Contents · 11 sections↓
- 01What is Self-Ask prompting?
- 02How Self-Ask works
- 03Worked example: two multi-hop questions
- 04Plug in search for the follow-ups
- 05Auto-CoT: chain-of-thought examples without writing them
- 06Decomposed prompting: a handler per sub-task
- 07Decomposition vs chain of thought: what is the difference?
- 08When to use which (and when not to)
- 09Common mistakes
- 10Frequently asked questions
- 11Next steps
Self-Ask prompting makes the model ask and answer its own follow-up questions before it answers the main one. It targets multi-hop questions, where the answer depends on combining two or more facts, and it gives you a clean place to plug in search. This guide covers Self-Ask, Auto-CoT (automatically built chain-of-thought examples) and decomposed prompting, with real outputs, a small search loop in Python, and an honest note on what reasoning models and tool calling have replaced.
What is Self-Ask prompting?
Self-ask prompting is a prompting technique in which the model breaks a complex question into simpler follow-up questions, answers each one, and then combines the answers into the final answer. In the prompt format, the model writes "Follow up:" questions, answers each one with "Intermediate answer:", and only then writes "So the final answer is:". It was introduced to close the compositionality gap: models often know each fact but fail to combine them. Because each follow-up is a standalone question, you can send it to a search engine instead of the model.
Key takeaways:
Use it for multi-hop questions: "the capital of the country that hosted X", "who was in office when Y happened".
The format is the point. One worked example teaches it; the labeled lines make the output easy to parse.
Each follow-up is a search query. That is Self-Ask's lasting value, and the bridge to tool-calling agents.
Reasoning models decompose on their own. With them, use Self-Ask when you need retrieval or an auditable chain, not to make the model think.
[02]
How Self-Ask works
Measuring and Narrowing the Compositionality Gap in Language Models (Press, Zhang, Min, Schmidt, Smith and Lewis, 2022) measured how often models answer every sub-question correctly but still get the combined question wrong. In the GPT-3 family, that gap did not shrink as models grew. Chain-of-thought narrowed it; Self-Ask narrowed it further by making the sub-questions explicit. The paper also showed that answering the follow-ups with a search engine improved accuracy again.
The prompt is one or more worked examples in a fixed format, followed by the new question:
Answer the question by asking and answering follow-up questions first. Use exactly this format.

Question: Who was president of the U.S. when superconductivity was discovered?
Are follow up questions needed here: Yes.
Follow up: When was superconductivity discovered?
Intermediate answer: Superconductivity was discovered in 1911.
Follow up: Who was president of the U.S. in 1911?
Intermediate answer: William Howard Taft.
So the final answer is: William Howard Taft

Question: {question}
Are follow up questions needed here:
The example question is the one used in the paper. Keep one or two examples; more adds tokens without teaching anything new.
[03]
Worked example: two multi-hop questions
Both questions were asked directly, several times, with the model's reasoning at its lowest level and "Reply with just the answer" appended.
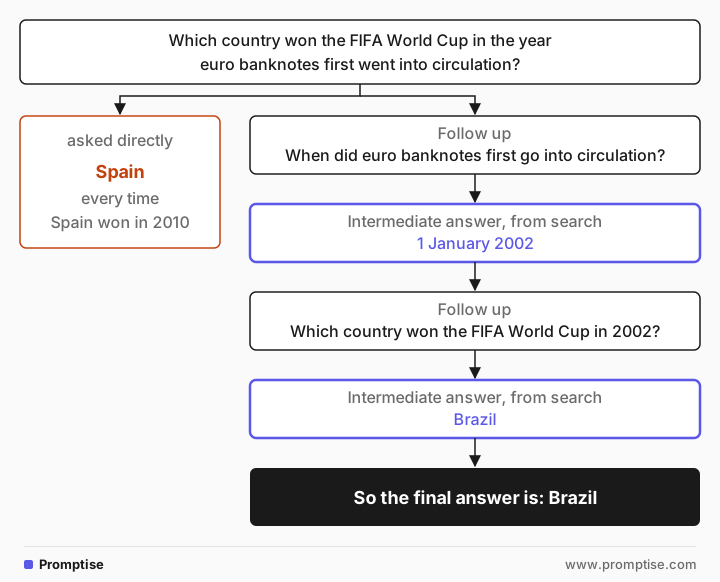
Which country won the FIFA World Cup in the year euro banknotes first went into circulation?
['Spain', 'Spain', 'Spain']

Which river flows through the capital of the country that hosted the 1992 Winter Olympics?
['Arly', 'France', 'Arly']
Both wrong. Euro banknotes entered circulation in 2002, and Brazil won that year (Spain won in 2010). The 1992 Winter Olympics were in Albertville, France; the capital is Paris, on the Seine. The Arly flows through Albertville: the model skipped the "capital" hop.
With the Self-Ask prompt, same model and setting:
Question: Which river flows through the capital of the country that hosted the 1992 Winter Olympics?
Are follow up questions needed here: Yes.
Follow up: Which country hosted the 1992 Winter Olympics?
Intermediate answer: France (the 1992 Winter Olympics were held in Albertville, France).
Follow up: What is the capital of France?
Intermediate answer: Paris.
Follow up: Which river flows through Paris?
Intermediate answer: The Seine.
So the final answer is: The Seine
The euro question came back as two follow-ups (2002, then the 2002 winner) and the answer Brazil. Every hop is visible, so a wrong one is easy to spot.
[04]
Plug in search for the follow-ups
The model's own intermediate answers are only as good as its memory. For facts that change or are obscure, answer each follow-up from a search API or your own retrieval, and let the model only write questions and the final answer. The loop below asks for one line at a time:
import re

PROMPT = open("self_ask_prompt.txt").read()  # the prompt above


def search(question: str) -> str:
    """Your search API or retrieval step goes here. This demo uses a separate, isolated model call."""
    return ask(f"Answer in one short sentence: {question}", effort="low")


def self_ask(question: str, max_hops: int = 4) -> str:
    transcript = PROMPT.replace("{question}", question) + " Yes.\n"
    for _ in range(max_hops):
        step = ask(transcript + "\n\n(Write only the next line: either 'Follow up: ...' or 'So the final answer is: ...')")
        line = step.strip().splitlines()[0]
        if line.startswith("So the final answer is:"):
            return line
        follow_up = re.sub(r"^Follow up:\s*", "", line)
        answer = search(follow_up)
        print(f"Follow up: {follow_up}\nIntermediate answer: {answer}")
        transcript += f"Follow up: {follow_up}\nIntermediate answer: {answer}\n"
    return "No answer within the hop limit."
ask(prompt, effort="minimal") is a one-line wrapper around your chat API that returns the text. Output for the euro question:
Follow up: When did euro banknotes first go into circulation?
Intermediate answer: Euro banknotes first went into circulation on 1 January 2002.
Follow up: Which country won the FIFA World Cup in 2002?
Intermediate answer: Brazil won the 2002 FIFA World Cup.
So the final answer is: Brazil
The hop limit matters: without it, a confused model can keep asking. In production, this loop is usually written with tool calling instead of text parsing: the model calls a search tool, and your code returns the result. That is the ReAct pattern; see building a ReAct agent loop from scratch.
[05]
Auto-CoT: chain-of-thought examples without writing them
Few-shot chain-of-thought works well, but someone has to write the worked examples. Automatic Chain of Thought Prompting in Large Language Models (Zhang, Zhang, Li and Smola, 2022) generates them instead:
Cluster your task's questions by meaning (the paper used Sentence-BERT embeddings and k-means).
From each cluster, pick a representative question.
Generate its reasoning chain with zero-shot "Let's think step by step", and keep it if it passes simple heuristics (short question, few reasoning steps).
Use those question-plus-chain pairs as the few-shot examples.
The paper's main finding is that diversity matters: generated chains contain mistakes, and examples drawn from different clusters keep one mistake from being copied across similar questions. On ten reasoning benchmarks with GPT-3, Auto-CoT matched or beat hand-written chain-of-thought examples.
Today, Auto-CoT matters less for reasoning itself: current models reason without demonstrations, and reasoning models do it internally. The useful part is the selection idea. If you keep few-shot examples for format or house style, pick them from different clusters of real inputs, not from the first five tickets in the log. To decide which inputs deserve a hand-checked example, see active prompting; for how to format examples, see few-shot examples the right way.
[06]
Decomposed prompting: a handler per sub-task
Decomposed Prompting: A Modular Approach for Solving Complex Tasks (Khot et al., 2022) goes one step further than Self-Ask. A decomposer prompt splits the task into sub-tasks, and each sub-task goes to its own handler: another prompt, a retrieval call, or plain code. Each handler can be tested and improved on its own.
That design is now the normal shape of LLM applications: an orchestrating prompt and a set of tools. When the sub-tasks are fixed and known in advance, write them as code steps and skip the decomposer call. When they are not, let the model choose tools.
If your prompts live in Python, Promptise Foundry has a decompose strategy that adds the identify, solve and combine instructions to any prompt function and returns only the final answer:
from promptise.prompts import prompt
from promptise.prompts.strategies import decompose

@prompt(model="openai:gpt-5-mini")
async def plan(task: str) -> str:
    """Plan the migration: {task}"""

answer = await plan.with_strategy(decompose)("Move 40 cron jobs from a VM to a managed scheduler")
That is single-call decomposition. For Self-Ask with search, keep the loop above or use tool calling.
[07]
Decomposition vs chain of thought: what is the difference?
Chain of thought asks the model to reason step by step and write the steps out, in one pass, before the answer. Decomposition splits the problem into separate sub-questions first and answers each one on its own, often in its own call, with search or with code, before it combines the results. Chain of thought shows the reasoning. Decomposition gives each step a place where you can check it or replace it.
Chain of thought | Decomposition (Self-Ask, least-to-most, decomposed prompting) | |
|---|---|---|
What the model writes | Free-form reasoning steps | Explicit sub-questions and their answers |
Calls | One | One or more; each sub-question can be its own call |
Facts come from | The model's memory | Memory, search, a database or code, per sub-question |
Easy to parse and test | No, the steps are prose | Yes, each sub-answer is a labeled unit |
Best for | Math, logic and reasoning on information in the prompt | Multi-hop questions, workflows with distinct steps, answers that need retrieval |
The two combine: a decomposed step can use chain of thought inside it. With reasoning models, chain of thought happens on its own, so decomposition is the part you still choose to add, for retrieval, auditability or testable steps. For more on chain of thought, see chain-of-thought for beginners.
[08]
When to use which (and when not to)
Situation | Use | Note |
|---|---|---|
Multi-hop factual question, facts may be stale or obscure | Self-Ask with search, or a tool-calling agent | The model writes queries; retrieval supplies facts |
Multi-hop question, a reasoning model, stable facts | Ask directly with reasoning on | At low effort, the model answered both questions above correctly |
Fixed multi-step workflow | Code steps (decomposed prompting) | Each step is testable |
Need a few-shot set for a recurring task | Auto-CoT-style diverse selection, then human review | Diversity over volume |
Single-fact lookup | None | Follow-ups add cost only |
[09]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Format described, not shown | The model invents its own labels and parsing breaks | Include one complete worked example |
Trusting intermediate answers from memory | The hops are visible but can still be wrong | Answer follow-ups with search or your data |
No hop limit | Loops on confusing questions | Cap at 3 to 5 follow-ups |
Many near-identical examples | One wrong chain is copied to similar questions | Pick examples from different clusters |
Self-Ask on simple questions | Extra calls for no gain | Route only multi-hop questions to it |
[10]
Frequently asked questions
Is Self-Ask the same as chain-of-thought?
It is a structured kind of chain-of-thought. Instead of free reasoning, the model writes explicit sub-questions and answers. The structure makes the steps parseable, which is what lets you replace the answers with search results.
What is the difference between decomposition and chain of thought?
Chain of thought writes the reasoning steps in one pass from the model's memory. Decomposition splits the question into sub-questions and answers each one separately, which lets you send a sub-question to search, check it in code or test it on its own. Self-Ask is decomposition written in a chain-of-thought style.
Do I still need Self-Ask with reasoning models?
Mostly not for accuracy on stable facts: at low reasoning effort the model answered both example questions correctly. Self-Ask is still useful when facts must come from search or your own data, and when you want an auditable chain of sub-answers.
What is the difference between Self-Ask and least-to-most prompting?
Both decompose. Self-Ask targets multi-hop facts and pairs naturally with search. Least-to-most targets problems harder than the examples, by planning sub-problems first and solving them in order.
Is Auto-CoT worth implementing today?
As a full pipeline, rarely; current models don't need generated reasoning demos. Its selection idea is worth keeping: build few-shot sets from diverse clusters of real inputs and review the chains before use.
How is this related to ReAct agents?
Self-Ask with search is a narrow, early version of the ReAct pattern: reason, call a tool, read the result, continue. ReAct generalizes it to any tool, usually with native tool calling.
[11]
Next steps
The basics first: chain-of-thought prompting for beginners.
Sub-problems in order: self-consistency and least-to-most.
Choosing examples: few-shot examples the right way and active prompting.
Tools instead of text parsing: ReAct agent loops from scratch.
Check what comes back: verification loops with CoVe and SelfCheckGPT.