Contents · 7 sections↓
Active prompting decides which few-shot examples are worth a human's time. Instead of hand-labeling random inputs, you ask the model the same question several times, measure how much its answers disagree, and annotate only the inputs it is most unsure about. This guide is for developers building classifiers, extractors or reasoning prompts who have many unlabeled inputs and little labeling time. It covers the method from the paper, a runnable version on support-ticket triage with real output, and what it still adds now that models reason on their own.
What is active prompting?
Active prompting (Active-Prompt) selects few-shot examples by uncertainty. For each unlabeled input in a pool, sample several answers from the model and compute an uncertainty score, such as the share of distinct answers. A person then writes a worked answer for the most uncertain inputs, and those become the prompt's examples. It is active learning applied to choosing demonstrations instead of training data.
Key takeaways:
Label where the model is torn, not where it is already consistent. Two well-chosen examples can do more than ten random ones.
Disagreement is simple: distinct answers divided by the number of samples.
Uncertainty misses confident disagreements with your policy. Review a sample of the confident answers too.
With reasoning models, the gain shifts from teaching reasoning to teaching your labels, edge cases and house rules.
[02]
How active prompting works
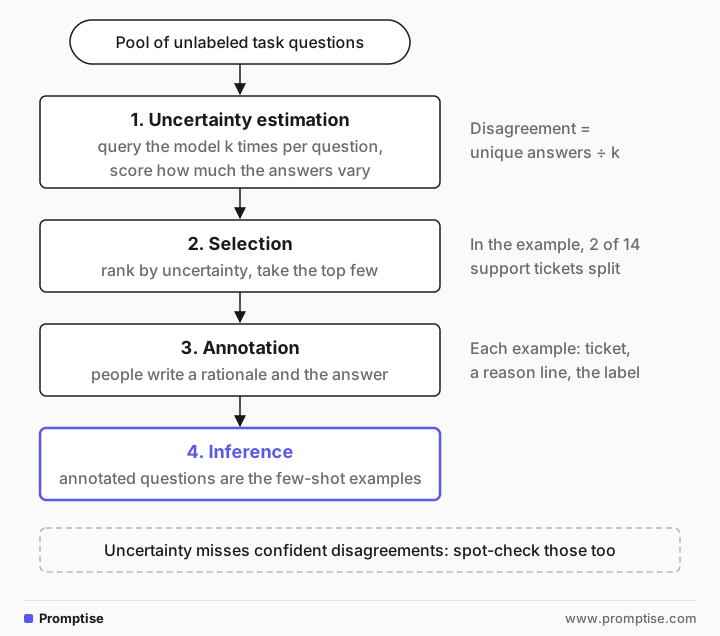
Active Prompting with Chain-of-Thought for Large Language Models (Diao, Wang, Lin, Pan, Liu and Zhang, 2023) starts from the observation that chain-of-thought examples are usually a fixed, hand-picked set, which is not necessarily the most useful set for a task. The method has four steps:
Uncertainty estimation. Query the model k times on each question in a pool of unlabeled task questions (k = 10 in the main experiments) and score how much the answers vary.
Selection. Rank the questions by uncertainty and take the top few.
Annotation. People write a chain-of-thought rationale and the answer for each selected question.
Inference. Use those annotated questions as the few-shot examples for the task.
The paper compared several uncertainty metrics. Disagreement (the number of unique answers divided by k) and entropy worked best and became the main metrics. Variance kept up on two arithmetic datasets but fell behind on GSM8K. Asking the model to rate its own confidence did not work, because models tend to be over-confident. Across eight complex reasoning benchmarks, Active-Prompt beat the baseline chain-of-thought methods it was compared with.
[03]
Worked example: triaging support tickets
The task: label each support ticket as billing, bug, account_access, feature_request or shipping. The pool is 14 unlabeled tickets. The code samples five labels per ticket and computes disagreement:
from collections import Counter

LABELS = "billing, bug, account_access, feature_request, shipping"


def classify_prompt(ticket: str, examples: str = "") -> str:
    return f"Classify the support ticket into one of: {LABELS}.\n{examples}\nTicket: {ticket}\nReply with the label only."


def uncertainty(ticket: str, examples: str = "", k: int = 5) -> tuple[float, Counter]:
    votes = Counter(a.strip().lower() for a in ask(classify_prompt(ticket, examples), n=k))
    return len(votes) / k, votes  # the paper's "disagreement": distinct answers / k


scored = sorted(((*uncertainty(t), t) for t in POOL), key=lambda x: -x[0])
for u, votes, t in scored:
    print(f"{u:.1f}  {dict(votes)}  {t}")
ask(prompt, n=k) returns k sampled completions at the model's lowest reasoning setting. The first eight tickets, mostly clear-cut, all came back unanimous (disagreement 0.2, the minimum for k = 5), including some that look ambiguous to a person:
0.2  {'billing': 5}  I upgraded to Pro but still see the free plan limits.
0.2  {'billing': 5}  The invoice PDF shows my old company name.
0.2  {'account_access': 5}  2FA codes never arrive by SMS.
…
The model was consistent where a person might hesitate. Six more tickets with mixed signals:
0.4  {'shipping': 2, 'bug': 3}  The package arrived but the dashboard still says 'in transit' and I can't activate the device.
0.4  {'billing': 3, 'feature_request': 2}  Your pricing page is confusing, I can't tell which plan includes SSO.
0.2  {'billing': 5}  I was billed after I cancelled, and now I can't log in to download my invoices.
0.2  {'bug': 5}  The app crashes when I try to update my credit card.
0.2  {'feature_request': 5}  Can you add PayPal? My card keeps getting declined.
0.2  {'account_access': 5}  I can't see the team workspace my admin invited me to.
Out of 14 tickets, two split the model. Those are the two to annotate. Most of the labeling budget would have gone to tickets the model already handles consistently.
Annotate the uncertain ones with a reason
Each annotation is the ticket, a one-line reason that states the rule, and the label your team wants:
Examples:
Ticket: The package arrived but the dashboard still says 'in transit' and I can't activate the device.
Reason: activation waits on the shipment record, so the shipping team fixes it.
Label: shipping

Ticket: Your pricing page is confusing, I can't tell which plan includes SSO.
Reason: questions about what a plan includes are billing questions; feature_request is only for things no plan offers.
Label: billing
The reason line is the useful part: it states the rule, which transfers to new tickets, instead of just a label for one ticket. That matches the paper's use of written rationales.
Check on new tickets
Two new tickets of the same kinds, five samples each, without and with the examples:
before 0.4  {'bug': 4, 'shipping': 1}  My order shows delivered but the device won't activate, it says the serial isn't registered yet.
after  0.2  {'shipping': 5}  My order shows delivered but the device won't activate, it says the serial isn't registered yet.
before 0.2  {'feature_request': 5}  Does the Team plan include audit logs? The comparison table doesn't say.
after  0.2  {'billing': 5}  Does the Team plan include audit logs? The comparison table doesn't say.
The first ticket went from split to unanimous and matches the team's rule. The second is the more important lesson: before the examples, the model was unanimous and, by your policy, wrong. Uncertainty sampling would never have flagged it. The annotated rule from a different ticket fixed it anyway. Uncertainty finds where the model is torn; it can't find where the model confidently disagrees with a policy it was never told. Spot-check a sample of confident answers as well.
[04]
When to use active prompting (and when not to)
Use it when:
You have a pool of real, unlabeled inputs and limited time to write examples.
Labels follow house rules the model can't guess: routing, policy categories, edge cases.
You maintain a few-shot set over time and want to know which example to add next.
Skip it when:
Zero-shot output is already right on your test set. Examples add tokens to every call.
You have plenty of labeled data. Pick examples by similarity to the input, or fine-tune.
Each answer is long free text, where "distinct answers" is meaningless. Group by meaning first, as in semantic entropy.
What changes with reasoning models
The paper used active prompting to pick chain-of-thought examples for math and reasoning benchmarks. Reasoning models gain little from worked reasoning examples, since they reason internally, so that use has faded. The selection idea has not: it is a cheap way to find where your instructions are ambiguous. In practice the output of active prompting is often a better instruction, not only a better example. The pricing-page reason above can go straight into the system prompt as a rule. Keep the examples for cases a rule can't express briefly.
Sampling costs little here: five one-word answers per ticket at the lowest reasoning setting, requested with n=5 in one call. Sample at a low setting even if production uses more reasoning, since you are looking for ambiguity in the task, not testing the production configuration.
[05]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Annotating random inputs | Most of the labels repeat what the model already does | Annotate the most uncertain inputs first |
Labels without a reason | The example teaches one case, not the rule | One reason line per example that states the rule |
Trusting unanimous answers | Consistent answers can still break your policy | Spot-check confident answers; add rules for misses |
Asking the model to rate its confidence | Models tend to be over-confident; the paper found this metric weak | Measure disagreement across samples |
Temperature 0 when sampling | All samples match, so nothing looks uncertain | Default sampling for the uncertainty pass |
Never re-running the pass | New example sets create new uncertain areas | Re-score the pool after each change |
[06]
Frequently asked questions
How many samples per input do I need?
The paper used 10 in its main experiments and found gains leveled off around there. For a short label, 5 is enough to separate unanimous from split inputs, as in the example. Larger k gives finer scores at a linear cost.
How big should the unlabeled pool be?
Big enough to contain the hard cases: a few hundred real inputs is a practical start. In the example, 14 tickets yielded 2 uncertain ones; real traffic will have more variety.
Is active prompting the same as Auto-CoT?
No. Auto-CoT builds examples automatically by clustering questions and letting the model write the rationales, with no human labels. Active prompting chooses which inputs a human should label. See Self-Ask and Auto-CoT.
Does this work for extraction or generation tasks?
For extraction with short fields, yes: compare the extracted values across samples. For generation, group samples by meaning before counting, or use a judge to score agreement. The principle is the same: spend human time where the model disagrees with itself.
How many examples should end up in the prompt?
As few as fix the observed confusions, often two to five. More examples cost tokens on every call and can bias the output toward the example labels; see few-shot examples the right way.
[07]
Next steps
Format and order your examples: few-shot examples the right way.
Generated examples instead of labeled ones: Self-Ask, Auto-CoT and decomposition.
Uncertainty for free-text answers: semantic entropy.
Measure the effect of each change: beginner eval loops.
Reasoning examples and when they help: chain-of-thought for beginners.
Improve the instruction itself: simple instruction tuning by iteration.