Contents · 6 sections↓
An LLM learned what it knows from what many people wrote. A fact stated on thousands of pages is learned well; a fact stated on a handful is learned poorly, and the model gives both in the same confident tone. This essay, part of the Mental Models learning path, explains the research on popularity and accuracy, how to predict which questions are risky, and what to do about the long tail. It includes a real example where the famous answers are right and the obscure ones are invented.
Why do LLMs get niche facts wrong?
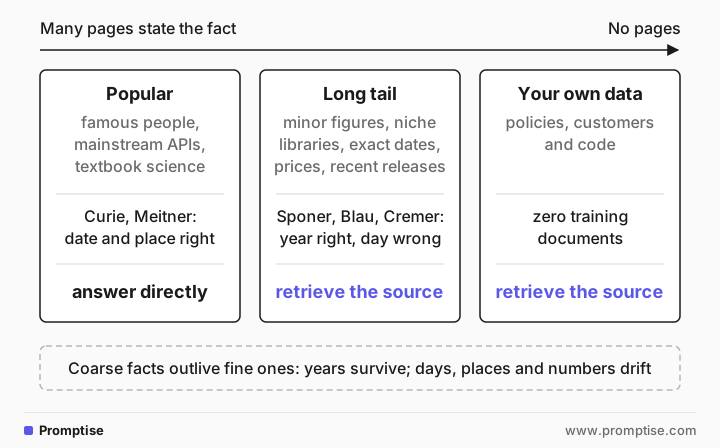
A model's accuracy on a factual question tracks how often the facts behind it appear in its training data. Popular facts appear across thousands of documents and are learned reliably. Long-tail facts, such as minor people, small companies, exact dates and your own internal data, appear rarely or never, so the model fills the gap with something plausible. Nothing in the answer tells you which case you are in. For long-tail questions, give the model the source.
Key takeaways:
Ask "how many pages say this?" That estimate predicts reliability better than how confident the answer sounds.
Coarse facts outlive fine ones. Years and countries survive; days, places and numbers drift.
Retrieval fixes the tail. Supplying the source matters far more for obscure facts than for popular ones.
Your company's data is the extreme tail: zero training documents.
[02]
Why it's true
Large Language Models Struggle to Learn Long-Tail Knowledge (Kandpal et al., ICML 2023) counted, for each question in benchmarks such as TriviaQA, how many pretraining documents mention the entities involved. Accuracy rose with that count, with both correlational and causal evidence, across model sizes up to 176B parameters. Bigger models did better on rare facts, but the authors estimated that scale alone would need many orders of magnitude to close the gap, and that retrieval reduces the dependence on pretraining frequency.
When Not to Trust Language Models (Mallen et al., ACL 2023) built PopQA, 14k questions about entities of varying popularity. Models struggled with less popular entities, and scaling did not meaningfully improve memorization of the tail. Retrieval-augmented models beat much larger unaided models, while unaided models stayed competitive on popular entities. The authors proposed adaptive retrieval: retrieve only when the question is about something unpopular.
The crowd metaphor is accurate in one more way: the model has no index of its sources. It can't tell you "only three pages said this" because it doesn't store pages; it stores what the pages had in common.
[03]
Example: famous and obscure scientists
Give the full date of birth (day, month, year) and place of birth of each of these physicists/chemists. One line each, no commentary:
Marie Curie
Lise Meitner
Hertha Sponer
Marietta Blau
Harriet Brooks
Erika Cremer
Clara Immerwahr
Hilde LeviMarie Curie — 7 November 1867, Warsaw, Congress Poland (then Russian Empire)
Lise Meitner — 7 November 1878, Vienna, Austria-Hungary
Hertha Sponer — 23 September 1895, Neisse (now Nysa), Prussian Silesia, German Empire
Marietta Blau — 28 July 1894, Vienna, Austria-Hungary
Harriet Brooks — 2 January 1876, Port Hope, Ontario, Canada
Erika Cremer — 23 June 1900, Berlin, German Empire
Clara Immerwahr — 21 June 1870, Polkendorf (now part of Świebodzin), Province of Brandenburg, Prussia
Hilde Levi — 7 November 1909, Copenhagen, DenmarkChecked against Wikidata: Curie and Meitner, the two famous names, are right. Every birth year is right. But Sponer was born on 1 September, Blau on 29 April, Brooks on 2 July in Exeter, Ontario, Cremer on 20 May in Munich, and Levi on 9 May in Frankfurt. Levi got the same "7 November" as the two famous lines above her. Immerwahr's date is right, her birthplace description wrong.
A prompt that allows uncertainty helps only partly:
… If you are not confident of the exact day and month, give only what you are sure of (for example just the year) and mark the line 'CHECK'. Leaving out a detail is better than guessing it.…
Hertha Sponer — 5 July 1895, Neunkirchen, Saarland, German Empire. CHECK …
Marietta Blau — 28 July 1894, Vienna, Austria-Hungary.
…
Erika Cremer — 23 January 1900, Erlangen, Kingdom of Bavaria, German Empire.
…It flagged four lines, but still gave exact dates instead of just years, and left two wrong lines unflagged. Sponer's birthplace changed between runs, from the correct Neisse to Neunkirchen. Results vary by model; the pattern of right-on-popular, wrong-on-rare is the stable part.
[04]
What it changes in practice
Estimate popularity before you trust. Would this fact appear on many independent pages? Famous people, mainstream APIs and textbook science, probably. Minor figures, niche libraries, recent releases, prices and anything about your organization, no.
Retrieve for the tail. Paste the source, connect search or a database, or give the model a lookup tool. Adaptive retrieval is a fine default: answer popular questions directly, ground everything else.
Use disagreement as a signal. When repeated samples disagree on a detail, as Sponer's birthplace did, the model is guessing. Verify that detail or drop it.
[05]
Frequently asked questions
How do LLMs learn facts?
They learn statistical patterns from training text. A fact repeated across many documents becomes a strong pattern; one mentioned rarely leaves a weak one. There's no separate fact database inside the model, which is why rare facts degrade into plausible guesses.
Does a bigger model fix long-tail errors?
It helps a little. Both Kandpal et al. and Mallen et al. found that scale improves popular facts much more than rare ones. Retrieval augmentation was the more effective fix for the tail.
Can I ask the model how sure it is?
You can, and it helps somewhat, but the model's self-reported confidence is not well matched to its accuracy on rare facts. Checking agreement across samples, or verifying against a source, is more reliable.
What counts as long-tail knowledge?
Facts that appear in few documents: lesser-known people and places, exact dates and figures, small projects, recent events after the training cutoff, and private data such as your policies, customers and code.
[06]
Next steps
LLMs as lossy compression: why exact wording fails even for popular sources.
LLM hallucinations: why they happen: quick checks for any answer.
Grounding LLM answers: give the model the right context.
Agentic RAG in Python: let an agent decide when to retrieve.
Verification loops: sample-agreement checks such as SelfCheckGPT.
Mental Models: How to Think with LLMs: the full learning path.