Contents · 8 sections↓
Chain-of-thought prompting asks the model to work through a problem in steps before giving the answer. It helps most on tasks with several dependent steps, such as date math, scheduling, pricing or multi-condition rules, where a one-shot answer skips a step and comes out wrong. This guide is for beginners. It shows a real scheduling question answered directly and step by step, and explains when reasoning models make the technique unnecessary.
What is chain-of-thought prompting?
Chain-of-thought (CoT) prompting gets the model to write out intermediate reasoning steps before its final answer, either by asking for steps or by showing worked examples. It was introduced in Chain-of-Thought Prompting Elicits Reasoning in Large Language Models (Wei et al., 2022), which used few-shot examples with written-out reasoning. Large Language Models are Zero-Shot Reasoners (Kojima et al., 2022) showed that simply adding "Let's think step by step" also helped on arithmetic and logic tasks.
Key takeaways:
It helps on multi-step problems, not on lookups or writing tasks.
Name the steps for your task instead of saying only "think step by step".
Put the final answer on a marked line so you or your code can find it.
Reasoning models already do this internally. With them, prompt for the steps you want to see, not for thinking itself.
[02]
How chain-of-thought works
A model writes its answer one token at a time. If it has to produce the answer in the first few words, it gets no room to work anything out. Writing the steps first means each later step can build on earlier ones that are already on the page: convert the time zones, then compare the ranges, then answer.
Reasoning models (OpenAI's o-series and GPT-5 family, Claude with extended thinking, and others) do this before they reply, in hidden or summarized reasoning. You control how much with a setting such as reasoning effort or a thinking budget. With those models, "think step by step" adds little. What still helps is telling the model which steps matter for your task and asking it to show them, so you can check its work.
[03]
Worked example: finding a meeting slot
Find a 1-hour meeting slot on Tuesday, November 10, 2026 that is inside working hours for all three people:
- Anna in Zurich, works 9:00-17:00 local time
- Ben in San Francisco, works 9:00-17:00 local time
- Chloe in Singapore, works 9:00-18:00 local time
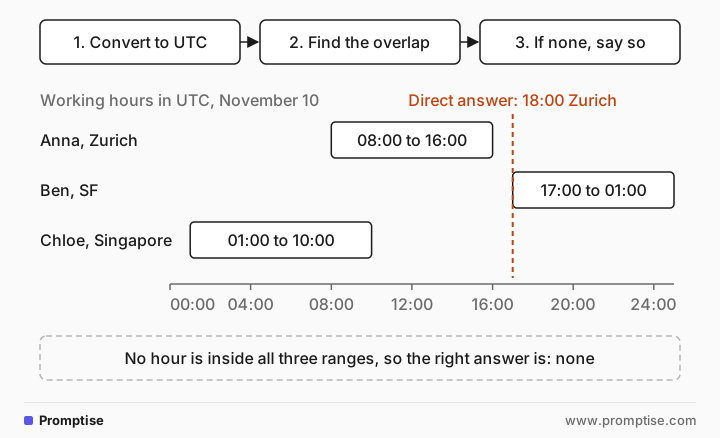
The correct answer: there is none. In UTC that day, Anna works 08:00 to 16:00, Ben 17:00 to 01:00 and Chloe 01:00 to 10:00. No hour overlaps all three.
Direct answer, minimal reasoning
With the model's reasoning set to its lowest level and "Answer in one line" appended:
Tuesday, November 10, 2026 — 18:00–19:00 CET (Zurich time)Wrong. 18:00 in Zurich is after Anna's day ends and 01:00 the next morning in Singapore.
Step-by-step prompt, same setting
<same question>

Work it out step by step before answering:
1. Convert each person's working hours to UTC for that date (check whether daylight saving time applies).
2. Find the overlap of all three ranges.
3. If there is no overlap, say so, and suggest the best two-person options.
Show the steps briefly, then put the answer on the last line, starting with "Answer:".
The output (trimmed):
Step 1 — time zones and DST on 2026-11-10
- Zurich (Anna): … On 2026-11-10 Europe is on standard time (CET, UTC+1) because DST ended the last Sunday in October. So Anna's 09:00–17:00 CET = 08:00–16:00 UTC.
- San Francisco (Ben): … On 2026-11-10 the US is on standard time (PST, UTC−8) because DST ended first Sunday in November. So Ben's 09:00–17:00 PST = 17:00–01:00 UTC (next day).
- Singapore (Chloe): … UTC+8 year-round. Chloe's 09:00–18:00 SGT = 01:00–10:00 UTC.

Step 2 — convert ranges to UTC and find overlap
- Intersection of Anna (08:00–16:00) and Chloe (01:00–10:00) = 08:00–10:00 UTC.
- Intersect that with Ben (17:00–01:00) … There is no UTC time on Nov 10 that is simultaneously within Ben's working hours and the others' working hours.
…
Answer: No 1-hour slot on 2026-11-10 fits all three. Best two-person option for all-day participants is Anna and Chloe: pick 08:00–09:00 UTC or 09:00–10:00 UTC (Zurich 09:00–11:00, Singapore 16:00–18:00).
Correct, including the daylight saving check that a direct answer skips. The steps named in the prompt (convert, intersect, handle "none") are the steps where people get this wrong too. The full output was long and included a self-correction ("Wait: …"), which is normal for visible reasoning; the "Answer:" line keeps the result easy to find.
Same direct prompt, more reasoning
With reasoning effort raised to medium and the original one-line prompt, no steps requested:
No 1-hour slot exists on Tuesday 2026-11-10 in Zurich time that fits all three: Anna 09:00–17:00 CET, Ben 09:00–17:00 PST = 18:00–02:00 CET, Chloe 09:00–18:00 SGT = 02:00–11:00 CET (no overlap).Also correct. The model did the steps internally and used more output tokens to do it. That is the trade-off: either ask for visible steps, or let a reasoning model think and pay for the hidden tokens. Results vary by model and setting.
[04]
When to use step-by-step prompting (and when not to)
Use it for:
Date, time and money calculations: prorating, deadlines, invoices, time zones.
Rules with several conditions: "is this order eligible for a refund?"
Any answer you want to audit: the steps show where it went wrong.
Skip it for:
Lookups and extraction ("what's the order number?"). Steps add length, not accuracy.
Writing and summarizing. Ask for an outline first instead, if anything.
Reasoning models on routine tasks, where internal reasoning already covers it.
For exact arithmetic over many numbers, don't rely on the model's steps. Have it write the calculation as code or give it a calculator tool; see program-of-thought and PAL.
[05]
A reusable template
<task>

Work it out before answering:
1. <first step specific to this task>
2. <second step>
3. <how to handle the "no answer" or edge case>
Keep the steps short. Put the final answer on the last line, starting with "Answer:".
In code, read only the line that starts with Answer:. If a person reads the output, keep the steps; they make the answer checkable.
[06]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Only "think step by step" | The model picks its own steps and may skip the key one | Name the steps that matter |
Steps on simple lookups | Longer, slower, no more accurate | Ask directly |
Final answer buried in the reasoning | Hard to parse or skim | "Answer:" on the last line |
Trusting the steps because they look careful | Reasoning can be fluent and wrong | Check the key step (here, the UTC offsets) |
Asking a reasoning model to "think harder" in text | Thinking is controlled by a setting | Raise reasoning effort or the thinking budget |
[07]
Frequently asked questions
Is chain-of-thought still useful with reasoning models?
Less as a thinking trick, more as a way to see and check the work. Reasoning models think before answering, so "think step by step" adds little. Asking for specific visible steps still helps when you need to audit the result.
Do the written steps show how the model really reached the answer?
Not necessarily. Written reasoning is a useful check, but it is not a guaranteed record of the model's internal process. Verify important answers independently.
Does chain-of-thought cost more?
Yes. Visible steps are output tokens, which are usually the expensive ones. Reasoning models charge for hidden reasoning tokens too. Use steps where errors are likely.
What's the difference between this and self-consistency?
Self-consistency samples several step-by-step answers and takes the most common final answer. It is more reliable and more expensive. See chain of thought evolved: self-consistency and least-to-most.
Should I show worked examples instead?
For a recurring task type, one or two worked examples with steps can teach the exact procedure you want, as in the original CoT paper. See few-shot examples.
[08]
Next steps
Previous in the path: role prompting.
Advanced variants: self-consistency and least-to-most.
Exact math with code: program-of-thought and PAL.
Back to the pillar: what is prompt engineering?