Contents · 10 sections↓
- 01How do you write a good long-context prompt?
- 02Why long prompts fail
- 03Where to put documents, instructions and the question
- 04How to structure the documents
- 05Worked example: a policy that was amended
- 06Quote first, then answer
- 07Retrieval vs stuffing: when to send everything
- 08Common mistakes
- 09Frequently asked questions
- 10Next steps
Long-context prompting is how you write a prompt that contains a lot of material, such as contracts, policies, transcripts or a codebase, so the model finds and uses the right parts. Big context windows let you paste everything, but the model can still miss a detail, mix an old rule with a new one, or give an answer you can't trace. This guide covers the tactics that help most: where to put documents and instructions, how to structure them, quoting before answering, and when to retrieve instead of stuffing.
How do you write a good long-context prompt?
Put the long material first, wrapped in tags with an id, date and title per document. Put the instructions and the question after it (some providers also recommend repeating key instructions before it). Tell the model how to resolve conflicts, ask it to quote the relevant passages before answering, and require document ids in the answer. If most of the material is irrelevant to each question, retrieve the relevant parts instead of sending everything.
Key takeaways:
Documents first, question last for long inputs.
One tag per document, with metadata the model needs to reason (id, date, source).
Quote, then answer. It focuses the model and gives you something to check.
State conflict rules: "the later date wins", "the contract overrides the FAQ".
Long context is not free. Every token is billed and adds latency; retrieve when you can.
[02]
Why long prompts fail
Models don't use every part of a long input equally well. Lost in the Middle (Liu et al., 2023, TACL) found that performance on multi-document QA was often highest when the relevant information was at the beginning or end of the context and dropped when it was in the middle. Newer models do better on simple retrieval tests, but OpenAI's GPT-4.1 prompting guide still notes that performance can degrade when many items must be retrieved or the task needs reasoning over the whole context.
Three failure patterns show up in practice:
Missed detail: the one sentence that matters is buried in page 30.
Blended rules: the model combines an old rule and its amendment into something neither says.
Uncheckable answers: the answer may be right, but you can't tell which document it came from.
The tactics below target these directly. For techniques that shrink the context itself (LLMLingua, selective context, reordering), see prompt compression and lost-in-the-middle.
[03]
Where to put documents, instructions and the question
Provider guidance agrees on the main point and differs on a detail:
Anthropic's prompting best practices say to put long documents at the top, above the query, instructions and examples, and report that queries at the end "can improve response quality by up to 30 percent in tests", especially with complex multi-document inputs.
OpenAI's GPT-4.1 guide recommends placing instructions at both the beginning and the end of long context; if only once, above the context.
A layout that satisfies both:
<short role and task statement, 1-2 lines>

<documents>
  <doc id="..." date="..." title="...">...</doc>
  ...
</documents>

<instructions: conflict rules, quoting, output format>
Question: <the question>[04]
How to structure the documents
Wrap each document in its own tag and put the facts the model needs to reason about in attributes. OpenAI's guide reports XML-style tags such as <doc id='1' title='The Fox'> worked well for large document sets and JSON worked worst. Anthropic suggests <document> tags with <source> and other metadata.
The metadata is not decoration. If documents can amend each other, the model needs dates. If sources have different authority, the model needs the source type. Then say how to use them:
- Policies can amend older ones. When two documents conflict, the one with the later date wins.
- The signed contract overrides the help center.[05]
Worked example: a policy that was amended
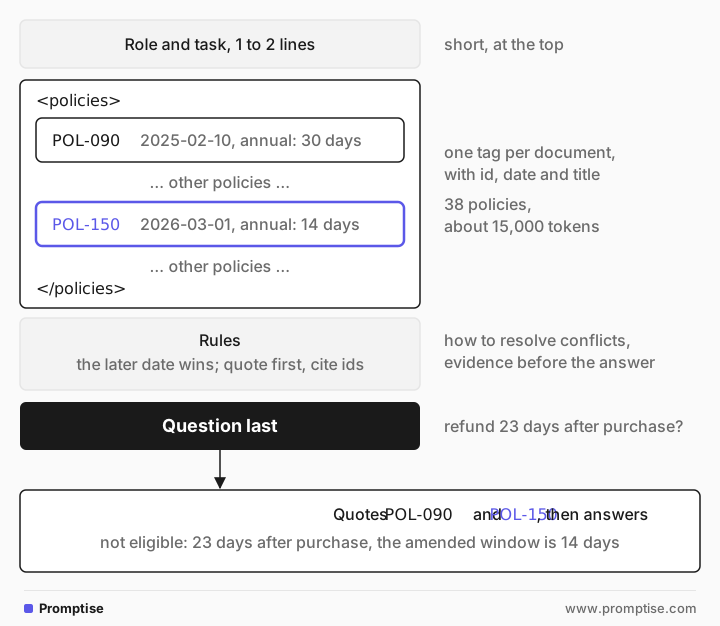
The prompt contained 38 support policies, about 13,000 words and 15,000 tokens. An early policy says annual plans can be refunded within 30 days. An amendment in the middle of the set, dated a year later, changes that to 14 days. The question:
A customer bought an annual plan on 2026-04-02 and asks for a refund on 2026-04-25. Are they eligible?The correct answer is no: the request is 23 days after purchase, and the amended window is 14 days.
Unstructured: question first, policies pasted below
A customer bought an annual plan on 2026-04-02 and asks for a refund on 2026-04-25. Are they eligible?

Here are our policies:

Refunds
Monthly plans can be refunded within 14 days ...
...
The model's answer (trimmed):
No — they are not eligible for a full refund under the current policy.

Reason:
…
- Amendment effective 2026-03-01 (Amendment to POL-090) changed annual-plan refund window to 14 days from purchase.
- 14 days after 2026-04-02 is 2026-04-16, so the request on 2026-04-25 is outside the 14-day window.
- The Refunds policy also says refunds are prorated after the first 7 days, but that only applies within the allowed refund timeframe. …

If you want to offer anything beyond policy, that would require a written exception approved by a team lead and logged in the CRM. …
The verdict is right, and at 15,000 tokens this model found the amendment without help. But nothing in the answer can be checked automatically: it names no document ids for the proration rule or the exception process, so a support agent has to search the policies to confirm them. On longer or messier inputs, an answer you can't check is also one you can't catch when it's wrong.
Structured: tagged documents first, rules and question last
<policies>
<doc id="POL-090" date="2025-02-10" title="Refunds">
Monthly plans can be refunded within 14 days of a charge. Annual plans can be refunded within 30 days ...
</doc>
...
<doc id="POL-150" date="2026-03-01" title="Amendment to POL-090">
Effective 2026-03-01, annual plans can be refunded within 14 days of the purchase date, not 30. ...
</doc>
...
</policies>

Answer the support question using only the policies above.
- Policies can amend older ones. When two documents conflict, the one with the later date wins.
- First, quote every passage that bears on the question, with its doc id and date.
- Then answer in 1-2 sentences, citing the doc ids you relied on.

Question: A customer bought an annual plan on 2026-04-02 and asks for a refund on 2026-04-25. Are they eligible?- "Annual plans can be refunded within 30 days of the purchase date." — POL-090 (2025-02-10)
- "Monthly plans can be refunded within 14 days of a charge." — POL-090 (2025-02-10)
- "Effective 2026-03-01, annual plans can be refunded within 14 days of the purchase date, not 30. Monthly plan refunds are unchanged." — POL-150 (2026-03-01)
[Answer]
No — the 2026-03-01 amendment (POL-150) shortens annual-plan refund eligibility to 14 days, so an annual purchase on 2026-04-02 would only be refundable through 2026-04-16; the 2026-04-25 request is outside that window (POL-150; POL-090).Same verdict, but now the evidence is visible: the old rule, the amendment, and which one wins. You can check the quotes against the source in code (exact substring match) before showing the answer. Both prompts used about the same number of input tokens. Results vary by model and by how long and noisy the input is.
[06]
Quote first, then answer
Asking for relevant quotes before the answer is one of Anthropic's documented long-context tips. It makes the model locate the evidence before it commits to a conclusion, and it gives you a cheap automatic check:
import re

def quotes_are_real(answer: str, docs: dict[str, str]) -> bool:
    """Every quoted passage must appear verbatim in one of the documents."""
    quotes = re.findall(r'"([^"]{20,})"', answer)
    return bool(quotes) and all(
        any(q.rstrip(". ") in text for text in docs.values()) for q in quotes
    )
On the answer above it returns True. Change "30 days" to "45 days" in the answer and it returns False.
If a quote isn't in the documents, retry or flag the answer for review. A stricter version also checks that each quote comes from the document id it cites.
[07]
Retrieval vs stuffing: when to send everything
Retrieval Augmented Generation or Long-Context LLMs? (Li et al., 2024, EMNLP industry track) compared the two and found that long-context models, when resourced sufficiently, outperformed RAG on average, while RAG's much lower cost remained its advantage. Their Self-Route method lets the model decide per query whether retrieved chunks are enough and falls back to the full context only when they aren't.
Situation | Send everything | Retrieve first |
|---|---|---|
Material fits comfortably and is mostly relevant (one contract, one transcript) | Yes | |
The question needs the whole document (summarize, compare all sections) | Yes | |
Large corpus, each question touches a few documents | | Yes | |
High volume or tight latency budget | | Yes | |
Same documents reused across many questions | Yes, with prompt caching | Or retrieve |
Prompt caching changes the math for repeated context: providers charge less for a cached prefix, which is another reason to keep documents first and the variable question last. In the same policy example, retrieving the top three documents cut input from about 15,900 to 1,400 tokens with the same answer; the compression guide shows that run.
[08]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Question at the top, documents below | Instructions get far from where the model answers | Documents first; question and rules last (optionally repeat rules at the top) |
One undifferentiated blob of text | The model can't tell where documents start, or which is newer | One tag per document with id, date, source |
No conflict rule | Old and new rules get blended | State which source or date wins |
Answers without citations | You can't verify or debug | Quote first, cite ids, check quotes in code |
Stuffing a large corpus for every question | High cost and latency, more distractors | Retrieve, or route between retrieval and full context |
JSON arrays for many long documents | Reported to work worse than tag formats | Use XML-style tags |
[09]
Frequently asked questions
Should the question go before or after a long document?
After, in most cases. Anthropic recommends documents at the top and the query at the end. OpenAI recommends instructions at both the beginning and end of long context. Putting the question last and optionally a one-line task statement first satisfies both.
Do large context windows make RAG unnecessary?
No. Long context can match or beat retrieval on quality when the budget allows, but it costs more per query and adds latency. For large corpora or high volume, retrieve first, and send full documents when the question really needs them.
What tags should I use for documents?
Any consistent XML-style tags work: <doc id="..." title="..."> or <document> with <source> and <document_content>. Include the metadata the model must reason about, such as dates and source type. Avoid large JSON arrays of documents.
How do I stop the model from mixing old and new versions of a rule?
Give each document a date or version, state the precedence rule explicitly, and ask the model to quote the passages it relies on. Better still, remove superseded versions before they reach the prompt.
What is lost in the middle?
A finding by Liu et al. (2023) that models used information at the start and end of a long context better than information in the middle. Mitigations include putting the most relevant material at the edges and sending less. See the compression guide.
[10]
Next steps
Shrink the context itself: prompt compression and lost-in-the-middle.
Grounding basics: give the model the right context.
A first retrieval pipeline: RAG zero to one.
Long-running agents: context engineering for AI agents.
Retrieval as an agent tool: agentic RAG in Python.