Contents · 11 sections↓
- 01What is a self-verification loop in an LLM?
- 02How Chain-of-Verification works: the CoVe fact-check workflow
- 03How SelfCheckGPT works
- 04A note on "draft-then-verify"
- 05Worked example: languages created at Bell Labs
- 06Other verification passes: self-refutation and bidirectional inference
- 07What changes with reasoning models
- 08When to use which (and when not to)
- 09Common mistakes
- 10Frequently asked questions
- 11Next steps
A verification loop checks a model's draft before you use it. Chain-of-Verification (CoVe) has the model write fact-checking questions about its own draft, answer them separately, and revise. SelfCheckGPT samples the answer several times and flags claims the samples don't agree on. This guide is for developers who need fewer hallucinated facts in lists, summaries and answers. It shows both methods on a real example, including three versions of the CoVe prompt and what went wrong in the first two.
What is a self-verification loop in an LLM?
A self-verification loop (or verification loop) makes the model check its own draft before you use it: draft, check, then revise or flag. The check can be the model answering targeted questions about its own claims (Chain-of-Verification), comparing the draft against independent samples (SelfCheckGPT), or comparing it against a trusted source. The loop costs extra calls and catches some, not all, hallucinated facts.
Key takeaways:
Ask open questions, not yes/no. "Where was X created?" catches errors that "Was X created at Y?" waves through.
Answer each check on its own, without the draft in context, and make every question self-contained.
Disagreement across samples is a cheap hallucination flag; agreement is not proof.
The strongest check is a source: search or your own data, not the model's memory.
[02]
How Chain-of-Verification works: the CoVe fact-check workflow
Chain-of-Verification Reduces Hallucination in Large Language Models (Dhuliawala, Komeili, Xu, Raileanu, Li, Celikyilmaz and Weston, 2023) uses four steps:
Draft an initial response.
Plan verification questions that fact-check the draft.
Execute the verifications: answer each question independently, so the answers are not biased by the draft or by each other.
Generate the final verified response from the draft and the check results.
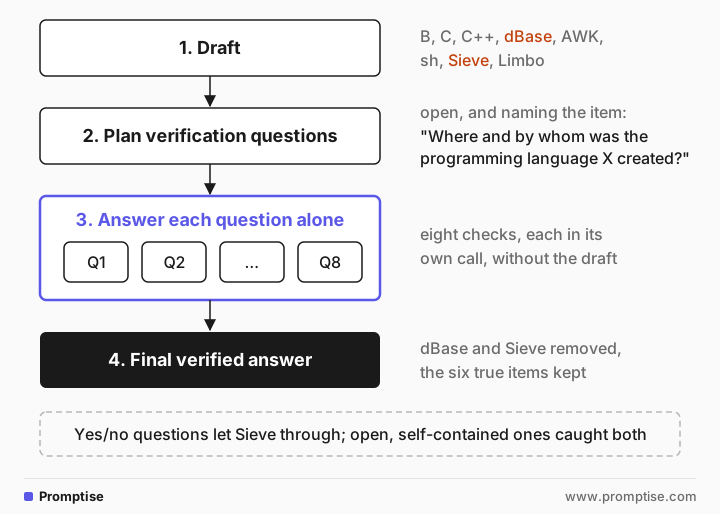
As a prompt engineering workflow, that is four prompts: one that writes the draft, one that turns its claims into fact-check questions, one call per question that answers it without the draft, and one that rewrites the draft from the answers. The worked example below builds exactly that. The paper compared running these steps in one prompt ("joint") with separate prompts. The "factored" versions, where each verification question gets its own call, performed better across its tasks: Wikidata list questions, closed-book MultiSpanQA and long-form biographies. It also found that open verification questions beat yes/no questions, because the model tends to agree with whatever fact a yes/no question contains.
[03]
How SelfCheckGPT works
SelfCheckGPT: Zero-Resource Black-Box Hallucination Detection for Generative Large Language Models (Manakul, Liusie and Gales, 2023) needs no database and no access to token probabilities. The idea: if a model knows a fact, samples will repeat it; if it made the fact up, samples will diverge. Generate the main answer, draw several more samples, and score each sentence of the main answer by how well the samples support it. The paper scores support in several ways, including n-gram overlap, natural language inference and asking an LLM whether a sample supports the sentence.
SelfCheckGPT detects; it does not fix. Use it to flag sentences for review, for a second retrieval step, or for removal.
[04]
A note on "draft-then-verify"
"Draft, then verify" is a general pattern, not one paper. Don't confuse it with Draft & Verify (Zhang et al., 2023), a speculative-decoding method that speeds up generation and has nothing to do with checking facts.
[05]
Worked example: languages created at Bell Labs
List 8 programming languages that were created at Bell Labs. One per line, names only.Four samples at the model's lowest reasoning setting gave mostly correct lists. The fourth, used as the draft below, contains two errors:
B | C | C++ | dBase (dBASE) | AWK | Unix shell (sh) | Sieve | LimbodBase came from Wayne Ratliff and Ashton-Tate, not Bell Labs. Sieve is an email-filtering language standardized by the IETF. The other six are right.
SelfCheckGPT on a list: count support across samples
For a list, "support" can be as simple as: does the item appear in the other samples?
import re


def norm(item: str) -> str:
    return re.sub(r"\(.*?\)|plan 9'?s?|unix", "", item.lower()).strip()


other_items = [{norm(i) for i in s.splitlines() if i.strip()} for s in others]
for item in filter(str.strip, draft.splitlines()):
    support = sum(norm(item) in items for items in other_items)
    flag = "  <- check" if support == 0 else ""
print(f"{item.strip():<16} supported by {support}/{len(others)} other samples{flag}")B supported by 3/3 other samples
C supported by 3/3 other samples
C++ supported by 3/3 other samples
dBase (dBASE) supported by 0/3 other samples <- check
AWK supported by 3/3 other samples
Unix shell (sh) supported by 3/3 other samples
Sieve supported by 0/3 other samples <- check
Limbo supported by 3/3 other samplesBoth errors flagged, no false alarms, at the cost of three extra samples. The limit is visible in the other samples too: two of the four listed Bliss, which was created at Carnegie Mellon. A mistake the model makes consistently gets consistent support. For prose, replace the exact match with an LLM or NLI check of "does this sample support this sentence?".
Chain-of-Verification, attempt 1: yes/no questions
The plan prompt asked for "one short verification question per item". The model wrote yes/no questions, and each was answered in its own call:
Q: Was dBase (dBASE) originally created at or by developers at Bell Labs?
A: No — dBASE was created by Ashton-Tate (originally by programmer Wayne Ratliff, …), not by Bell Labs.
Q: Was Sieve (the mail filtering language) designed at Bell Labs for filtering email messages?
A: Yes — Sieve was originally designed at Bell Labs (by Chris Newman and colleagues) as a language for filtering email messages.
Q: Was Limbo created at Bell Labs for the Inferno operating system?
A: No — Limbo was created at Bell Labs for the Inferno operating system.
…
Final: B, C, C++, AWK, Sieve
It caught dBase but confirmed Sieve with an invented history, the agreement effect the paper describes. Two answers started with "No" and then stated the fact as true, so the revise step dropped two correct items (Limbo and sh).
Attempt 2: open questions, but not self-contained
The plan prompt now asked for open questions such as "Where and by whom was X created?". Because each question is answered without context, short names were ambiguous:
Q: Where and by whom was Limbo created?
A: Limbo was created by Playdead, an independent Danish game developer …
Q: Where and by whom was B created?
A: I don't have enough context to identify which "B" you mean …
…
Final: C, C++, AWK, sh, Limbo
Limbo, the video game. The verifier answered a different question, and B was dropped for lack of context.
Attempt 3: open and self-contained
Question: {question}
Draft answer:
{draft}

For each item, write one open verification question that asks for the fact itself.
Each question will be answered on its own, without this context, so it must name the item
fully (for example "Where and by whom was the programming language X created?").
Do not write yes/no questions. Exactly one question per item, one per line, no numbering.Q: Where and by whom was the programming language dBase (dBASE) created?
A: dBASE was created in the late 1970s in Berkeley, California by Wayne Ratliff … and later developed and commercialized by Ashton-Tate.
Q: Where and by whom was the programming language Sieve created?
A: Sieve was created at the University of Washington by Jonathan Epstein and others in the late 1980s … later standardized by the IETF …
Q: Where and by whom was the programming language Limbo created?
A: Limbo was created at Bell Labs by Phil Winterbottom and other members of the Inferno operating system team, including Rob Pike and Sean Quinlan.
…
Final: B, C, C++, AWK, Unix shell (sh), LimboCorrect: both errors removed, all six true items kept. Look closer at the checks, though. The Sieve answer is itself muddled, and the Limbo answer gets a team member wrong (Sean Dorward, not Sean Quinlan, co-designed it). The verification only had to settle "Bell Labs or not", and that it did. Verification answers come from the same model memory as the draft, so they carry the same kind of errors.
The full loop:
from concurrent.futures import ThreadPoolExecutor

plan = ask(PLAN.format(question=QUESTION, draft=draft))
questions = [q.strip() for q in plan.splitlines() if q.strip().endswith("?")]

# Factored: each question is answered in its own call, without the draft in context.
with ThreadPoolExecutor() as pool:
    answers = list(pool.map(lambda q: ask(q + " Answer in one sentence."), questions))
checks = "\n".join(f"Q: {q}\nA: {a}" for q, a in zip(questions, answers))

final = ask(f"""Question: {QUESTION}
Draft answer:
{draft}

Verification results:
{checks}

Write the final answer. Drop any item the verification contradicts. If fewer than 8 items survive, list only the ones that survive. One per line, names only.""")
ask(prompt) is a one-line wrapper around your chat API; PLAN is the attempt-3 prompt. The run used ten calls: plan, eight checks, final.
[06]
Other verification passes: self-refutation and bidirectional inference
CoVe and SelfCheckGPT are not the only ways to run a verification pass. Two more show up often, and both fit the same draft, check, revise loop:
Self-refutation. A separate call is asked to argue against the draft: "List the strongest reasons each claim below could be wrong, then mark it kept, changed or removed." It looks for counterevidence instead of confirmation, which helps against the model's habit of agreeing with itself. It still draws on the same memory, so it finds weak claims rather than proving strong ones.
Bidirectional inference verification. The model reasons forward from the question to an answer, then backward from the answer to the question: it hides one fact from the question and checks whether the candidate answer lets it recover that fact. Large Language Models are Better Reasoners with Self-Verification (Weng et al., Findings of EMNLP 2023) scores candidate answers this way, and FOBAR (Jiang et al., Findings of ACL 2024) masks a number in a math problem and asks the model to predict it from each candidate answer. It works best where the backward step has one right answer, as in math and logic.
Use self-refutation for prose and claims, backward checks for problems with a computable answer, and CoVe or SelfCheckGPT for facts from memory.
[07]
What changes with reasoning models
Reasoning models check some of their own work while thinking, and a higher reasoning setting is the first thing to try. They still state false facts with confidence, and a model verifying itself from memory shares its own blind spots, as the Sieve answer shows. Two upgrades matter more than the technique choice:
Answer verification questions from a source. Send each question to search, your documentation or a database instead of the model's memory. The plan step stays the same; only the execute step changes. See grounding with context.
Verify in code where you can. Names against a catalog, numbers against a table, citations against the quoted text. See output verification.
[08]
When to use which (and when not to)
Situation | Use | Cost |
|---|---|---|
Lists of entities or facts from memory | CoVe with open, self-contained questions | 2 + one call per item |
Long text, want to know which sentences are risky | SelfCheckGPT-style sampling | 3 to 5 extra samples plus scoring |
You have a trusted source | Check against it directly | Retrieval plus one call, or code |
Should the system answer at all? | 5 to 10 short samples | |
Creative or opinion text | Neither | No facts to check |
[09]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Yes/no verification questions | The model tends to agree with the fact in the question | Ask for the fact: where, who, when |
Questions that rely on context | Isolated answers resolve "Limbo" to a video game | Name the item and its type in every question |
Answering checks with the draft visible | The model repeats the draft's error | One call per question, draft not included |
Trusting the check answers | They come from the same memory and can be wrong | Use a source, or check only the key fact |
Treating sample agreement as truth | Consistent errors get consistent support | Combine with a source check for important facts |
Verifying everything | Ten calls for a list nobody depends on | Verify where errors cost something |
[10]
Frequently asked questions
Does Chain-of-Verification eliminate hallucinations?
No. It reduces them on the tasks the paper tested, and in the example above it removed both errors only after the questions were made open and self-contained. The checks come from the same model and can be wrong themselves.
What is the difference between CoVe and SelfCheckGPT?
CoVe fixes the draft: it asks targeted questions and revises. SelfCheckGPT detects risk: it compares the draft with other samples and scores each claim. A common combination is SelfCheckGPT to find suspicious claims, then a verification step only on those.
How many samples does SelfCheckGPT need?
A few. Three extra samples were enough to flag both errors in the list example. More samples give smoother scores for long text, at a linear cost.
Should verification use a different model?
It can help, because a different model has different blind spots, but it is not a substitute for a source. A smaller model is fine for the check calls when each one only has to settle a single fact.
Is self-critique the same as verification?
No. "Review your answer and fix mistakes" in the same context mostly re-reads the draft and tends to keep it. Verification works when the checks are independent of the draft, or come from outside the model.
What is self-refutation in LLM verification?
A verification pass in which the model, in a separate call, tries to disprove its own answer: it lists the reasons each claim could be wrong and then keeps, fixes or drops it. It catches weak claims that a "review your answer" prompt waves through, because it asks for counterevidence. For important facts, back it with a source.
What is bidirectional inference verification?
Checking an answer in both directions. The model first reasons from the question to an answer, then works backward: given the answer, it must recover a fact hidden from the question. If it can't, the answer is suspect. Self-verification (Weng et al.) and FOBAR (Jiang et al.) use this for math and reasoning problems.
[11]
Next steps
The basics: hallucination basics and quick checks.
Decide whether to answer at all: semantic entropy.
Verify with code and sources: output verification.
Give the model the facts up front: grounding with context.
Visible steps you can check: chain-of-thought for beginners.
Use examples to fix the format of answers you parse: few-shot examples the right way.