Contents · 10 sections↓
- 01What are self-consistency and least-to-most prompting?
- 02How self-consistency works
- 03How least-to-most prompting works
- 04Worked example: a clock that runs fast
- 05Worked example: least-to-most on tiered pricing
- 06When to use them (and when not to)
- 07What changes with reasoning models
- 08Common mistakes
- 09Frequently asked questions
- 10Next steps
Self-consistency and least-to-most are two upgrades to chain-of-thought prompting. Self-consistency samples several reasoning paths and keeps the answer most of them agree on. Least-to-most splits a hard problem into simpler sub-questions and solves them in order. This guide is for developers who already use step-by-step prompts and want to know which upgrade fits which problem, what each costs, and when a reasoning model makes both unnecessary. If you are new to chain-of-thought, start with chain-of-thought for beginners.
What are self-consistency and least-to-most prompting?
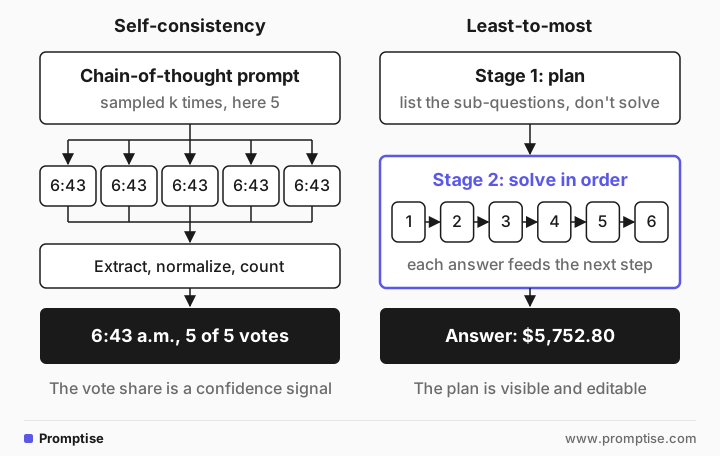
Self-consistency runs the same chain-of-thought prompt several times, extracts each final answer, and returns the majority answer. Least-to-most prompting first asks the model to list the sub-problems, then solves them one after another, feeding each answer into the next step. Both trade extra tokens for accuracy on multi-step problems with a checkable answer.
Key takeaways:
Self-consistency votes over reasoning paths, not over bare answers. Sampling direct answers and voting does little.
The vote share is a confidence signal. Five out of five is safer than three out of five, but agreement is not proof.
Least-to-most helps when the problem has an obvious order of sub-steps, such as tiered pricing or multi-part rules.
With reasoning models, raise the reasoning effort first. It is usually cheaper than five calls and gets most of the benefit.
[02]
How self-consistency works
Self-Consistency Improves Chain of Thought Reasoning in Language Models (Wang, Wei, Schuurmans, Le, Chi, Narang, Chowdhery and Zhou, 2022) replaced the single greedy chain-of-thought answer with a sample of diverse reasoning paths. The idea: a hard problem can be solved in several ways, and the correct answer is the one most paths reach. The paper reported large gains over plain chain-of-thought on arithmetic and commonsense benchmarks, for example +17.9% on GSM8K with the models of that time.
The procedure has three parts:
Sample k completions of a chain-of-thought prompt (the paper used temperature sampling; 5 to 20 samples is a common range).
Extract the final answer from each one, which requires a fixed answer format.
Normalize and count. Return the most common answer and its share of the votes.
Voting needs answers you can compare: a number, a date, a multiple-choice letter, a short label. For free-form text there is Universal Self-Consistency (Chen et al., 2023), which asks the model itself to pick the most consistent of several candidates. That idea is covered in prompt ensembles and rank-then-respond.
[03]
How least-to-most prompting works
Least-to-Most Prompting Enables Complex Reasoning in Large Language Models (Zhou et al., 2022) targets easy-to-hard generalization: problems harder than the examples in the prompt. It runs in two stages. First the model breaks the problem into simpler sub-problems. Then it solves them in sequence, and each solution is added to the context for the next one. With 14 exemplars, the paper's least-to-most prompt solved the SCAN compositional benchmark at 99% or better on every split, where chain-of-thought reached 16%.
The difference from plain chain-of-thought is control. You see the plan before any solving happens, you can check or edit it, and each sub-answer is small enough to verify.
[04]
Worked example: a clock that runs fast
A clock gains 3 minutes every hour (true time). It is set to the correct time at 9:00 a.m. on Monday.
What is the true time when the clock first shows 9:00 a.m. on Wednesday? Give the answer to the nearest minute.
The correct answer is Wednesday 6:43 a.m. The clock shows 48 hours passing, and it runs at 63 clock minutes per 60 true minutes, so 2,880 clock minutes take 2,880 × 60 / 63 ≈ 2,743 true minutes, or 45 hours 43 minutes.
Five direct answers, then a vote
With the model's reasoning set to its lowest level and "Reply with just the day and time" appended, five samples gave:
['Wednesday 6:00 a.m.', 'Wednesday 8:00 a.m.', 'Wednesday 6:00 a.m.', 'Wednesday 8:00 a.m.', 'Wednesday 8:00 AM']All wrong, and the majority (8:00) is wrong too. Voting over answers without reasoning only averages guesses.
Five step-by-step answers, then a vote
Same setting, with the answer format added:
<same question>

Work through it step by step, briefly, then put the final answer on the last line as: Answer: <day> <time>
The last line of each of the five samples:
'Answer: Wednesday 6:43 a.m.'
'Answer: Wednesday 6:43 AM'
'Answer: Wednesday 6:43 a.m.'
'Answer: Wednesday 6:43 a.m.'
'Answer: Wednesday 6:43 a.m.'
Five out of five, and correct. Here a single step-by-step call would already have been right; the value of the other four is the confidence: a 5/5 vote is a result you can ship, a 3/5 vote is one to flag for review.
Agreement is not correctness
A second question, asked the same direct way five times: "How many Friday the 13ths are there in the year 2026?" All five samples answered 1. The correct answer is 3 (February, March and November). When a model makes a systematic error, every sample makes it, and the vote is unanimous and wrong. With step-by-step reasoning, all five samples answered 3. Use the vote share as a signal, and keep an independent check (code, a calculator, a lookup) for anything that matters.
The self-consistency loop in code
import re
from collections import Counter
from openai import OpenAI

client = OpenAI()


def ask(prompt: str, n: int = 1, effort: str = "minimal") -> list[str]:
    r = client.chat.completions.create(
        model="gpt-5-mini", messages=[{"role": "user", "content": prompt}],
        reasoning_effort=effort, n=n,  # n samples in one request; otherwise make n parallel calls
    )
    return [c.message.content for c in r.choices]


def normalize(answer: str) -> str:
    return re.sub(r"[^a-z0-9:.]", "", answer.lower()).replace("a.m.", "am").rstrip(".")


def self_consistency(question: str, k: int = 5) -> tuple[str, float]:
    prompt = question + "\n\nWork through it step by step, briefly, then put the final answer on the last line as: Answer: <answer>"
    finals = [m[-1] for out in ask(prompt, n=k) if (m := re.findall(r"Answer:\s*(.+)", out))]
    answer, votes = Counter(normalize(f) for f in finals).most_common(1)[0]
    return answer, votes / k
Normalization matters more than it looks: "6:43 a.m." and "6:43 AM" are the same vote. For numbers, strip currency signs and thousands separators before counting.
[05]
Worked example: least-to-most on tiered pricing
A SaaS plan costs $12 per user per month for the first 10 users, $9 per user per month for users 11 to 50,
and $6 per user per month for every user beyond 50. Annual billing gets 15% off.
A company with 64 users pays annually. What is its annual cost?
The correct answer is $5,752.80. Asked directly three times at minimal reasoning:
['$5,850.24', '$5,184', '$5,\\!166.24']Three different wrong answers. Least-to-most uses two calls. Stage 1 asks only for the plan:
<same problem>

Do not solve it yet. List the simpler sub-questions that must be answered first, in the order they should be solved, one per line, numbered.1. How many users fall into each pricing tier for 64 users (first 10, next 11–50, and beyond 50)?
2. What is the monthly cost for each tier (number of users in that tier multiplied by that tier's per-user monthly price)?
3. What is the total monthly cost before the annual discount (sum of the tier monthly costs)?
4. What is the total annual cost before the discount (monthly total multiplied by 12)?
5. What is the 15% discount amount on the annual cost?
6. What is the final annual cost after subtracting the 15% discount?Stage 2 passes the problem and that list back: "Solve these sub-questions in order. Answer each one in one line, using the earlier answers. Then put the final answer on the last line as: Answer: <amount>".
1. Users per tier: first 10 = 10, next 11–50 = 40, beyond 50 = 14.
2. Monthly cost per tier: first 10 = 10×$12 = $120; next 40 = 40×$9 = $360; beyond 14 = 14×$6 = $84.
3. Total monthly cost before discount: $120 + $360 + $84 = $564.
…
6. Final annual cost after discount: $6,768 − $1,015.20 = $5,752.80.
Answer: $5,752.80
Correct, and every line is checkable. The plan from stage 1 is also a reusable artifact: for a recurring task type, review it once and hard-code it, which turns least-to-most into a fixed step prompt.
[06]
When to use them (and when not to)
Situation | Use | Why |
|---|---|---|
Short, checkable answer, fast model, errors are costly | Self-consistency, k = 3 to 5 | Accuracy plus a confidence score |
Problem with a natural order of sub-steps | Least-to-most | Plan is visible and editable |
Free-form output (emails, summaries) | Neither; see prompt ensembles | No answers to vote on |
Exact arithmetic over many numbers | Code, not votes; see program-of-thought | A calculator does not need a majority |
Reasoning model available | Raise reasoning effort first | Cheaper than k calls for similar gains |
[07]
What changes with reasoning models
Reasoning models (OpenAI's o-series and GPT-5 family, Claude with extended thinking, Gemini thinking models) already work through problems before answering. Two findings frame what that means. To CoT or not to CoT? (Sprague et al., 2024) found chain-of-thought helps mainly on math and symbolic tasks. The Decreasing Value of Chain of Thought in Prompting (Meincke, Mollick, Mollick and Shapiro, 2025) found that for reasoning models, asking for chain-of-thought gave marginal gains at best, while adding time and tokens.
In practice:
Instead of self-consistency for accuracy, set reasoning effort to low or medium on one call. In the Friday-the-13th example, one direct call at low reasoning effort answered 3, correctly, where five calls at minimal effort all answered 1.
Keep self-consistency for confidence. Three samples at low effort and a vote share give you a number to route on: ship at 3/3, flag at 2/3. See semantic entropy for the free-text version.
Keep least-to-most for control, not for thinking. A visible plan you can check, edit or hard-code is useful with any model.
[08]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Voting over direct answers | No reasoning paths, so the vote averages guesses | Sample step-by-step completions |
No fixed answer line | Extraction fails or picks a number from the reasoning | "Answer: <x>" on the last line, parse that |
Comparing raw strings | "6:43 AM" and "6:43 a.m." split the vote | Normalize before counting |
Treating 5/5 as proof | Systematic errors are unanimous | Independent check for high-stakes answers |
k = 20 by default | 20 times the cost for small extra gains on easy items | Start at 3 to 5; sample more only on low agreement |
Least-to-most for a one-step question | Two calls where one would do | Use it when sub-steps are real |
[09]
Frequently asked questions
How many samples does self-consistency need?
Three to five is a practical start. Gains flatten as k grows, so a common pattern is adaptive: take three samples, stop if they agree, and draw more only when they don't. That keeps the average cost close to three calls.
Does self-consistency work with temperature 0?
No. At temperature 0 most models return near-identical paths, so the vote adds nothing. Use the model's default sampling or a moderate temperature. Some reasoning models don't let you set temperature; their default sampling already varies.
What is the difference between least-to-most and plain chain-of-thought?
Chain-of-thought produces one stream of reasoning. Least-to-most separates planning from solving: the model lists sub-problems first, then solves them in order with earlier answers in context. You can inspect and fix the plan before solving.
Is self-consistency the same as an ensemble?
It is a kind of ensemble: one prompt, many samples, majority vote. Prompt ensembles vary the prompt itself and often use a judge to pick a winner, which also works for free-form text.
Should I use these techniques with reasoning models?
Rarely for accuracy alone; raise the reasoning effort instead. Self-consistency still earns its cost as a confidence signal, and least-to-most as a visible, editable plan.
[10]
Next steps
The beginner version: chain-of-thought prompting for beginners.
Decomposition with retrieval: Self-Ask, Auto-CoT and decomposition prompts.
Search instead of a single path: Tree of Thoughts.
Free-form answers: prompt ensembles and rank-then-respond.
Worked examples in the prompt: few-shot examples the right way.
Exact math: program-of-thought and PAL.