Contents · 10 sections↓
- 01What is prompt compression?
- 02Why compress: cost, latency and lost in the middle
- 03Prompt compression techniques
- 04Worked example: selection vs a generic summary
- 05How to apply LLMLingua
- 06How to mitigate lost in the middle
- 07When to compress (and when not to)
- 08Common mistakes
- 09Frequently asked questions
- 10Next steps
Prompt compression means sending the model fewer tokens while keeping the information it needs: dropping irrelevant documents, pruning low-information words, or summarizing context before the main call. It cuts cost and latency, and done well it can also help accuracy, because long contexts suffer from the "lost in the middle" effect. This guide covers the main techniques (selection, LLMLingua-style token pruning, abstractive compression), how to place what remains, and where compression goes wrong. It's for developers running RAG or long-document prompts at volume, with a real 15,900-token example.
What is prompt compression?
Prompt compression reduces the number of input tokens before a model call while preserving what the task needs. The three main families are: selecting only relevant chunks (retrieval, reranking), pruning tokens inside the text with a small model (LLMLingua and its successors), and rewriting context into a shorter summary (RECOMP). Question-aware compression, which keeps what matters for this specific question, is safer than generic shortening.
Key takeaways:
Select first. Dropping whole irrelevant documents is the cheapest, most faithful compression.
Compress for the question, not in general. Generic summaries lose the detail you needed.
Keep instructions intact. Compress the data, not the rules.
Place the best material at the start and end of what you send.
Measure the answer, not just the token count. Compare compressed and uncompressed answers on real questions.
[02]
Why compress: cost, latency and lost in the middle
Every input token is billed and processed. At high volume, a RAG prompt that carries ten chunks when two would do costs several times more than it needs to.
The accuracy argument comes from Lost in the Middle: How Language Models Use Long Contexts (Liu et al., 2023, TACL). On multi-document question answering and key-value retrieval, they found performance was often highest when the relevant information was at the beginning or end of the context and degraded significantly when it was in the middle, even for models built for long contexts. In an open-domain QA case study, they also found that answer quality saturated long before retrieval recall did: past a point, more retrieved documents added little. Newer models are stronger at long-context retrieval, but the practical lesson holds: fewer, better-placed documents are easier for the model to use.
For prompt layout, structure and retrieval-versus-stuffing decisions, see long-context prompting tactics. This guide is about reducing what you send.
[03]
Prompt compression techniques
Technique | What it does | Source | Good for | Risk |
|---|---|---|---|---|
Selection (BM25, embeddings, reranker) | Keeps the top-k relevant chunks, drops the rest | Standard IR | RAG, policy and FAQ corpora | Misses a relevant chunk that scores low |
Selective Context | Prunes low self-information phrases using a small language model | Li et al., 2023 (EMNLP) | Long articles, conversations | Can drop rare but key terms |
LLMLingua | Coarse-to-fine token pruning with a small model and a budget controller | Jiang et al., 2023 (EMNLP) | Long few-shot and reasoning prompts | Output text is ungrammatical; harder to debug |
LongLLMLingua | Question-aware version that also reorders documents | Jiang et al., 2023 (ACL 2024) | Multi-document QA | Same, plus extra compute per query |
LLMLingua-2 | Token classification with a small encoder trained on GPT-4-distilled data; task-agnostic | Pan et al., 2024 (ACL Findings) | Fast general compression, meeting transcripts | Task-agnostic means it doesn't know your question |
Abstractive compression | A model summarizes the context, optionally for the question | Many retrieved documents with overlap | Paraphrase can change meaning and lose sources |
What the papers report, briefly: LLMLingua reports up to 20x compression "with little performance loss" on its benchmarks. LongLLMLingua reports up to 21.4% better performance on NaturalQuestions with about 4x fewer tokens using GPT-3.5-Turbo. LLMLingua-2 reports being 3x to 6x faster than earlier compression methods, at compression ratios of 2x to 5x. RECOMP reports compression rates as low as 6% with minimal loss on its tasks. These are results on specific benchmarks and older models; test on your own data.
[04]
Worked example: selection vs a generic summary
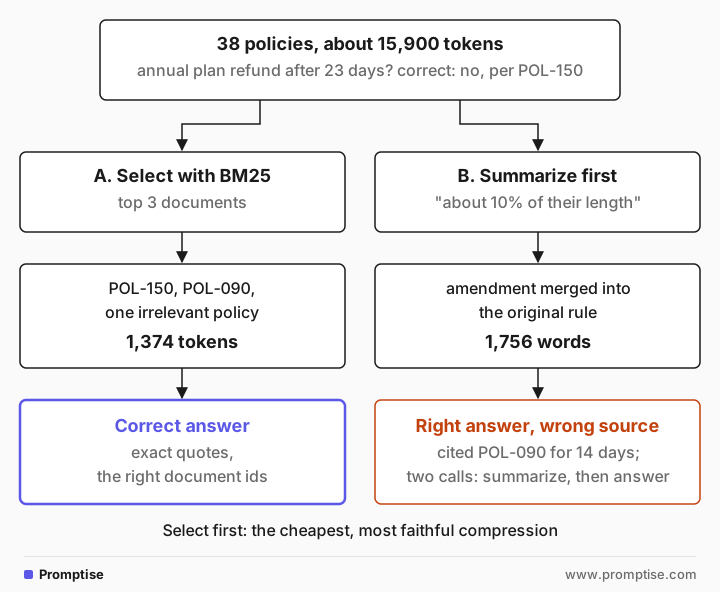
The same setup as the long-context guide: 38 support policies, about 15,900 input tokens. One policy says annual plans can be refunded within 30 days; an amendment (POL-150, dated later) changes it to 14 days. The question asks whether a refund 23 days after purchase is allowed. The correct answer is no, per POL-150.
Option A: select the relevant documents with BM25
A plain BM25 ranker in about fifteen lines, no dependencies:
import math, re
from collections import Counter

def tokens(text):
    return re.findall(r"[a-z0-9]+", text.lower())

def bm25_top_k(query, docs, k=3, k1=1.5, b=0.75):
    corpus = [tokens(d["title"] + " " + d["text"]) for d in docs]
    avg = sum(map(len, corpus)) / len(corpus)
    df = Counter(t for doc in corpus for t in set(doc))
    q = set(tokens(query))
    def score(doc):
        tf = Counter(doc)
        return sum(math.log(1 + (len(corpus) - df[t] + 0.5) / (df[t] + 0.5))
                   * tf[t] * (k1 + 1) / (tf[t] + k1 * (1 - b + b * len(doc) / avg))
                   for t in q if t in tf)
    ranked = sorted(range(len(docs)), key=lambda i: score(corpus[i]), reverse=True)
    return [docs[i] for i in ranked[:k]]

top = bm25_top_k(question + " refund annual plan", docs, k=3)
It picked POL-150 Amendment to POL-090, POL-090 Refunds and one irrelevant policy. The answer from those three, with the same instructions as before:
Quoted passages:
- "Effective 2026-03-01, annual plans can be refunded within 14 days of the purchase date, not 30." (POL-150)
- "Annual plans can be refunded within 30 days of the purchase date." (POL-090)

POL-150 is later (2026-03-01) than POL-090 (2025-02-10), so POL-150 overrides.

Answer:
No — under POL-150 annual plans are refundable only within 14 days of purchase; a request on 2026-04-25 for a 2026-04-02 purchase is past 14 days and not eligible.
Input dropped from about 15,900 tokens to 1,374, and the answer is correct with exact quotes and the right document ids. Note the query expansion (+ " refund annual plan"): the raw question contains "refund" once and many dates, so a few keywords help a lexical ranker. Embedding search or a reranker handles this better at scale.
Option B: summarize everything first, then answer
Compress these policies to about 10% of their length. Keep the key rules.
<all 38 policies>
The summary came back at 1,756 words, closer to 13% than 10%, and took 2,705 output tokens. The relevant part merged the amendment into the original policy:
  - Monthly refunds within 14 days; annual refunds amended to 14 days (effective 2026-03-01); monthly unchanged.
  - Refunds prorated after first 7 days.
The final answer was right, but it cited the wrong source:
"Citing POL-090 Refunds: 'Monthly refunds within 14 days; annual refunds amended to 14 days (effective 2026-03-01); monthly unchanged.' (POL-090)POL-090 never says 14 days for annual plans. The amendment's id disappeared in compression, and the "quote" is a paraphrase. This option also cost more than sending the full context once: one full-context call to summarize plus a second call to answer. Generic compression only pays off when the summary is reused across many questions, and even then it loses provenance.
[05]
How to apply LLMLingua
LLMLingua-2 runs locally as a small encoder model. The usage below follows the LLMLingua README. It downloads model weights on first use:
from llmlingua import PromptCompressor   # pip install llmlingua

compressor = PromptCompressor(
    model_name="microsoft/llmlingua-2-xlm-roberta-large-meetingbank",
    use_llmlingua2=True,
)
result = compressor.compress_prompt(context, rate=0.33, force_tokens=["\n", "?"])
compressed = result["compressed_prompt"]
rate=0.33 targets about a third of the original tokens. force_tokens keeps characters you need for structure. Apply it to the data part of the prompt only, and keep ids, dates, numbers and your instructions out of the compressor's reach, or protect them. For multi-document QA, the README shows LongLLMLingua options that take the question and reorder documents by relevance.
[06]
How to mitigate lost in the middle
Once you've chosen what to send, place it well:
Send fewer chunks. Three relevant chunks beat ten with seven distractors.
Put the most relevant chunks at the edges. If your retriever returns chunks sorted best first, interleave them so the best are first and last.
Keep instructions and the question at the end (and optionally a short task line at the start).
Give each chunk an id, so the model can cite and you can check.
def reorder_for_edges(chunks_by_relevance: list[str]) -> list[str]:
    """Most relevant chunks go to the start and end, least relevant to the middle."""
    front, back = [], []
    for i, chunk in enumerate(chunks_by_relevance):
        (front if i % 2 == 0 else back).append(chunk)
    return front + back[::-1]

print(reorder_for_edges(["c1", "c2", "c3", "c4", "c5", "c6"]))['c1', 'c3', 'c5', 'c6', 'c4', 'c2']The best chunk (c1) is first, the second best (c2) last, and the weakest in the middle.
[07]
When to compress (and when not to)
Compress when:
You send many retrieved chunks per question, at volume.
Context includes boilerplate repeated across documents (footers, disclaimers, signatures).
Few-shot examples or transcripts are long and only partly relevant.
Don't compress when:
The text is short or already dense. Savings are small and the risk is the same.
Exact wording matters: contracts, code, legal text, quotes you'll show users.
You reuse the same long prefix for many calls. Prompt caching gives you a discount on repeated prefixes without changing a word.
[08]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Generic "make this shorter" summaries | Drops the detail the question needs, merges sources | Select or compress for the question |
Compressing the instructions | Rules and output formats lose words that matter | Compress only the data section |
Token pruning on ids, numbers and dates | Pruned or split values break answers and citations | Protect them with forced tokens or keep them outside the compressor |
Judging by token savings alone | Cheaper but wrong is not a win | Compare answers with and without compression on real questions |
Ten chunks in retrieval order | Relevant chunks land in the middle | Fewer chunks, best at the edges |
Compressing to save money on a reused prefix | Caching is cheaper and lossless | Use provider prompt caching |
[09]
Frequently asked questions
What is LLMLingua?
A family of prompt compression methods from Microsoft Research. LLMLingua (2023) prunes tokens with a small language model and a budget controller. LongLLMLingua adds question-aware compression and document reordering for long contexts. LLMLingua-2 (2024) treats compression as token classification with a small encoder, which is faster and task-agnostic. All are open source.
Does prompt compression hurt accuracy?
It can. Selection can miss a relevant chunk, pruning can remove a key word, and summaries can change meaning, as in the example above where the amended rule was attributed to the wrong policy. Question-aware methods hurt less, and some papers report accuracy gains on long multi-document inputs. Always evaluate on your own questions.
What is the lost-in-the-middle problem?
Liu et al. (2023) found that language models used relevant information at the beginning or end of a long context better than information in the middle. Mitigate it by sending fewer documents and placing the most relevant ones at the start and end.
Is prompt caching a form of compression?
No, but it solves part of the same problem. Caching reduces the cost and latency of a repeated prefix without changing it. Use caching for stable context such as long system prompts or a fixed document, and compression for per-query context such as retrieved chunks.
How much can I compress?
It depends on how redundant your context is. Papers report ratios from 2x to 20x on their benchmarks. In practice, start with selection (often the biggest win), then try a modest token-pruning rate and compare answers before going further.
[10]
Next steps
Layout, structure and RAG vs stuffing: long-context prompting tactics.
Context budgets in long agent runs: context engineering for AI agents.
Cut cost on repeated questions: LLM semantic cache and model fallback.
Dense summaries that keep entities: summarization with chain of density.
Retrieval basics: RAG zero to one.