Contents · 8 sections↓
Tree of Thoughts (ToT) prompting turns one line of reasoning into a search. The model proposes several possible next steps, an evaluator scores them, and only the promising ones are expanded. It was built for puzzles and planning problems where the first move decides everything. This guide explains ToT and its graph-shaped successor, Graph of Thoughts, shows a small runnable ToT search for the Game of 24 with its real output, and covers when a reasoning model or a few lines of code do the job for less.
What is Tree of Thoughts prompting?
Tree of Thoughts is a search over partial solutions. Each "thought" is a coherent intermediate step, such as one equation or one paragraph plan. The model generates candidate thoughts, the model (or code) evaluates them, and a search algorithm such as breadth-first search with a fixed beam keeps the best ones, backtracking from dead ends. It costs many model calls per problem.
Key takeaways:
ToT helps when early choices matter and can be judged, like puzzles, constrained planning or layouts with hard rules.
The evaluator is the weak point. A model judging its own partial work prunes good branches; a code check does not.
Try the cheap options first: a reasoning model with higher effort, or sample a few answers and verify them in code.
Graph of Thoughts adds merging, so separate partial results can be combined, as in sorting chunks and merging them.
[02]
How Tree of Thoughts works
Tree of Thoughts: Deliberate Problem Solving with Large Language Models (Yao, Yu, Zhao, Shafran, Griffiths, Cao and Narasimhan, 2023) describes four design choices:
Thought decomposition: what one step is. In the Game of 24, one step is one arithmetic operation on two of the remaining numbers.
Thought generator: sample several independent thoughts, or ask for several in one "propose" prompt.
State evaluator: score each state on its own (the paper used "sure / likely / impossible") or vote across states.
Search algorithm: breadth-first search with a beam of b states per level, or depth-first search with backtracking.
The paper tested three tasks that need lookahead: the Game of 24, creative writing and mini crosswords. In the Game of 24, GPT-4 with chain-of-thought solved 4% of the puzzles; with ToT, 74%.
A related paper from the same month, Large Language Model Guided Tree-of-Thought (Long, 2023), adds a checker module and a controller that decides when to backtrack, and applies it to Sudoku.
[03]
Graph of Thoughts: when branches need to merge
Graph of Thoughts: Solving Elaborate Problems with Large Language Models (Besta et al., 2023) models thoughts as vertices in an arbitrary graph. Besides branching, a thought can combine several others (aggregation) or loop back to refine itself. The example that fits best is sorting: split a list into chunks, sort each chunk, merge the sorted chunks. The paper reported 62% better sorting quality than ToT at more than 31% lower cost.
If that sounds like an ordinary program with LLM calls in it, that is the right reading. Graph of Thoughts is a way to describe a workflow of prompts with dependencies. In practice you write it as code: a map step, a merge step, a refine step.
[04]
Worked example: the Game of 24
Use the numbers 3, 3, 8, 8 exactly once each, with + - * / and parentheses, to make 24.This is a hard instance. The only solution is 8 / (3 − 8/3).
Three direct answers, checked in code
With the model's reasoning at its lowest level and "Reply with just the expression":
['(8/(3-8/3))*3', '(8/(3-8/3))*3', '(8/(3-8/3))']The first two use an extra 3 and equal 72. The third is correct. A short checker tells them apart:
import ast
from collections import Counter
from fractions import Fraction


def value(node):
    if isinstance(node, ast.Constant):
        return Fraction(node.value)
    a, b = value(node.left), value(node.right)
    return {ast.Add: a + b, ast.Sub: a - b, ast.Mult: a * b}.get(type(node.op)) if not isinstance(node.op, ast.Div) else a / b


def is_valid_24(expr: str, numbers: list[int]) -> bool:
    try:
        tree = ast.parse(expr, mode="eval").body
        used = [n.value for n in ast.walk(tree) if isinstance(n, ast.Constant)]
        return Counter(used) == Counter(numbers) and value(tree) == 24
    except (SyntaxError, ZeroDivisionError, TypeError, AttributeError):
return False(8/(3-8/3))*3 False
(8/(3-8/3))*3 False
(8/(3-8/3)) TrueSample a few, keep the one that passes. This "generate and verify" pattern is the cheapest relative of ToT, and it works whenever you can check an answer in code.
A small Tree of Thoughts search
The search below follows the paper's breadth-first version. The model proposes next steps, code rejects any step that is arithmetically wrong, the model rates each remaining state, and the top five states move on.
import re
from fractions import Fraction

PROPOSE = """Numbers left: {nums}
Goal: reach 24 using every number exactly once with + - * /.
Propose up to 5 different next steps. Each step combines exactly two of the numbers left.
One per line, in the form: a op b = c (left: x y z)"""

EVALUATE = """Goal: reach exactly 24 using every number in a set once with + - * /.
For each numbered set below, judge whether 24 can still be reached: sure, likely, or impossible.

Sets:
{states}

Reply with one line per set, in the form: <number>. <verdict>"""

STEP = re.compile(r"(-?[\d/]+)\s*([+\-*/])\s*(-?[\d/]+)\s*=\s*(-?[\d/]+)")
OPS = {"+": lambda a, b: a + b, "-": lambda a, b: a - b, "*": lambda a, b: a * b,
       "/": lambda a, b: a / b if b else None}
SCORE = {"sure": 2, "likely": 1, "impossible": 0}


def fmt(nums):
    return " ".join(str(n) for n in nums)


def children(nums, path):
    """Ask for candidate steps; keep only those that are arithmetically valid (checked in code)."""
    out = []
    for line in ask(PROPOSE.format(nums=fmt(nums))).splitlines():
        m = STEP.search(line)
        if not m:
            continue
        a, op, b = Fraction(m[1]), m[2], Fraction(m[3])
        left = list(nums)
        if a not in left:
            continue
        left.remove(a)
        if b not in left:
            continue
        left.remove(b)
        c = OPS[op](a, b)
        if c is None:
            continue
        out.append((left + [c], path + [f"{a} {op} {b} = {c}"]))
    return out


def tot(numbers, beam=5):
    frontier = [([Fraction(n) for n in numbers], [])]
    for depth in range(len(numbers) - 1):
        candidates = [child for nums, path in frontier for child in children(nums, path)]
        if depth == len(numbers) - 2:  # last step: check the goal in code
            return [path for nums, path in candidates if nums == [24]]
        states = "\n".join(f"{i}. {fmt(n)}" for i, (n, _) in enumerate(candidates, 1))
        reply = ask(EVALUATE.format(states=states))
        verdicts = {int(i): v for i, v in re.findall(r"(\d+)\W+(sure|likely|impossible)", reply.lower())}
        scored = sorted(enumerate(candidates, 1), key=lambda ic: -SCORE.get(verdicts.get(ic[0]), 0))
        frontier = [c for i, c in scored[:beam] if SCORE.get(verdicts.get(i), 0) > 0]
        print(f"depth {depth + 1}: {len(candidates)} candidates, kept {[fmt(n) for n, _ in frontier]}")
    return []
ask(prompt) is a one-line wrapper around your chat API that returns the text. Output of tot([3, 3, 8, 8]) with the same fast setting:
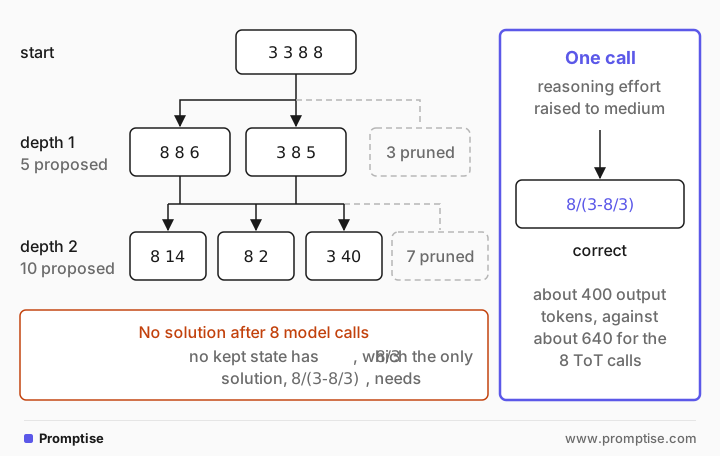
depth 1: 5 candidates, kept ['8 8 6', '3 8 5']
depth 2: 10 candidates, kept ['8 14', '8 2', '3 40']
No solution, after eight model calls. Neither state kept at depth 1 contains 8/3, the intermediate value the only solution needs, so the search was lost after the first step. Another evaluator prompt failed the other way and rated a dead end highly: it kept the set "3 8 24" among its best states, although 24 cannot be reached from it. The search algorithm was fine. The proposals and the ratings were not.
One call with more reasoning
The original direct prompt, with reasoning effort raised to medium:
8/(3-8/3)Correct, in one call that used about 400 output tokens, fewer than the roughly 640 the eight ToT calls used together. Results vary by model and run, but the direction is typical: a reasoning model runs its own search internally, and it is usually better at it than a hand-built tree with a fast model as the judge.
[05]
When to use Tree of Thoughts (and when not to)
ToT is worth its cost when all of these hold:
A single pass, even with more reasoning, fails often enough to matter.
Steps really branch, and a bad early step cannot be repaired later.
You can evaluate partial states reliably, ideally in code: tests pass, constraints hold, a schedule has no conflicts.
Cheaper options, in the order to try them:
Option | When it fits | Cost |
|---|---|---|
Raise reasoning effort | Any model with a reasoning setting | One call, more hidden tokens |
Sample 3 to 5, verify in code | The final answer can be checked | 3 to 5 calls plus a checker |
Ask the model to write a solver | Search problems with clear rules (24, scheduling, packing) | One call plus running code; see program-of-thought |
Self-consistency vote | Short answers you can compare but not check | k calls; see self-consistency |
Tree of Thoughts | Branching steps with a reliable partial-state check | Tens of calls per problem |
For writing tasks, a light version works: generate three outlines, pick one with a rubric, then write. That is one level of the tree, and it is the same pattern as rank-then-respond.
[06]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
The model judges its own partial states | It rates impossible states "sure" and prunes the right branch | Use code checks where you can; model ratings only as a tiebreaker |
Thoughts that are too small or too big | Tokens are too small to judge; whole answers leave nothing to search | One meaningful step: an equation, a plan item, a move |
No validity check on proposals | Arithmetic or rule errors enter the tree | Parse and verify each step in code before scoring |
Beam too narrow | One bad rating ends the search | Beam of 3 to 5, and keep "likely" states |
No call budget | Cost grows with branching factor times depth | Cap calls and stop on the first verified solution |
Using ToT where a solver exists | Many calls for a problem code solves exactly | Have the model write the solver |
[07]
Frequently asked questions
Is Tree of Thoughts still useful with reasoning models?
Less than it was. Reasoning models explore and backtrack internally, and in the example above one medium-effort call beat an eight-call tree. ToT still helps when you have an external evaluator, such as tests or a constraint checker, that is better than the model's own judgment.
What is the difference between Tree of Thoughts and self-consistency?
Self-consistency samples several complete reasoning paths and votes on the final answers. Tree of Thoughts evaluates partial paths and prunes during the search. Self-consistency needs comparable final answers; ToT needs a way to score intermediate states.
What is Graph of Thoughts used for?
Problems where partial results must be merged, not only chosen: sorting chunks and merging them, combining summaries of sections, or refining a draft in a loop. Written as code, it is a workflow of prompts with dependencies.
How many calls does a ToT search take?
Roughly one propose call per kept state per level, plus an evaluation call per level if you batch the ratings. The small search above took eight calls for four numbers. Wider beams or deeper problems grow quickly, so set a budget.
Can I do Tree of Thoughts in a single prompt?
You can ask for "three approaches, rate each, continue with the best" in one prompt. It is cheaper and sometimes helps, but the model rates its own work in the same context, which loses the independent evaluation that makes ToT work.
[08]
Next steps
The foundation: chain-of-thought prompting for beginners.
Voting instead of searching: self-consistency and least-to-most.
Let code do the search: program-of-thought and PAL.
Choosing among candidates: prompt ensembles and rank-then-respond.
Outline first, then write: Skeleton-of-Thought.
Examples that teach a procedure: few-shot examples the right way.