Contents · 11 sections↓
A ReAct agent alternates between reasoning about what it needs and acting with a tool, then reads the result and decides again, until it can answer. It's the loop behind most AI agents. This guide explains the pattern from the original paper, builds a working loop from scratch in about 60 lines of Python with a real trace, and maps it to native tool calling. It's for developers who want to know what an agent framework does, or need a minimal loop they control.
What is a ReAct agent?
ReAct (Reason + Act) is a prompting pattern where the model produces interleaved reasoning traces and actions: a Thought about what to do next, an Action that calls a tool, then an Observation with the tool's result, repeated until a final answer. It was introduced in ReAct: Synergizing Reasoning and Acting in Language Models (Yao et al., 2022, ICLR 2023). The reasoning steers which tool to call; the observations ground the reasoning in real data.
Key takeaways:
The loop is simple: model proposes an action, your code runs it, the result goes back to the model.
Your code is in charge: it parses actions, runs tools, enforces limits and decides when to stop.
Feed errors back as observations, so the model can correct itself.
Always cap the steps. A loop without a limit will eventually run forever.
In production, use native tool calling instead of parsing text; the loop is the same.
[02]
How the ReAct loop works
Each turn of the loop has three parts:
Thought: the model writes what it needs next.
Action: the model names a tool and its input, as tool[input], and stops there.
Observation: your code runs the tool and adds its result.
The loop repeats until the model writes a Final Answer instead of an Action.
The paper's motivation: chain-of-thought alone reasons only over what the model already knows, so it can hallucinate facts and carry errors forward. Acting alone (tool calls without reasoning) loses track of the plan. Interleaving them lets reasoning "induce, track, and update action plans as well as handle exceptions", while actions fetch real information. On HotpotQA and FEVER, ReAct with a simple Wikipedia API reduced hallucination compared with chain-of-thought; on the ALFWorld and WebShop decision-making benchmarks it beat imitation and reinforcement learning baselines by 34 and 10 points of success rate, with one or two in-context examples.
The model never runs anything. It writes text that names a tool and an input. Your controller decides whether to run it.
[03]
When to use ReAct (and when not to)
ReAct fits when the next step depends on what the last step returned: search, lookup, debugging, research, support questions that need account data. It's a poor fit when the steps are known in advance (write a plan and execute it instead, see planning API calls), when there are many independent calls that could run in parallel, or when one tool call answers the question. For a comparison of ReAct with plan-and-execute, reflection and code-action on the same tasks, see AI agent reasoning patterns.
[04]
Step 1: Define two tools
import ast, operator, re

DOCS = {
    "pricing": "Team plan: $12 per seat per month. Business plan: $25 per seat per month.",
    "annual billing": "Paying annually gives 15% off the monthly price. Annual plans are billed once per year.",
    "seats": "You can add seats at any time. Removed seats are credited at the next renewal.",
}

def search_docs(query: str) -> str:
    words = set(re.findall(r"\w+", query.lower()))
    hits = [f"[{k}] {v}" for k, v in DOCS.items() if words & set(re.findall(r"\w+", (k + " " + v).lower()))]
    return "\n".join(hits[:2]) or "no results"

OPS = {ast.Add: operator.add, ast.Sub: operator.sub, ast.Mult: operator.mul, ast.Div: operator.truediv}

def calculator(expression: str) -> str:
    """Arithmetic only. Parses the expression; never calls eval()."""
    def ev(node):
        if isinstance(node, ast.Constant) and isinstance(node.value, (int, float)):
            return node.value
        if isinstance(node, ast.BinOp) and type(node.op) in OPS:
            return OPS[type(node.op)](ev(node.left), ev(node.right))
        raise ValueError("only + - * / and numbers are allowed")
    return str(round(ev(ast.parse(expression, mode="eval").body), 2))

TOOLS = {"search_docs": search_docs, "calculator": calculator}
The calculator parses the expression into a syntax tree and evaluates only numbers and four operators. The model's input is text from a model; eval() on it would let it run any Python.
[05]
Step 2: Write the ReAct prompt
SYSTEM = """Answer the question by alternating Thought, Action and Observation steps.
Tools:
- search_docs[query]: searches the help center
- calculator[expression]: evaluates arithmetic such as 12*14
Format, one step per reply:
Thought: <what you need next>
Action: <tool name>[<input>]
Stop after the Action line. I will reply with "Observation: ...".
When you know the answer, reply instead with:
Thought: <why you are done>
Final Answer: <answer>
Use only facts from observations. Never compute in your head; use the calculator."""
The original paper used few-shot examples of full trajectories. Current models usually follow a format description like this one without examples. "Stop after the Action line" matters: some models keep going and write the Observation themselves, inventing the tool result. Some reasoning-model APIs don't support stop sequences, so the controller also cuts everything after the first Action.
[06]
Step 3: Write the controller loop
ACTION = re.compile(r"^Action:\s*(\w+)\[(.*)\]\s*$", re.M)

def react(question: str, max_steps: int = 6) -> str:
    messages = [{"role": "system", "content": SYSTEM}, {"role": "user", "content": f"Question: {question}"}]
    for step in range(max_steps):
        reply = llm(messages)                      # one model call
        if "Final Answer:" in reply:
            return reply.split("Final Answer:", 1)[1].strip()
        m = ACTION.search(reply)
        if not m:
            observation = "Error: no Action line found. Use the format Action: tool[input]."
        elif m.group(1) not in TOOLS:
            observation = f"Error: unknown tool {m.group(1)}. Tools: {', '.join(TOOLS)}."
        else:
            try:
                observation = TOOLS[m.group(1)](m.group(2))
            except Exception as e:                 # tool errors go back as observations
                observation = f"Error: {e}"
        reply = reply[: m.end()] if m else reply   # drop anything the model wrote after the Action
        messages += [{"role": "assistant", "content": reply},
                     {"role": "user", "content": f"Observation: {observation}"}]
    return "Stopped: step limit reached without a final answer."
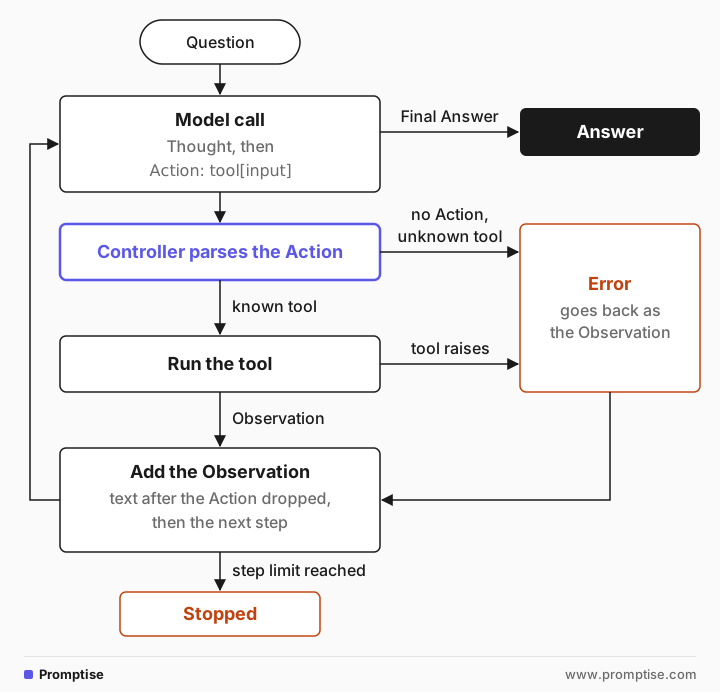
llm() is one chat completion call; here it used gpt-5-mini at minimal reasoning effort. Four things make the loop reliable:
Errors become observations. A bad format, an unknown tool or a failing tool returns text the model can act on, instead of crashing the loop.
Truncation after the Action removes any invented observation.
A step limit ends runaway loops with an explicit message.
Only known tools run. The model can name anything; the controller runs only what's in TOOLS.
[07]
Step 4: Run it
react("We have 14 seats on the Team plan. What do we pay per year if we switch to annual billing?")The full trace:
Thought: I need to find pricing info for Team plan monthly and annual to compute annual cost for 14 seats with annual billing (likely discounted rate). I'll search the help center for Team plan pricing and annual billing details.

Action: search_docs[Team plan pricing annual billing]
Observation: [pricing] Team plan: $12 per seat per month. Business plan: $25 per seat per month.
[annual billing] Paying annually gives 15% off the monthly price. Annual plans are billed once per year.

Thought: I need to calculate the annual cost for 14 seats on the Team plan applying a 15% discount to the monthly price and then multiplying by 12 months and 14 seats. I'll compute step-by-step using the calculator tool.

Action: calculator[(14*(12*(1-0.15))*12)]
Observation: 1713.6

Thought: I have the computed annual cost using the discounted monthly rate and total seats; I'm done.

Final Answer: $1,713.60 per year
Correct: 14 seats × $12 × 0.85 × 12 months = $1,713.60. Three model calls, two tool calls. The trace shows why ReAct is easy to debug: you can see what the model wanted, what it got and how it used it. If the answer were wrong, you'd know whether the search, the expression or the reasoning was at fault.
[08]
From text ReAct to native tool calling
Current model APIs have tool calling built in: you pass tool definitions as JSON schemas, and the model returns structured tool calls instead of Action: lines. The loop is the same, with less parsing:
Text ReAct (this guide) | Native tool calling |
|---|---|
Tools described in the prompt | Tools passed as JSON schemas |
Regex parses Action: tool[input] | The API returns tool_calls with name and JSON arguments |
"Observation:" in a user message | A tool-result message tied to the call id |
Format errors are common | Arguments are structured; schema errors still possible |
Thought is visible text | Reasoning may be hidden; ask for a short plan if you want it visible |
Use text ReAct to learn the pattern, with models that lack tool calling, or when you want the reasoning in plain view. Use native tool calling for anything you ship. How to build an AI agent in Python builds that version step by step, and what an agent harness is covers everything around the loop: context compaction, token budgets, loop guards and verification. Frameworks also ship ReAct as the default; in Promptise Foundry it's the default reasoning pattern, with others (verify, code-action, debate and more) selectable per agent.
[09]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
No step limit | A confused model loops forever | Cap steps; return an explicit "stopped" result |
Letting the model write Observations | It invents tool results and answers from them | Truncate after the Action; add observations only from code |
Crashing on a bad action | One format slip ends the run | Return the error as an observation |
eval() in a calculator tool | Model text becomes code execution | Parse with ast, allow numbers and operators only |
Mental math in the Thought | Arithmetic slips | "Never compute in your head; use the calculator" |
Same call repeated | Wasted steps, then the limit | Detect repeated tool calls with the same input; see agent stuck in a loop |
[10]
Frequently asked questions
What does ReAct stand for?
Reason + Act. The model alternates reasoning steps (Thoughts) with actions (tool calls), and each action's result (Observation) feeds the next reasoning step. The name comes from the 2022 paper by Yao et al.
Is ReAct still used with function calling?
Yes. Native tool calling is the same loop in a structured format: the model reasons, requests a tool call, receives the result and continues. Most agent frameworks implement ReAct this way, and "ReAct agent" usually means this loop.
What's the difference between ReAct and chain-of-thought?
Chain-of-thought reasons only over what's in the prompt and the model's knowledge. ReAct adds actions, so the model can look things up or compute, and its reasoning is grounded in the results. The paper found that this reduced hallucination on fact-based questions.
How many steps should a ReAct agent get?
Enough for your hardest normal task plus a margin. Measure how many steps successful runs take, set the limit somewhat above that, and treat hitting it as a failure to log and review.
ReAct or plan-and-execute?
ReAct when each step depends on the previous result. Plan-and-execute when the steps are predictable, some actions change data, or you want to review the plan before anything runs. See plan-and-execute agents in Python.
[11]
Next steps
Build a production agent with native tool calling: how to build an AI agent in Python.
The same loop as a framework runs it: ReAct agent pattern.
What surrounds the loop: what is an agent harness?
Compare patterns on the same tasks: AI agent reasoning patterns.
Plan first instead: plan-and-execute agents.
Detect and stop loops: AI agent stuck in a loop.
Several agents working together: LLM agent orchestration patterns.