Contents · 8 sections↓
An LLM hallucination is an answer that sounds confident and fluent but is false or unsupported: a made-up citation, a policy that doesn't exist, a date that was never mentioned. This guide is for anyone who uses model output in real work and needs to know when to trust it. It explains why hallucinations happen, which questions are risky, and three quick checks you can add today, with a real fake-citation example and a small Python check.
Why do LLMs hallucinate?
Language models generate the most plausible continuation of the text, not a looked-up fact. When the answer is in the prompt or well covered in training data, plausible and true usually match. When it isn't, the model still produces something plausible, and nothing in the output marks the difference. Training and evaluation have also tended to reward a confident guess over "I don't know".
Key takeaways:
Risky questions are predictable: exact citations, numbers, niche facts, recent events, and anything about your own business.
Allow "I don't know" explicitly. Models tend to abstain more when you make it acceptable.
Ground and cite. Answers tied to a source you supplied are far easier to check.
Check mechanically where you can: look up DOIs, match quotes against the source.
[02]
How hallucinations happen
Survey of Hallucination in Natural Language Generation (Ji et al., 2023) separates two kinds. Intrinsic hallucinations contradict the source you gave. Extrinsic ones add claims the source can't support. Both show up in everyday use: a summary that gets a date wrong (intrinsic), or an answer that adds a refund rule from nowhere (extrinsic).
OpenAI researchers argue in Why Language Models Hallucinate (Kalai et al., 2025) that the problem is partly about incentives. Most benchmarks score a wrong answer and "I don't know" the same, zero, so a model that always guesses scores better than one that admits uncertainty. Models learn to guess. The practical lesson for prompts: tell the model that abstaining is acceptable, and make guessing visible.
[03]
Worked example: citations from memory
A common request:
I'm writing a short internal memo. Give me 3 peer-reviewed studies showing that a four-day work week improves productivity. For each: authors, year, title, journal, DOI, and the key finding in one sentence.The output (trimmed):
1) Author(s): …
Year: 2023
Title: "The 4-Day Week: A Global Trial of Reduced Working Time"
Journal: Nature Human Behaviour
DOI: 10.1038/s41562-023-01692-4
…
2) Author(s): …
Year: 2022
Title: "Working time reduction and productivity: Experimental evidence from a corporate trial"
Journal: Journal of Economic Behavior & Organization
DOI: 10.1016/j.jebo.2022.08.012
…
3) …
Journal: Journal of Applied Psychology
DOI: 10.1037/apl0000850
It looks perfect. Looking up the three DOIs in the Crossref registry:
10.1038/s41562-023-01692-4: not found.
10.1016/j.jebo.2022.08.012: a real paper, titled "Female jockeys - what are the odds?".
10.1037/apl0000850: a real paper about COVID-19 and health care workers.
None of the three citations is what it claims to be. The DOI formats, journals, titles and author names (omitted here) are all plausible, which is exactly why this is dangerous. The request also pushed the model: "give me 3 studies showing X" assumes they exist and asks for precise details the model can't reliably recall.
A safer prompt
I'm writing a short internal memo. List up to 3 peer-reviewed studies on whether a four-day work week improves productivity.

Rules:
- Only list a study if you are confident it exists. Fewer is fine. "I'm not sure" is a good answer.
- Never write a DOI, page number or exact title from memory unless you are certain; write "check" instead.
- For each study, say how confident you are (high / medium / low) and what I should search for to verify it.
- If the evidence is mixed or mostly from non-peer-reviewed pilots, say so.
The output (trimmed):
1) Study: Randomized or quasi-experimental evaluation of a four-day work week in a sample of employees (often cited from Nordic/UK trials)
- Confidence: medium
- What to search for to verify: try keywords like “four-day work week randomized trial productivity peer-reviewed” …
…
Overall summary: The evidence base is mixed. Much of the widely cited positive evidence on productivity comes from organizational pilots and government-commissioned reports rather than peer-reviewed randomized trials. …
If you want, I can run more targeted searches and provide exact citations to verify.
No invented DOIs and an honest note on the evidence. Less satisfying, and far more useful. Note the last line: the model offers to "run searches" it has no tool for. Treat offers like that as another small hallucination. The real fix for citations is a model with a search tool, or you doing the search, then grounding the summary in what you found.
[04]
Three quick checks
1. Spot the risky question before you ask
Be skeptical when the answer needs exact citations, numbers, quotes, recent events, niche facts or anything specific to your organization. For these, either supply the source or verify the answer.
2. Ground the answer and require a quote
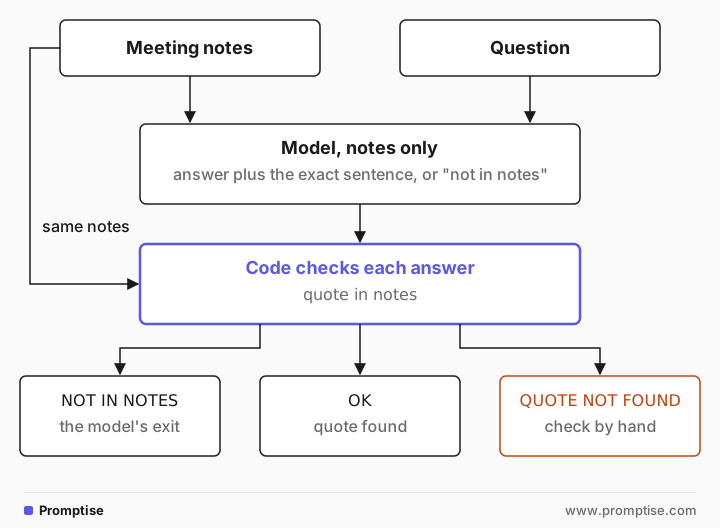
Give the source and ask for the supporting sentence word for word, with an explicit "not in notes" exit. For example, against a set of meeting notes:
Answer each question from the meeting notes only.
For each, return the answer and the exact sentence from the notes that supports it, copied word for word.
If the notes don't contain the answer, set answer to "not in notes" and quote to "".
Asked "Who approved the marketing budget for the campaign?", which the notes never mention, the model returned "answer": "not in notes". See grounding for the full pattern.
3. Check quotes in code
A quote copied word for word can be checked with a substring match:
import json
import sys

notes = open(sys.argv[1]).read()
result = json.load(open(sys.argv[2]))

for item in result["answers"]:
    quote = item["quote"]
    if item["answer"] == "not in notes":
        status = "NOT IN NOTES"
    elif quote and quote in notes:
        status = "OK"
    else:
        status = "QUOTE NOT FOUND, check by hand"
print(f"{status:32} {item['question']}")OK 1. When will the team decide go/no-go for Nov 3?
NOT IN NOTES 2. Who approved the marketing budget for the campaign?
OK 3. When does Tom need to finish regression testing?A failed match doesn't always mean a hallucination (the model may have fixed a typo), but it tells you exactly which answer to read by hand. Exact matching is strict; normalize whitespace and quotes if you get false alarms.
[05]
When these checks are enough (and when not)
These checks catch most problems in everyday use: memos, summaries, support answers, internal Q&A. They are not enough when errors are costly, as with medical, legal or financial content, customer-facing commitments or automated actions. There, add human review, verification loops and tests on real cases. See verification loops and output verification.
[06]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Asking for citations from memory | The model produces plausible fake references | Use search, or verify every DOI and URL |
"Give me 3 studies that show X" | Assumes they exist and invites invention | "Up to 3, fewer is fine, say if unsure" |
No "I don't know" option | Guessing is the default behavior | Make abstaining explicit and acceptable |
Trusting a confidence rating alone | Self-reported confidence is often miscalibrated | Use it to triage, then check the low ones and a sample of the high |
Trusting fluent detail | Detail is not evidence | Ask for a source or quote, then check it |
[07]
Frequently asked questions
Can I make a model stop hallucinating completely?
No. You can make it much rarer and easier to catch: supply sources, allow abstaining, ask for quotes, check them. Newer models hallucinate less on common facts, but no current model is free of it.
Does asking "are you sure?" help?
Sometimes, but it is unreliable. Models may change a correct answer when challenged or defend a wrong one. A specific check, like "quote the sentence that supports this", works better than a general challenge.
Are confidence scores from the model useful?
As a rough signal. A "low" rating is worth reading, but "high" doesn't mean correct. See self-check prompts and confidence fields for how to use them. For a more rigorous method, see semantic entropy.
Do reasoning models hallucinate less?
They make fewer reasoning mistakes on multi-step problems, but they can still invent facts they don't know, such as citations. Grounding and checks matter just as much.
Is a hallucination the same as a lie?
No. The model has no intent. It produces plausible text, and plausible text is sometimes false. That is why the fix is checking, not asking the model to be honest.
[08]
Next steps
Previous in the path: self-check prompts and confidence fields.
Next: beginner eval loops, to measure whether your fixes work.
Stop gaps at the source: grounding.
Stronger checks: verification loops.
Back to the pillar: what is prompt engineering?