Contents · 11 sections↓
- 01How do you evaluate a prompt?
- 02How an eval loop works
- 03Step 1: Build the golden set
- 04Step 2: Write the prompt versions
- 05Step 3: Write the checks
- 06Step 4: Run, log and compare
- 07Step 5: Read the passes too
- 08When to use an eval loop (and when it's overkill)
- 09Common mistakes
- 10Frequently asked questions
- 11Next steps
A prompt eval loop is a small, repeatable test: run your prompt on a fixed set of example inputs, check every output against rules, and compare the pass count before and after each change. This guide is for anyone who edits prompts and wants to know whether an edit helped, without reading every output by hand. You'll build one in about 60 lines of Python, with a real comparison of two prompts.
How do you evaluate a prompt?
Collect 10 to 30 real inputs, including the awkward ones, as a golden set. Write pass/fail checks for what a good output must do. Run each prompt version on the whole set, count passes, and read the failures. Keep the set fixed while you compare versions, and add every new failure you find in real use as a new case.
Key takeaways:
A small fixed set beats impressions. Ten inputs run on every change tell you more than one input you keep retrying.
Include edge cases on purpose: empty input, one-sided input, another language.
Start with checks code can run: format, length, required labels, exact phrases.
Read failures and a few passes. Your checks only catch what you thought of.
Grow the set from real failures. Each bug becomes a test.
[02]
How an eval loop works
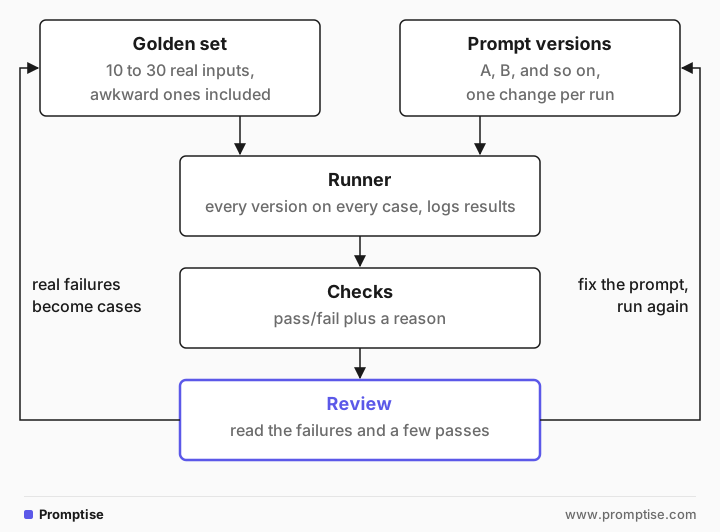
The loop has four parts:
Golden set. Inputs that look like real traffic, each with a short note on why it's there. Some cases carry an expectation, for example "this review has no drawback".
Checks. Functions that return pass/fail plus a reason. Start with things code can verify reliably.
Runner. Runs every prompt version on every case, applies the checks, logs the results.
Review. Read the failures, fix the prompt, run again. Stop when the remaining failures are acceptable.
This guide covers single prompts. For agents, where you also grade tool calls and multi-step behavior, see how to evaluate AI agents. For running prompt tests in pytest and CI, see how to test LLM prompts.
[03]
Step 1: Build the golden set
The task: turn a product review into one "Pro:" line and one "Con:" line. The set mixes normal reviews with cases that trip up a naive prompt:
GOLDEN = [
    {"id": "R1", "review": "Loved the camera quality and battery life. Case felt cheap and slippery."},
    {"id": "R2", "review": "Package arrived late. Support apologized quickly and refunded shipping."},
    {"id": "R3", "review": "Keyboard is quiet and comfortable, but Bluetooth pairing drops every hour."},
    {"id": "R4", "review": "Perfect. Does exactly what it says. Would buy again.", "no_con": True},
    {"id": "R5", "review": "Stopped working after two days. Waste of money.", "no_pro": True},
    {"id": "R6", "review": "ok"},
    {"id": "R7", "review": "Great sound for podcasts; bass is weak for music. Price is fair."},
    {"id": "R8", "review": "Le casque est confortable mais la batterie dure seulement 4 heures."},
]
R4 has no drawback, R5 no advantage, R6 almost no content, R8 is in French. In a real project, take these from actual inputs; the awkward ones are usually easy to find.
[04]
Step 2: Write the prompt versions
PROMPTS = {
    "A": """Summarize this product review as one pro and one con.

Review: {review}""",
    "B": """Summarize this product review in exactly two lines of plain text:
Pro: <one advantage the reviewer mentions>
Con: <one drawback the reviewer mentions>

Rules:
- Each line is at most 15 words. No bullets, no extra lines, no emojis.
- Use only what the review says. If it mentions no advantage, write "Pro: none mentioned".
  If it mentions no drawback, write "Con: none mentioned".
- Write in English even if the review is in another language.

Review: {review}""",
}[05]
Step 3: Write the checks
import re

def check(output, case):
    lines = [l.strip() for l in output.strip().splitlines() if l.strip()]
    if len(lines) != 2:
        return False, f"{len(lines)} lines"
    pro, con = lines
    if not pro.startswith("Pro:") or not con.startswith("Con:"):
        return False, "missing Pro:/Con: labels"
    if max(len(pro.split()), len(con.split())) > 15:
        return False, "line over 15 words"
    if case.get("no_con") and con.lower() != "con: none mentioned":
        return False, "invented a con"
    if case.get("no_pro") and pro.lower() != "pro: none mentioned":
        return False, "invented a pro"
    if re.search(r"[\U0001F300-\U0001FAFF]", output):
        return False, "emoji"
    return True, "ok"
Each check returns a reason, so a failure tells you what to fix.
[06]
Step 4: Run, log and compare
import csv
from openai import OpenAI

client = OpenAI()

def run(prompt):
    r = client.chat.completions.create(model="gpt-5-mini", reasoning_effort="minimal",
                                       messages=[{"role": "user", "content": prompt}])
    return r.choices[0].message.content

with open("eval_log.csv", "w", newline="") as f:
    log = csv.writer(f)
    log.writerow(["variant", "case", "passed", "reason", "output"])
    for variant, template in PROMPTS.items():
        passed = 0
        for case in GOLDEN:
            out = run(template.format(**case))
            ok, reason = check(out, case)
            passed += ok
            log.writerow([variant, case["id"], ok, reason, out])
            if not ok:
                print(f"  {variant} {case['id']} FAIL: {reason}")
        print(f"Prompt {variant}: {passed}/{len(GOLDEN)} passed")
The output:
  A R4 FAIL: invented a con
  A R5 FAIL: invented a pro
Prompt A: 6/8 passed
Prompt B: 8/8 passed
The two failures are exactly the cases the golden set was built to catch. For R5, prompt A produced "Pro: Affordable initial purchase (implied)." The review says nothing about price.
[07]
Step 5: Read the passes too
The CSV shows what the checks missed. Two of prompt A's "passes":
A,R6,True,ok,"Pro: Simple and straightforward — the reviewer found the product acceptable.
Con: Lacks detail — the review is too brief to convey specific strengths or weaknesses."
A,R8,True,ok,"Pro: Casque confortable.
Con: Autonomie de batterie limitée à environ 4 heures."
R6 invents a pro from the word "ok", and R8 answers in French. Both pass because no check covers them. Prompt B handled both ("Pro: none mentioned / Con: none mentioned" for R6, English for R8), but the checks didn't prove it. The fix is to improve the eval: mark R6 with no_pro and no_con, and add a language check for R8. A passing score only means the outputs passed the checks you wrote.
For qualities code can't check, such as "is this con actually in the review?", you can add an LLM judge with a narrow yes/no question, then compare its verdicts with your own on a sample before trusting it. See LLM as a jury, not a judge.
[08]
When to use an eval loop (and when it's overkill)
Use one as soon as a prompt runs more than a handful of times or other people depend on it: extraction, classification, summaries, support replies. Rerun it whenever you change the prompt, the model or the input format. For a one-off prompt you'll use once, reading the output is enough.
Results vary between runs, because model outputs aren't fully deterministic. If a case flips between pass and fail, run it a few times and treat it as unstable rather than fixed.
[09]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Testing on one favorite input | One input hides most failures | 10 to 30 varied cases |
Only easy cases | Every prompt passes | Add empty, one-sided, foreign-language and long inputs |
Changing the golden set mid-comparison | Scores stop being comparable | Freeze the set per comparison; add cases between rounds |
Vague checks like "is it good?" | Can't be scored consistently | Pass/fail rules with reasons |
Trusting the pass count | Checks miss what you didn't anticipate | Read failures and a sample of passes |
Changing several things at once | You can't tell what helped | One change per run |
[10]
Frequently asked questions
How many test cases do I need?
Start with 10 to 20 that cover normal and awkward inputs. Add every real failure you find. A small set you actually run beats a large one you don't.
What is a golden set?
A fixed list of example inputs, sometimes with expected outputs or expectations, that you reuse to test every version of a prompt. It's the prompt equivalent of a unit test suite.
Can I use an LLM to grade outputs?
Yes, for qualities code can't check, such as relevance or tone. Ask a narrow question, require a short reason, and compare the judge's verdicts with your own on a sample first. Use code checks wherever they work.
How is this different from unit testing?
Unit tests usually expect one exact result. Prompt evals check properties of outputs that vary, and they track a pass rate across many inputs rather than a single pass.
When should I stop iterating?
When the remaining failures are rare, understood and acceptable for the use case, or when changes stop improving the pass rate. Then freeze the prompt and keep the eval for the next change.
[11]
Next steps
Previous in the path: LLM hallucinations and quick checks.
Improve the prompt between runs: iterative prompt refinement.
Let a model search for a better prompt against your golden set: automatic prompt optimization.
Move the loop into pytest and CI: how to test LLM prompts.
Evaluate agents, not just prompts: how to evaluate AI agents.