Contents · 9 sections↓
Semantic entropy measures how unsure a model is about an answer by asking the same question several times and checking whether the answers mean the same thing. If they agree, the model probably knows. If they scatter, it is likely making something up. This guide is for developers who need a system to say "I don't know", look something up, or hand off to a person instead of guessing. It covers the research method, a runnable Python version with real output, and a routing rule.
What is an uncertainty-aware prompt?
An uncertainty-aware prompt lets the model say how sure it is, and tells it what to do when it isn't sure: answer, say "I don't know", ask a question, or look something up. A plain prompt pushes the model to always produce an answer. An uncertainty-aware one makes "not sure" an allowed, useful output:
Answer the question below from what you know.
If you are not sure of the answer, say "I don't know" and name the fact you would need to check.
Do not guess dates, names or numbers.
Question: {question}
That is the cheap first step, and it helps. Its limit is that the model judges itself: models that state their confidence in words tend to be overconfident, as Xiong et al. (ICLR 2024) found. The stronger version measures uncertainty from outside the model's own claim. Ask the same question several times and check whether the answers agree. That measurement is semantic entropy, and the rest of this guide builds it.
[02]
What is semantic entropy?
Semantic entropy is the entropy of a model's answers after grouping them by meaning. Sample several answers to one question, cluster answers that say the same thing in different words, and compute the entropy of the cluster sizes. Low entropy means the answers agree; high entropy means they don't, which signals that the model is confabulating.
Key takeaways:
Group by meaning, not by string. "1889" and "It was completed in 1889." are one answer.
It catches inconsistent guessing, not errors the model makes the same way every time.
It costs 5 to 10 short samples plus one grouping call, so use it on factual questions where a wrong answer is expensive.
Turn the score into a policy: answer, answer with a source, retrieve first, or abstain. Set the thresholds on your own labeled questions.
[03]
How semantic entropy works
Semantic Uncertainty: Linguistic Invariances for Uncertainty Estimation in Natural Language Generation (Kuhn, Gal and Farquhar, 2023) starts from a problem with ordinary entropy over outputs: different sentences can mean the same thing, so a model that knows the answer but phrases it five ways looks uncertain. Semantic entropy fixes that in three steps:
Sample several answers to the same question.
Cluster them by meaning. The paper treats two answers as equivalent when each entails the other (bidirectional entailment), checked with a natural language inference model.
Compute entropy over the clusters.
The paper found semantic entropy more predictive of whether an answer is correct than comparable baselines. A follow-up, Detecting hallucinations in large language models using semantic entropy (Farquhar, Kossen, Kuhn and Gal, Nature, 2024), applied it to detecting confabulations: arbitrary, wrong answers. It also describes a discrete version that needs only the sampled texts, not token probabilities, which is what you can use with closed APIs. The paper reports that the discrete version performs similarly.
Discrete semantic entropy, for n samples grouped into clusters of sizes c₁, c₂, …:
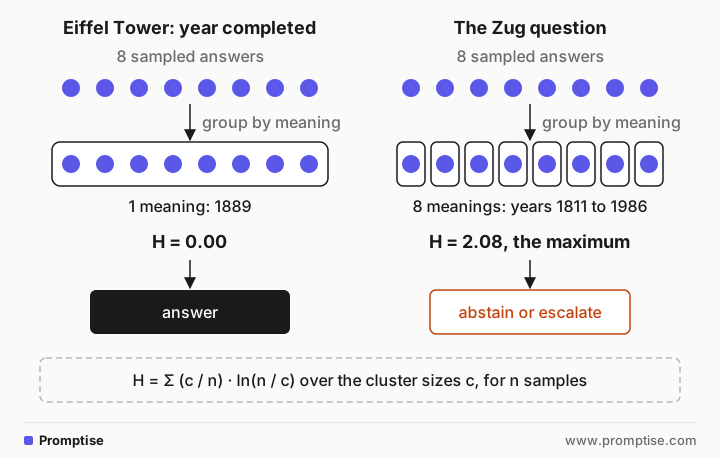
H = Σ (cᵢ / n) · ln(n / cᵢ)All answers in one cluster gives H = 0. Every answer different gives the maximum, ln(n), which is 2.08 for n = 8.
[04]
Worked example: three questions
The code samples 8 short answers per question at the model's lowest reasoning setting, groups them with one structured-output call, and computes H:
import json
import math
import re

CLUSTER = """Question: {q}
Answers:
{answers}

Group answers that give the same answer to the question. Ignore wording, punctuation and extra
detail that doesn't change the answer. Answers with different values go in different groups.
Put every answer number in exactly one group."""

GROUPS = {"type": "json_schema", "json_schema": {"name": "groups", "strict": True, "schema": {
    "type": "object", "additionalProperties": False, "required": ["groups"],
    "properties": {"groups": {"type": "array", "items": {"type": "array", "items": {"type": "integer"}}}}}}}


def split_by_numbers(groups: list[list[int]], answers: list[str]) -> list[list[int]]:
    """Guardrail: answers with different numbers (years, amounts) never share a meaning group."""
    out = []
    for g in groups:
        by_num = {}
        for i in g:
            by_num.setdefault(tuple(re.findall(r"\d+", answers[i - 1])), []).append(i)
        out.extend(by_num.values())
    return out


def semantic_entropy(q: str, n: int = 8) -> tuple[float, list[str]]:
    answers = ask(q + " Answer in a few words.", n=n)  # n samples in one request
    numbered = "\n".join(f"{i}. {a.strip()}" for i, a in enumerate(answers, 1))
    reply = ask(CLUSTER.format(q=q, answers=numbered), effort="low", response_format=GROUPS)
    groups = split_by_numbers(json.loads(reply)["groups"], answers)
    entropy = sum(len(g) / n * math.log(n / len(g)) for g in groups)
    return entropy, [f"{len(g)}x {answers[g[0] - 1].strip()}" for g in groups]
ask() wraps the chat API and returns a list when n is above 1. The output, with the number of distinct strings added for comparison:
In what year was the Eiffel Tower completed?
  2 distinct strings, 1 meanings, semantic entropy 0.00 (max 2.08)
  ['8x 1889.']

What is the main ingredient of guacamole?
  3 distinct strings, 1 meanings, semantic entropy 0.00 (max 2.08)
  ['8x Avocado (ripe)']

In what year did the Swiss town of Zug open its first public library?
  8 distinct strings, 8 meanings, semantic entropy 2.08 (max 2.08)
  ['1x 1829', '1x 1986', '1x 1849', '1x 1886', '1x 1841', '1x 1847', '1x 1811', '1x 1826']
The first two questions get several spellings but one meaning, so H = 0: answer them. The third gets eight different years from 1811 to 1986. Each sample sounded just as confident as the Eiffel Tower answer; only the spread gives it away. That question should not be answered from the model's memory.
Two ways the grouping step can go wrong
The grouping call is the fragile part, and it can fail in both directions:
Merging different answers. A looser grouping prompt put eight different years for the Zug question into four groups, which lowered H from the true 2.08 to 1.21. That would pass a guessed answer as fairly confident. The split_by_numbers guardrail in the code above prevents that for numeric answers.
Splitting the same answer. A grouping call can also put "Avocado" and "Avocado (mashed)" into separate groups, giving H = 0.56 for a question the model clearly knows. The prompt above says to ignore extra detail that doesn't change the answer, and the grouping call runs with a little more reasoning.
Test the grouping step on your own question types before trusting the scores. For short factual answers, normalize in code (numbers, dates, names) and use the model only for the rest.
[05]
Turning the score into a policy
Semantic entropy is useful only when it changes what the system does. A simple router:
def route(entropy: float) -> str:
    if entropy < 0.5:
        return "answer"                 # samples agree
    if entropy < 1.2:
        return "answer_with_source"     # retrieve and cite, or add a caveat
    return "abstain_or_escalate"        # "I don't know", search, or a human
Those thresholds are placeholders. To set real ones, collect 50 to 100 questions from your domain with known answers, compute H for each, and pick the cut-off where wrong answers start to dominate. What a wrong answer costs decides how strict to be: a support bot can retrieve on doubt, a medical or legal assistant should abstain.
For the abstain path, give the model a way to say so and mean it; see hallucination basics. For the retrieve path, see grounding with context.
[06]
When to use semantic entropy (and when not to)
Use it when | Skip it when |
|---|---|
Short factual answers from model memory: names, dates, numbers, yes/no facts | The answer comes from retrieved documents you can check directly |
A wrong answer costs more than eight extra short calls | Creative or open-ended tasks, where variety is expected |
You need a trigger for retrieval, abstention or human review | You need one guarantee per answer; the score is a probability-like signal, not a proof |
You can't get token probabilities (closed APIs, reasoning models) | You have open weights and can use cheaper probe-based methods |
On that last row: Semantic Entropy Probes (Kossen et al., 2024) train a small probe on a model's hidden states to predict semantic entropy from a single generation. That removes the sampling cost but needs access to the model's internals.
What changes with reasoning models
Reasoning models often don't expose token probabilities, which rules out log-probability methods, so sampling-based checks like this one are one of the few options left. Two practical adjustments:
Sample at a low reasoning setting. You want the model's spread of beliefs, not eight long deliberations. The short samples above cost little. (How reasoning settings work is covered in chain-of-thought for beginners.)
Remember what it can't see. A reasoning model that is consistently wrong gives H = 0. In the self-consistency guide, five samples all answered "1" to a question whose answer is 3. Low entropy means "the model is consistent", not "the model is right".
Asking the model for a confidence number in the same answer is cheaper but often poorly calibrated; see self-check prompts and confidence fields for when that is enough.
[07]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Counting distinct strings | Wording differences look like uncertainty | Group by meaning before computing entropy |
Trusting the grouping call blindly | It can merge different answers or split identical ones | Normalize numbers and names in code; test grouping on your data |
Long, free-form samples | Hard to group, and every sample differs in detail | Ask for a short answer: "Answer in a few words" |
Temperature 0 or identical samples | No spread, so H is always low | Default sampling; reasoning models already vary |
Thresholds picked by feel | Too strict blocks good answers, too loose lets guesses through | Calibrate on 50 to 100 labeled questions |
Reading H = 0 as "correct" | Systematic errors are consistent | Pair with retrieval or checks for high-stakes answers |
[08]
Frequently asked questions
How many samples does semantic entropy need?
The example uses 8, which gives a maximum H of 2.08 and enough resolution to separate "agrees" from "scatters". Five works for a rough signal. Request them in one call with an n parameter where the API supports it, which saves resending the prompt.
Is semantic entropy the same as self-consistency?
They use the same raw material, several samples. Self-consistency takes the majority answer to improve accuracy. Semantic entropy measures how spread out the answers are, to decide whether to answer at all.
What's the difference between semantic entropy and SelfCheckGPT?
SelfCheckGPT scores each sentence of one long answer by how well other samples support it. Semantic entropy scores the whole answer to a question. Use SelfCheckGPT to find risky sentences in a paragraph, semantic entropy to decide whether to answer a short question. See verification loops.
Can I compute semantic entropy without an LLM for grouping?
Yes, for answers that normalize cleanly: years, numbers, multiple-choice letters, entity names matched against a list. The paper used an NLI model for grouping, which is cheaper than an LLM call and works for short sentences.
Does semantic entropy detect all hallucinations?
No. It detects confabulations, where the model gives different arbitrary answers. It does not detect errors the model repeats consistently, such as a wrong fact learned in training.
[09]
Next steps
Why models make things up, and quick checks: hallucination basics.
Fix the answer instead of scoring it: verification loops with CoVe and SelfCheckGPT.
Cheaper, rougher signal: self-check prompts and confidence fields.
Voting on the samples instead: self-consistency and least-to-most.
Route hard questions to a bigger model: query routing.
Uncertainty also picks examples: active prompting.