Contents · 9 sections↓
- 01How do you get a useful confidence score from an LLM?
- 02What the research says about self-reported confidence
- 03The weak version: "rate your confidence 1 to 5"
- 04The better version: basis, quote, confidence, check
- 05Route answers in code
- 06When to use confidence fields (and when not)
- 07Common mistakes
- 08Frequently asked questions
- 09Next steps
A confidence field is an extra field in the model's output that says how sure it is and why: a rating, the basis for the answer, and what to check. This guide is for anyone who uses model answers in a workflow and wants to know which ones to trust, review or reject. It shows why a bare "rate your confidence 1 to 5" tells you little, and how to design self-check fields that your code can act on, with a real example and output.
How do you get a useful confidence score from an LLM?
Don't ask for a number alone. Ask for fields the model can fill from evidence: the basis of the answer (quoted from your source, calculated, or not found), the quote it relied on, a confidence level with defined meanings, and one thing to check. Then let code, not the model, decide what happens: accept, review or say "unknown".
Key takeaways:
Bare 1 to 5 scores bunch at the top. Research finds verbalized confidence tends to be overconfident.
"Basis" beats "confidence". Whether the answer came from your source, from a calculation or from nowhere is easier for the model to report and for you to act on.
Define every level. "High only if the quote states the answer directly" is checkable. "Very sure" is not.
Verify what you can in code. A quote either appears in the source or it doesn't.
[02]
What the research says about self-reported confidence
Models can express uncertainty in words, and it carries some signal. Just Ask for Calibration (Tian et al., 2023) found that for chat models such as ChatGPT, GPT-4 and Claude, confidence stated in the output was often better calibrated than the model's internal token probabilities. Can LLMs Express Their Uncertainty? (Xiong et al., ICLR 2024) also found that verbalized confidence tends to be overconfident, possibly imitating how people talk, and that calibration improves with model capability and with methods such as sampling several answers and checking whether they agree.
So treat a confidence field as a triage hint, not a probability. It is most useful when it is tied to something you can check, which is what the rest of this guide does. For the general problem of made-up answers, see LLM hallucinations: why they happen and quick checks.
[03]
The weak version: "rate your confidence 1 to 5"
The task: answer four questions about a short pricing page for a fictional backup service. One answer is quoted directly, one needs arithmetic, two are not on the page.
Answer these questions about the page below. After each answer, rate your confidence from 1 to 5.

Acme Cloud Backup - Plans (updated March 2026)
Personal: $6 per month, 1 TB storage, 1 user, file versions kept for 30 days.
Team: $15 per user per month, minimum 3 users, 5 TB shared storage, file versions kept for 180 days.
All plans: encryption at rest, restore from the web app or desktop client.
Annual billing gives 2 months free.

Questions:
1. How long are file versions kept on the Team plan?
2. What does a Team plan for 4 users cost per year with annual billing?
3. Does the Personal plan include phone support?
4. What encryption algorithm does Acme use?
The output:
1. File versions on the Team plan are kept for 180 days. — Confidence: 5
2. 4 users × $15/user/month = $60/month. With annual billing (2 months free) you pay for 10 months = $60 × 10 = $600 per year. — Confidence: 5
3. The page does not state that the Personal plan includes phone support (no phone support is mentioned). — Confidence: 4
4. The page only says “encryption at rest”; it does not specify which encryption algorithm is used. — Confidence: 5
The answers are good. The scores are not useful: a direct lookup and a calculation that depends on interpreting "2 months free" both get a 5, and nothing tells your code which answers came from the page. A 5 means something different in every line.
[04]
The better version: basis, quote, confidence, check
Put the field definitions in the system prompt and enforce the shape with structured outputs:
Answer questions using only the product page the user provides.
For every question, fill all fields:
- answer: the answer, or "not on the page".
- basis: "quoted" if a sentence on the page states it, "calculated" if you derived it from numbers on the page,
  "not_on_page" if the page doesn't say. Never answer from general knowledge.
- quote: the sentence from the page you relied on, copied exactly. Empty string if basis is not_on_page.
- confidence: "high" only if the quote states the answer directly. "medium" if you calculated or interpreted.
  "low" if you are unsure.
- check: one short thing a person should verify before using this answer.
The JSON schema makes basis an enum (quoted, calculated, not_on_page) and confidence an enum (high, medium, low). The output for the same four questions, trimmed:
{"question": "How long are file versions kept on the Team plan?",
 "answer": "File versions are kept for 180 days.", "basis": "quoted",
 "quote": "Team: $15 per user per month, minimum 3 users, 5 TB shared storage, file versions kept for 180 days.",
 "confidence": "high", "check": "Verify the retention period in the full plan terms or FAQ in case of recent changes."}

{"question": "What does a Team plan for 4 users cost per year with annual billing?",
 "answer": "$600 per year.", "basis": "calculated",
 "quote": "Team: $15 per user per month, minimum 3 users, 5 TB shared storage, file versions kept for 180 days. Annual billing gives 2 months free.",
 "confidence": "medium", "check": "Confirm the annual billing discount is applied as \"2 months free\" on the checkout …"}

{"question": "Does the Personal plan include phone support?",
 "answer": "not on the page", "basis": "not_on_page", "quote": "", "confidence": "low", …}

{"question": "What encryption algorithm does Acme use?",
 "answer": "not on the page", "basis": "not_on_page", "quote": "", "confidence": "low", …}
Now the fields separate the three kinds of answer, and the calculated one is marked medium with a specific thing to check.
[05]
Route answers in code
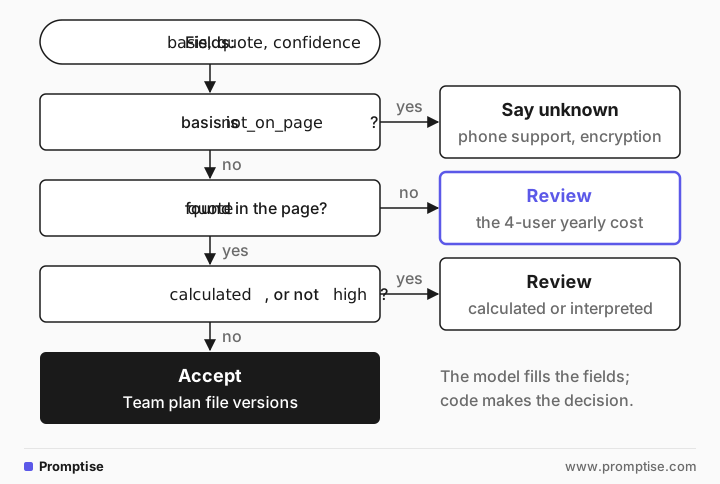
The model's fields are inputs to a decision you make in code:
def route(item, page):
    if item["basis"] == "not_on_page":
        return "SAY UNKNOWN"
    if item["quote"] not in page:
        return "REVIEW (quote not found)"
    if item["basis"] == "calculated" or item["confidence"] != "high":
        return "REVIEW"
return "ACCEPT"ACCEPT How long are file versions kept on the Team plan?
REVIEW (quote not found) What does a Team plan for 4 users cost per year with annual billing?
SAY UNKNOWN Does the Personal plan include phone support?
SAY UNKNOWN What encryption algorithm does Acme use?The second answer was sent to review for a reason the model didn't report: its "quote" joins two separate lines of the page, so it isn't an exact copy. The answer is right, but this is exactly the kind of mismatch a code check catches and a confidence score hides. If joined quotes are normal for your task, make quote a list of sentences and check each one.
Notice also that the model gave confidence: "low" to "not on the page", although it is quite sure the page doesn't say. That's because the definition only covered answers. Define what confidence means for every basis, or ignore it when the basis is not_on_page.
[06]
When to use confidence fields (and when not)
Use them when answers feed a decision or another system: support answers, extraction, internal Q&A over documents, triage queues. They are cheap, a few extra tokens per answer, and they make review targeted.
Don't rely on them alone when a wrong answer is costly. A model can be confidently wrong, and self-checks share the model's blind spots. For stronger signals, sample the answer several times and check agreement (semantic entropy) or run a separate verification pass (verification loops).
[07]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
A bare 1 to 5 score | Scores bunch at 4 to 5 and mean different things per answer | Use defined levels tied to evidence |
No basis field | You can't tell a lookup from a guess | Add basis with fixed values |
Letting the model decide what to do | The model is grading itself | Route on the fields in code |
Long reasoning in the self-check | Adds tokens without adding checks | One short check line |
Never checking high-confidence answers | Overconfidence is the common failure | Spot-check a sample of high answers |
Undefined levels for "unknown" | The model picks an arbitrary rating | Define confidence for every basis |
[08]
Frequently asked questions
Are LLM confidence scores reliable?
Partly. Research finds stated confidence carries signal but tends to be overconfident, and calibration varies by model and task. Use it to sort answers for review, never as proof of correctness.
Should I use numbers or words for confidence?
Words with definitions ("high only if quoted directly") are easier to keep consistent than numbers. If you need numbers, define each value the same way and test whether low scores really mark worse answers on your own examples.
What is a self-check prompt?
A prompt that asks the model to assess its own answer in the output, for example by naming its basis, quoting its source or listing what to verify. It costs little and works best when your code can check the result.
Can I get token probabilities instead?
Some APIs return log probabilities for output tokens. They can help on short, fixed answers such as labels. On question-answering benchmarks, the Tian et al. study found that chat models' stated confidence was often better calibrated than their token probabilities.
Does this replace evals?
No. Confidence fields help per answer at run time. An eval loop tells you whether the prompt works across many inputs, including whether its "high" answers are actually right.
[09]
Next steps
Next in the path: LLM hallucinations: why they happen and quick checks.
Get the fields back as valid JSON: structured outputs.
Give the model a source to quote: grounding LLM answers.
Stronger uncertainty signals: semantic entropy and verification loops.
Measure the whole prompt: beginner eval loops.