Contents · 11 sections↓
- 01What is Chain of Density prompting?
- 02How Chain of Density works
- 03The example article
- 04A plain summary first
- 05Chain of Density, three rounds
- 06A practical version: one densify pass
- 07Check the result in code
- 08When to use Chain of Density (and when not)
- 09Common mistakes
- 10Frequently asked questions
- 11Next steps
Chain of Density (CoD) is a summarization prompt that makes a summary more specific without making it longer: in each round, the model finds important names, numbers or dates that the summary is missing and rewrites it to include them at the same length. This guide is for anyone who gets summaries that read well but leave out the details that matter. It explains the original technique, shows real output, and gives a lighter one-round version that works well with current models.
What is Chain of Density prompting?
Chain of Density is a prompt from From Sparse to Dense: GPT-4 Summarization with Chain of Density Prompting (Adams et al., 2023). The model writes a deliberately vague first summary, then repeats two steps several times: list 1 to 3 informative entities missing from the summary, and rewrite the summary to include them without adding words. Each round packs more facts into the same length.
Key takeaways:
Density is not length. The same word budget can hold filler or facts.
The paper found a sweet spot. Its annotators preferred summaries denser than GPT-4's plain ones, about as dense as human-written ones: the middle rounds, not the densest.
Too dense hurts readability. Late rounds turn into long, packed sentences.
Check what got dropped. Making room for new entities can push out old ones.
With newer models, one densify pass on a normal summary is often enough.
[02]
How Chain of Density works
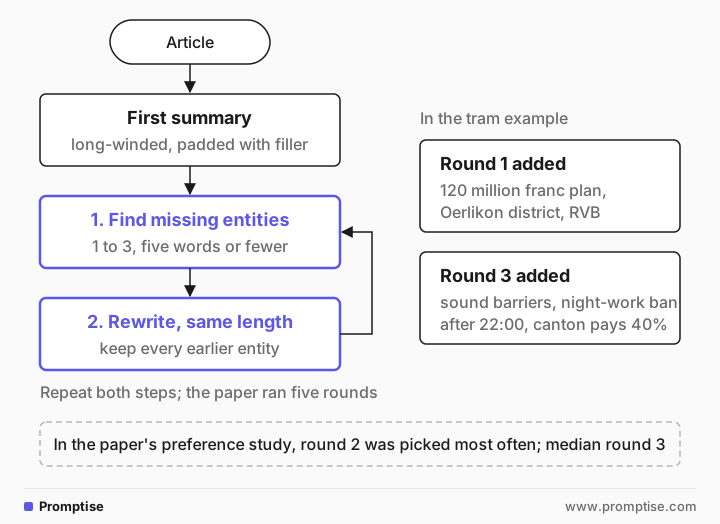
The paper's prompt asks the model to repeat two steps five times and answer in JSON:
Identify 1 to 3 informative entities from the article that are missing from the previous summary.
Write a new, denser summary of identical length that covers every entity and detail from the previous summary plus the missing ones.
A "missing entity" must be relevant to the main story, specific yet concise (five words or fewer), novel (not in the previous summary), faithful (present in the article) and can come from anywhere in the article. The first summary is meant to be long-winded and non-specific, padded with phrases like "this article discusses", so later rounds have room to swap filler for facts. The model makes space through fusion, compression and removing uninformative phrases, and must never drop an entity.
The paper's first summary is about 80 words in 4 to 5 sentences. The authors ran five rounds on 100 CNN/DailyMail news articles. In their preference study, in which four of the authors picked their favorite round for each article, round 2 was chosen most often and the median pick was round 3. Overall, they report that people prefer summaries more dense than GPT-4's vanilla ones and almost as dense as human-written ones, with a trade-off between informativeness and readability. The prompt and data are public on Hugging Face.
[03]
The example article
A short, fictional news item about a tram extension (about 190 words), with many specifics: a 120 million franc budget, five stops, waits cut from 9 to 6 minutes, a pilot bus lane on Hofwiesenstrasse from October 2025 to March 2026, a merchants' association, a night-work ban after 22:00, a projected 12% drop in car trips, 40% cantonal funding if federal money is confirmed by mid-2026, construction from the first quarter of 2027, service from December 2028, and a council member, Ana Ruiz, who voted against.
[04]
A plain summary first
Summarize this article in about 60 words.The output (63 words):
Brenntal city council approved a 120 million franc plan to extend the Blue Line tram to Oerlikon by December 2028. The RVB proposal adds five stops, upgrades signaling to cut waits from 9 to 6 minutes, and funds sound barriers with a night-work ban after 22:00. A trial bus lane runs Oct 2025–Mar 2026. Canton covers 40% if federal aid arrives by mid‑2026.That's already dense. The model left out the opposition (Ana Ruiz), the merchants' concerns, the 12% projection and the street name, which is a reasonable choice at 60 words. Current models often write tighter plain summaries than the GPT-4 version studied in 2023, so always look at a plain summary before reaching for CoD.
[05]
Chain of Density, three rounds
The paper's prompt, shortened to three rounds and a 60-word target:
You will write increasingly concise, entity-dense summaries of the article above. Repeat these two steps 3 times.

Step 1. Identify 1-3 informative entities from the article that are missing from the previous summary.
Step 2. Write a new, denser summary of identical length that covers every entity and detail from the
previous summary plus the missing entities.

A missing entity is: relevant to the main story; specific yet concise (5 words or fewer); not in the
previous summary; faithful (present in the article); and can be from anywhere in the article.

Guidelines:
- The first summary should be about 60 words but non-specific, containing little information beyond
  the entities marked as missing. Use filler phrases like "this article discusses" to reach about 60 words.
- Make every word count: rewrite the previous summary to improve flow and make space for new entities.
- Make space with fusion, compression, and removal of uninformative phrases.
- Never drop entities from the previous summary. If space can't be made, add fewer new entities.
- Every summary has the same length (about 60 words).

Answer in JSON: {"rounds": [{"missing_entities": "...", "summary": "..."}]}
Round 1 and round 3 of the output:
ROUND 1 (57 words) added: 120 million franc plan; Oerlikon district; RVB (regional transport authority)
This article discusses a 120 million franc plan proposed by RVB to extend the Blue Line into the Oerlikon district. It outlines approvals, projected impacts, and mitigation measures. The piece summarizes council debates, schedules, funding conditions, local reactions, and environmental positions. …

ROUND 3 (63 words) added: sound barriers; night-work ban after 22:00; canton pays 40%
This article discusses a 120 million franc plan proposed by RVB to extend the Blue Line into the Oerlikon district, adding five stops and replacing signaling to reduce waits. It outlines approvals, a pilot bus lane, mitigation measures including sound barriers and a night-work ban after 22:00, projected impacts, and funding—the canton would pay 40% if federal co-funding is confirmed—plus debates and schedules.
The mechanics work: same length, more entities each round, and every number traces back to the article. But after three rounds, the summary still carries filler ("This article discusses", "plus debates and schedules") and has fewer facts than the plain summary. The full technique runs five rounds because it starts so sparse. It's most useful when you want to study or control the density level, for example to generate summaries at several densities and pick one.
[06]
A practical version: one densify pass
For everyday use, start from a normal summary and run a single CoD-style round on it:
Article:
{article}

Summary:
{summary}

Step 1. List the 1-3 most important entities (names, numbers, dates, places) from the article that are missing
from the summary. Each must appear in the article.
Step 2. Rewrite the summary to include them without making it longer: keep it at {words} words or fewer.
Make space by merging sentences and cutting less important details. Do not add anything that is not in the article.

Answer in JSON: {"missing_entities": ["..."], "summary": "..."}
Run on the plain summary above, the output was:
added: ['RVB', 'Hofwiesenstrasse', 'Ana Ruiz']
(62 words)
Brenntal council approved a 120 million franc plan by regional transport authority RVB to extend the Blue Line tram to Oerlikon by December 2028, adding five stops, upgrading signaling to cut waits from 9 to 6 minutes, funding sound barriers with a night-work ban after 22:00; a pilot bus lane on Hofwiesenstrasse runs Oct 2025–Mar 2026; council member Ana Ruiz voted against.
It added the street and the opposing vote. It also shows both costs the paper describes. The summary is now one 62-word sentence, harder to read than before. And to make room, it dropped the 40% cantonal funding condition, which this prompt allowed ("cutting less important details"). Whether that trade is right depends on the reader. "RVB" was also listed as missing although the original summary had it, so the entity list isn't fully reliable either.
[07]
Check the result in code
Two cheap checks catch the main risks: numbers that aren't in the source (invented), and numbers the previous version had that the new one lost (dropped):
import re

def numbers(text):
    return set(re.findall(r"\d+(?:[.,]\d+)?", text))

def numbers_not_in_source(summary, article):
    return sorted(n for n in numbers(summary) if n not in article)

def dropped_numbers(before, after):
return sorted(numbers(before) - numbers(after))numbers not in source: none
dropped numbers: ['40']The second check flags the lost funding condition immediately. Extend the same idea to names: list the entities you require, and check they survive.
[08]
When to use Chain of Density (and when not)
Use it for news, reports, meeting notes and research papers where names, numbers and dates are the point and the length is fixed, such as a newsletter blurb, a card in a dashboard or a notification. Use the one-pass version when a plain summary is close but misses specifics.
Skip it for very short or vague sources (there's nothing to add), for summaries meant to be skimmed by non-experts (dense text is slower to read), and when you need a fixed list of fields, where structured outputs are simpler. For long documents with many sections, see long-form control.
[09]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Running many rounds on a model that's already dense | Late rounds only cost readability | Look at a plain summary first; often one pass is enough |
Allowing outside knowledge | Added "entities" can be invented | "Each must appear in the article", then check numbers |
Not checking what was dropped | New facts can push out important ones | Diff numbers and key names between versions |
Taking the densest round by default | Readers prefer a middle density | Pick the round a reader can follow |
Fixed word count too small for the source | Forces the model to drop facts | Set the length for the reader, not the minimum |
[10]
Frequently asked questions
Does Chain of Density work with any model?
The prompt works with any capable chat model; the paper tested GPT-4. Results vary by model. Newer models may write dense plain summaries already, which reduces the gain.
How many rounds should I run?
The paper used five, and its annotators most often preferred round 2 or 3. For practical use, start with a plain summary and one densify round, and add rounds only while the summary stays readable.
What counts as an entity?
In the paper, any informative, specific item of five words or fewer from the article: names, organizations, places, dates, numbers, and specific terms.
Can Chain of Density cause hallucinations?
It can if the model adds details not in the source. Require every entity to appear in the article and check numbers and names in code.
How is this different from asking for a shorter summary?
Shorter cuts words; denser swaps vague words for specific facts at the same length. You can combine them: set the length you need, then densify.
[11]
Next steps
Keep the summary grounded in the source: grounding LLM answers.
Control density across long documents: long-form control.
Fit long inputs into the prompt: prompt compression and lost in the middle.
Test summaries across many articles: beginner eval loops.
Catch invented facts: LLM hallucinations.