Contents · 10 sections↓
- 01How do you get an LLM to write a good long-form document?
- 02Why long outputs drift
- 03Worked example: one prompt vs an outline with budgets
- 04Write the style sheet as rules
- 05Check what code can check
- 06When to use outline-first generation (and when not to)
- 07Make the sections read as one document
- 08Common mistakes
- 09Frequently asked questions
- 10Next steps
Long-form LLM writing (articles, reports, documentation, proposals over a thousand words) fails in predictable ways: the length drifts, sections repeat each other, the structure is whatever the model felt like, and the style slides back to generic. This guide shows how to control all four with an outline that carries word budgets, section-by-section generation, a style sheet written as checkable rules, and a few checks in code. It's for developers and content teams generating long documents with an API. A real 1,200-word article is generated both ways.
How do you get an LLM to write a good long-form document?
Plan first, then write in pieces. Ask for an outline with headings, the points each section must make and a word budget per section. Generate each section separately, telling the model what earlier sections covered. Write style as concrete rules, and check length, banned words and sentence length in code before a person reads it. One prompt for the whole document gives you much less control.
Key takeaways:
Outline with budgets. Section-level word targets are easier for a model to hit than one big target.
One section per call, with a summary of what's already covered, to prevent repetition.
Assign each point to one section only in the outline. Repetition starts in the plan.
Style rules must be checkable: "no sentences over 30 words", not "concise".
Check in code what code can check. Use a model or a person for the rest.
[02]
Why long outputs drift
Models are trained mostly on outputs much shorter than a long article. LongWriter (Bai et al., 2024) found that long-context models "struggle to generate outputs exceeding even a modest length of 2,000 words" and traced the limit to how few long outputs appear in fine-tuning data. Their AgentWrite pipeline broke long writing into planned subtasks and got off-the-shelf models past 20,000 words.
Planning also helps below that limit. Skeleton-of-Thought (Ning et al., ICLR 2024) had models write an outline first and expand each point, mainly to cut latency through parallel calls, and reported that it could also improve answer quality on some question types. The Skeleton-of-Thought guide covers the speed side. This guide covers control.
[03]
Worked example: one prompt vs an outline with budgets
The brief:
Topic: How a small SaaS team should run its first on-call rotation.
Audience: engineering managers at 5-15 person startups.
Facts to use: rotations of one week are common; page only for customer-facing impact; every page gets
a short written review within 2 business days.
Style: American English, short sentences, second person. No marketing words (seamless, robust,
game-changer, leverage). No rhetorical questions. Use concrete examples.
One prompt
Write a 1,200-word article.
<brief>
The result was 1,328 words, about 11% over, with no headings at all: 19 paragraphs and a few bullets in one unbroken block. The content was solid. The opening shows the style rules being followed a little too literally:
You are starting your first on-call rotation. Your team has 5–15 engineers. You run a small SaaS product. You need coverage without burning people out. You need to protect customers. You need clear, simple rules that everyone can follow.Ask for an outline with budgets
Plan a 1,200-word article as 5 sections. For each: heading, 2-4 points it must make, and a word budget.
Budgets must sum to 1,200. Each point appears in one section only.
<brief>
Request the outline as structured output (a JSON schema with heading, points and words per section), so your code can loop over it. Part of what came back:
{
  "heading": "Designing the initial rotation",
  "points": [
    "Choose a cadence that balances coverage and burnout; rotations of one week are common and fit small teams …",
    "Define who participates and when: include engineering generalists, product-aware engineers, and a clear escalation path …",
    "Determine shift boundaries and time off rules, including how to handle vacations, partial-week onboarding, and swapping weeks …"
  ],
  "words": 240
}
Review the outline before generating anything. It's the cheapest place to fix structure, scope and order.
Write one section per call
<brief>
You are writing one section of a longer article. Earlier sections covered: <headings so far>.
Don't repeat them and don't write an introduction or conclusion for the whole article.
Section heading: <heading>
Make these points: <points>
Length: about <words> words (stay within 10%). Return only the section body, no heading.
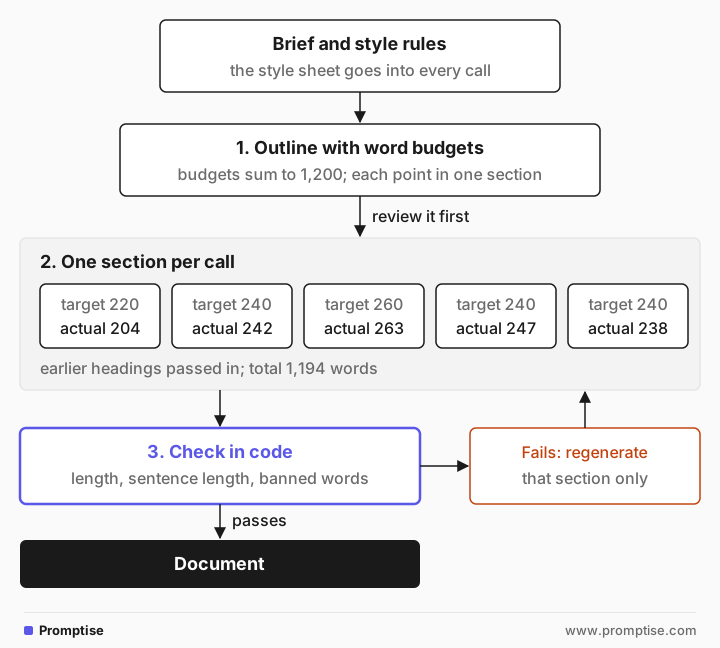
The result per section:
 220 target   204 actual  Why an on-call rotation matters for a small SaaS team
 240 target   242 actual  Designing the initial rotation
 260 target   263 actual  Alerting and paging policy for customer impact
 240 target   247 actual  Handoff, documentation, and immediate post-incident work
 240 target   238 actual  Improving the rotation and keeping it sustainable
TOTAL: 1194
Every section landed within 10% of its budget, and the total was within 1% of 1,200. The structure is the one you approved, and "Don't repeat them" plus one-point-one-section in the outline keeps sections from re-explaining the same facts. Results vary by model.
The cost is more calls: one outline plus one per section, each repeating the brief. For a 1,200-word piece that's small. For a 20,000-word report it's the only approach that works.
[04]
Write the style sheet as rules
"Professional and concise" gives the model nothing to act on. Rules it can follow and you can check work better:
Style rules:
- American English. Second person ("you").
- Sentences under 25 words on average; none over 35.
- One idea per paragraph; paragraphs of 2-5 sentences.
- Every section has at least one concrete example (a number, a name, a command).
- Never use: seamless, robust, game-changer, leverage, delve, crucial.
- No rhetorical questions. No sentences that only announce what comes next.
Put the style sheet in every section call. Without it, later sections drift back to the model's default voice.
[05]
Check what code can check
import re
import statistics

BANNED = ["seamless", "robust", "game-changer", "leverage", "crucial", "delve"]

def style_report(text: str) -> dict:
    sentences = [s for s in re.split(r"(?<=[.!?])\s+", text) if s.strip()]
    lengths = [len(s.split()) for s in sentences]
    return {
        "words": sum(lengths),
        "avg_sentence_words": round(statistics.mean(lengths), 1),
        "sentences_over_30_words": sum(n > 30 for n in lengths),
        "questions": text.count("?"),
        "banned": [w for w in BANNED if w in text.lower()],
    }
On the two versions:
oneshot {'words': 1329, 'avg_sentence_words': 10.7, 'sentences_over_30_words': 1, 'questions': 0, 'banned': []}
outline {'words': 1189, 'avg_sentence_words': 13.2, 'sentences_over_30_words': 2, 'questions': 0, 'banned': []}
Both followed the style rules. The one-shot version's 10.7-word average reflects the choppy "You need… You need…" opening. A report like this catches regressions when you change the model or the prompt. If a section fails a check, regenerate only that section with the failure in the prompt ("Sentence 4 has 41 words; split it").
What code can't check (accuracy against the brief, whether examples are sensible, whether the argument flows) needs a model pass with a narrow question, or a human editor. Ask for one thing per pass: "List any claim not supported by the brief" works better than "review this article".
[06]
When to use outline-first generation (and when not to)
Use it for:
Anything over about 800 words, or with a required structure (reports, docs, proposals).
Documents generated repeatedly from a template, where predictable length and headings matter.
Long documents that must stay consistent with source material, one section at a time.
Skip it for:
Short answers, emails and summaries. One call is fine.
Pieces where the flow between paragraphs matters more than structure, like a narrative essay. Generate in one call and edit.
For summaries that must keep names, numbers and dates, see chain of density summarization.
[07]
Make the sections read as one document
Section-by-section writing can feel stitched together. Three fixes:
Pass the outline and the headings already written, so each section knows its place.
Pass the last two sentences of the previous section when transitions matter.
Generate the introduction and conclusion last, from the finished sections, so they describe what's actually there.
[08]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
One prompt with a word count for a long piece | Length drifts; structure is the model's choice | Outline with section budgets, then write per section |
The same point allowed in several sections | Sections repeat each other | Assign each point to one section in the outline |
Style as adjectives ("crisp, engaging") | Nothing to follow or check | Concrete rules: sentence length, banned words, examples |
Style sheet only in the first call | Later sections drift to the default voice | Include it in every section call |
Intro written first | It promises things the sections don't deliver | Write intro and conclusion last |
One "review this article" pass | Vague feedback, random edits | Narrow checks: unsupported claims, missing points, length |
[09]
Frequently asked questions
Why can't LLMs hit an exact word count?
Models generate tokens, not words, and don't count as they write. They're also trained on few very long outputs, which LongWriter (Bai et al., 2024) identified as a cause of length limits. Section-level budgets break a large target into smaller ones the model can approximate, and you can verify each in code.
How long can an LLM write in one call?
It depends on the model and its output token limit, and quality often drops well before the limit. For anything over a few thousand words, plan and generate in sections.
How do I keep the style consistent across sections?
Use the same style sheet in every call, write it as concrete rules, and run a style check on each section. Regenerate sections that fail, with the specific failure in the prompt.
How do I stop sections from repeating each other?
Give each point to exactly one section in the outline, tell each section call which sections came before, and say "don't repeat them". Repetition that slips through is easy to spot when you read the outline and sections side by side.
Should sections be generated in parallel?
You can, as in Skeleton-of-Thought, which saves time. Sequential generation lets each section see what came before, which helps transitions and avoids overlap. Use parallel calls for reference-style documents and sequential for arguments.
[10]
Next steps
Outline first, then expand in parallel: Skeleton-of-Thought and section budgets.
Dense summaries: chain of density summarization.
Tone and polish: polish and style controls.
Revise against checks: LLM self-correction.
Structured outlines: structured outputs.