Contents · 7 sections↓
Structured outputs make a language model return data in a fixed shape, usually JSON that matches a schema you define, so your code can use it without guessing. This guide is for developers who extract fields from emails, tickets or documents and are tired of parsing whatever the model felt like returning. It shows a real support-email extraction three ways: a plain prompt, a schema-enforced call in Python, and the one problem a schema can't catch.
How do you get reliable JSON from an LLM?
Define a schema for the fields you need, with types and fixed value lists (enums) where possible. Then use your provider's structured-output feature, which constrains the model to that schema, and parse the result into a typed object such as a Pydantic model. Finally, check the values, not just the shape: a schema guarantees valid JSON with the right keys, not correct answers.
Key takeaways:
"Return JSON" in a prompt is not enough. Key names and value formats change from input to input.
Use enums for anything your code branches on (issue type, requested action).
Use null for "not stated" and say so, or the model invents a value.
Describe each field's meaning. Most wrong values come from ambiguous field names.
[02]
How structured outputs work
There are three levels of reliability:
Approach | What you get | Use when |
|---|---|---|
Prompt only ("return JSON with these keys") | Usually valid JSON; keys and values may drift | Prototypes, providers without schema support |
JSON mode | Always parseable JSON; keys still up to the model | Rarely the best choice now |
Structured outputs (schema-enforced) | JSON that matches your schema | Anything your code depends on |
With schema-enforced output, the provider constrains generation so the model can only produce tokens that fit your JSON Schema. OpenAI calls this Structured Outputs; other providers offer similar features or tool-call schemas that work the same way. Support for schema features (nested objects, enums, optional fields) varies, so check your provider's docs.
[03]
Worked example: extracting fields from a support email
The email:
Subject: Wrong size delivered - order 48213

Hi,

I ordered the Alder rain jacket in M (order #48213, placed Oct 2) and received an L instead.
I'd like to swap it for the M, not a refund. I'm traveling on the 25th so if the replacement
can't arrive by then, please just refund me instead.

You can reach me at this email or 415-555-0142.

Thanks,
Dana Whitfield
The plain prompt
Extract the order details from this email as JSON.The output (trimmed):
{
  "order_number": "48213",
  "customer_name": "Dana Whitfield",
  "product": "Alder rain jacket",
  …
  "requested_action": "exchange_for_size",
  "fallback_action_if_replacement_unavailable_by_deadline": "refund",
  "deadline_for_replacement": "Oct 25",
  …
}
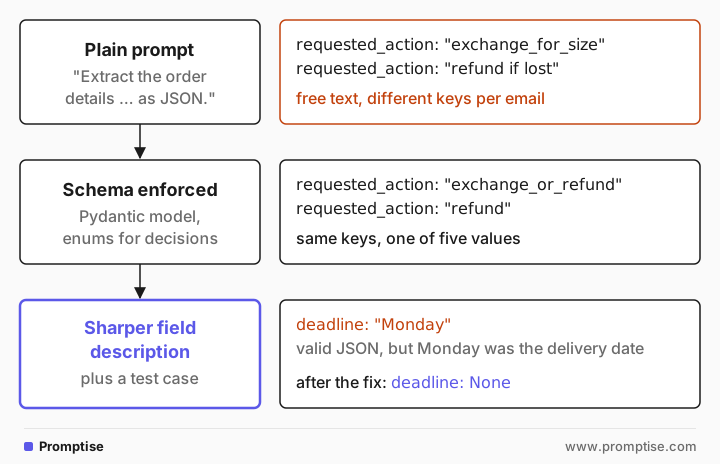
Reasonable. Now a second email, "Order 48377 was supposed to arrive Monday. Tracking hasn't updated in 5 days. Please refund if it's lost.", with the same prompt:
{
  "order_number": "48377",
  "customer_name": "Sam",
  "subject": "where is my package??",
  "message": "Order 48377 was supposed to arrive Monday. …",
  "expected_delivery": "Monday",
  "tracking_last_updated": "5 days ago",
  "requested_action": "refund if lost"
}
Different keys, and requested_action is free text ("exchange_for_size", "refund if lost"). Code that routes tickets on requested_action == "refund" breaks on both.
The schema-enforced version
Define the fields once, as a Pydantic model, and let the SDK enforce it:
from typing import Literal, Optional

from openai import OpenAI
from pydantic import BaseModel, Field


class SupportEmail(BaseModel):
    order_id: Optional[str] = Field(description="Order number without #")
    customer_name: Optional[str]
    issue: Literal["wrong_item", "damaged", "late", "missing", "other"]
    requested_action: Literal["exchange", "refund", "exchange_or_refund", "info", "other"]
    deadline: Optional[str] = Field(description="Date the customer needs it by, as written, or null")
    summary: str = Field(description="One sentence for the support agent")


client = OpenAI()


def extract(email: str) -> SupportEmail:
    response = client.chat.completions.parse(
        model="gpt-5-mini",
        messages=[
            {"role": "system", "content": "Extract fields from customer support emails. Use null when the email doesn't say."},
            {"role": "user", "content": email},
        ],
        response_format=SupportEmail,
    )
    message = response.choices[0].message
    if message.refusal:
        raise ValueError(f"model refused: {message.refusal}")
    return message.parsed  # already validated against SupportEmail
The first email now returns:
{"order_id":"48213","customer_name":"Dana Whitfield","issue":"wrong_item","requested_action":"exchange_or_refund","deadline":"25th","summary":"Customer received the jacket in size L instead of M and wants an exchange for M but requests a refund if the replacement cannot arrive by the 25th."}Same keys every time, and requested_action is one of five values your code can switch on. The "exchange, or refund if too late" case maps to exchange_or_refund because the enum offers it. Designing the enum is designing your workflow.
What the schema can't catch
The second email:
{
  "order_id": "48377",
  "customer_name": "Sam",
  "issue": "late",
  "requested_action": "refund",
  "deadline": "Monday",
  "summary": "Customer Sam (Order 48377) reports tracking hasn't updated in 5 days; package was due Monday and they request a refund if the package is lost."
}
Valid against the schema, and two values are wrong for the workflow. "Monday" was the expected delivery date, not a deadline the customer set. And "refund" drops the condition "if it's lost". The schema guarantees shape; correctness comes from clear field definitions and checks.
Two fixes: sharpen the field description ("deadline: a date the customer says they need it by; not the expected delivery date") and add the case to your test set. With that rule added, the same email returned deadline=None. For the conditional request, add an enum value like refund_if_lost or a conditions field, if your team handles those differently.
[04]
When to use structured outputs (and when not to)
Use them whenever code reads the output: extraction, classification, routing, filling a database, calling another API.
Don't use them for text a person reads, such as an email draft or a summary. Forcing prose into JSON fields tends to make it stiffer, and you gain nothing. If you need both, put the prose in one string field, like summary above.
If your provider has no schema enforcement, put the schema in the prompt, parse with Pydantic, and on a validation error send the error back to the model once and ask it to fix the output.
If you keep prompts in code, Promptise Foundry can attach the schema to a prompt function and return the typed object:
@prompt(model="openai:gpt-5-mini")
@blocks(
    Rules(["Use null when the email doesn't say", "deadline is the date the customer needs it by, not a delivery date"]),
    OutputFormat(format="json", schema=SupportEmail),
)
async def extract(email: str) -> SupportEmail:
    """Extract the fields from this customer email:
{email}"""SupportEmail order_id='48377' customer_name='Sam' issue='late' requested_action='refund' deadline=None summary="Customer Sam reports order 48377 was supposed to arrive Monday; tracking hasn't updated in 5 days and they request a refund if the package is lost."[05]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
"Return JSON" with no schema | Keys and formats drift between inputs | Use a schema and structured outputs |
Free-text fields your code branches on | "refund if lost" never equals "refund" | Enums for every decision field |
No way to say "not stated" | The model fills the field with a guess | Make it nullable and say "null when not stated" |
Vague field names (date, deadline) | The model picks whichever date it sees | A one-line description per field |
Trusting valid JSON as correct | Schema checks shape, not meaning | Spot-check values; keep a test set of real emails |
Huge nested schemas for simple tasks | More fields, more mistakes | Extract only what you'll use |
[06]
Frequently asked questions
What is the difference between JSON mode and structured outputs?
JSON mode guarantees the output parses as JSON but lets the model choose keys and types. Structured outputs constrain the output to your schema: required keys, types and enum values. Prefer structured outputs when your provider supports them.
Do I still need validation if I use structured outputs?
Yes, but a different kind. Parsing into Pydantic catches any shape problems for free. What you still need is value checks: is the order ID in your system, is the date real, does the summary match the email?
Should I ask the model to explain its reasoning in the JSON?
Only if you'll use it. A short reason field can help when you review wrong outputs. It adds tokens and does not make the other fields more accurate by itself.
How do I handle emails with several orders?
Make the top level a list (orders: list[Order]) and say "one entry per order mentioned". Test it with an email that mentions none, one and two orders.
Why did the model refuse?
Structured-output APIs can return a refusal instead of data, for example on unsafe content. Check for it, as the code above does, rather than assuming parsed is set.
[07]
Next steps
Previous in the path: grounding.
Next: add a confidence field with self-check prompts.
Check values, not just shape: output verification.
Test extraction prompts in CI: test LLM prompts in Python.
Back to the pillar: what is prompt engineering?