Contents · 8 sections↓
Directional Stimulus Prompting (DSP) steers a large model with a short hint written for each input, such as the keywords a summary must contain. In the original research a small model learns to write those hints, so the large model never needs fine-tuning. This guide is for developers who summarize, reply to or rewrite many similar inputs and need control over what the output includes. It explains the paper's method, a prompt-only version you can build today, a real before-and-after example, and where plain instructions already do the job.
What is directional stimulus prompting?
Directional stimulus prompting (DSP) is a prompting technique that adds a short hint, written for each input, to steer a large language model toward the output you want. It improves the AI's response by telling the model what matters for this particular input, so it doesn't have to guess which facts to keep, which tone to take or which step to reason through.
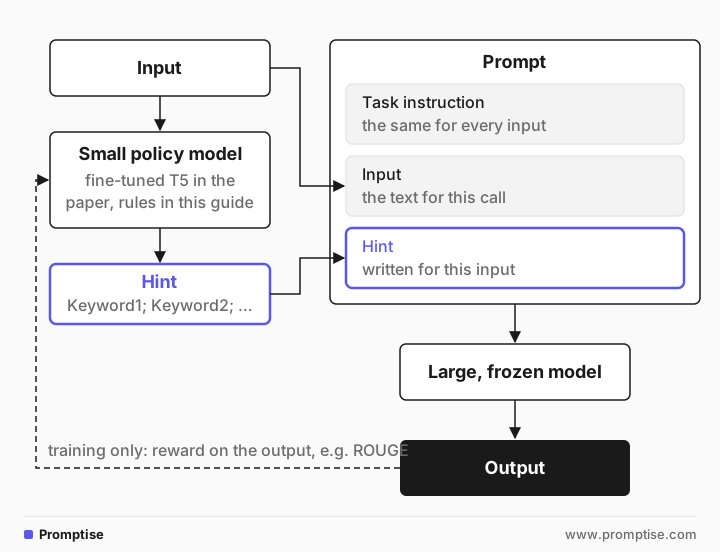
In practice, DSP adds an instance-specific hint, the "directional stimulus", to the prompt next to the task instruction. The hint tells the model which direction to take for this input: keywords to include, a dialogue act to perform, a reasoning cue. In the paper, a small policy model (a fine-tuned T5) generates the hint for each input, and it is trained so the hints lead the large, frozen model to better outputs.
Key takeaways:
The hint changes per input; the instruction does not. That is what separates DSP from a better system prompt.
The hint comes from a cheaper component: a small model, rules, retrieval or your own data.
It matters most under tight constraints. In the example, the hint decided which facts survived a 30-word limit.
Without training, DSP is "generate a hint, then prompt". Useful, but the paper's gains came from a trained hint writer.
[02]
How Directional Stimulus Prompting works
Guiding Large Language Models via Directional Stimulus Prompting (Li, Peng, He, Galley, Gao and Yan, 2023, NeurIPS) treats the large model as a black box and trains a small policy model to write hints:
Supervised start. For summarization, the authors extracted keywords from each article with TextRank and kept those that also appear in the reference summary. The policy model (Flan-T5-Large in the main experiments) learned to produce them from the article, formatted as "Keyword1; Keyword2; …".
Reinforcement learning. The policy model was then tuned with rewards measured on the large model's output, such as the ROUGE score of the summary it produced with that hint.
Inference. For each new input, the small model writes the hint, the hint is added to the prompt, and the large model generates as usual.
The paper tested summarization, dialogue response generation and chain-of-thought reasoning with ChatGPT, Codex and InstructGPT. With 80 dialogues from MultiWOZ for training, DSP improved ChatGPT's performance by 41.4%. For reasoning, the policy model wrote instance-specific chain-of-thought trigger prompts, which beat hand-written and automatically found ones for InstructGPT.
[03]
Worked example: a 30-word incident summary
The input is a 150-word incident report (abridged here):
At 14:05 UTC on Tuesday, checkout started failing for about a third of customers. The on-call engineer first
suspected the CDN … The real cause was the payment-gateway client in release v2.31, deployed at 13:58, which
lowered the request timeout from 10 seconds to 1 second by mistake. … The team rolled back to v2.30 at 14:43,
and checkout recovered by 14:47. In total 1,240 orders failed during the 42 minutes; 310 of those customers
completed their purchase later the same day. Support received 96 tickets. The fix, a config test that rejects
timeouts under 5 seconds, ships in v2.32. The CDN incident was unrelated.
The status page needs one sentence of at most 30 words, and your team has a rule: always include the start time, the versions, failed orders, duration, tickets and where the fix ships. The hint generator here is a few lines of rules, standing in for the paper's trained policy model:
import re


def stimulus(text: str) -> str:
    """Pull out the facts a status summary must keep: times, versions, counts.
    In the paper this is a small fine-tuned model that writes the hint for each input."""
    keep = re.findall(r"\d{1,2}:\d{2} UTC|v\d+\.\d+|\d[\d,]* (?:orders|minutes|tickets)", text)
    return "; ".join(dict.fromkeys(keep))


base = f"Summarize this incident report in one sentence of at most 30 words for a status update.\n\n{report}"
plain = ask(base)
hinted = ask(f"{base}\n\nHint (keywords the summary should include): {stimulus(report)}")
Output, same model and setting for both calls:
WITHOUT HINT:
At 13:58 a deploy (v2.31) accidentally set payment timeouts to 1s, causing ~1,240 failed checkouts (42 minutes); rollback to v2.30 at 14:43 restored service by 14:47.

HINT: 14:05 UTC; v2.31; v2.30; 1,240 orders; 42 minutes; 96 tickets; v2.32

WITH HINT:
At 14:05 UTC checkout failures began after v2.31 (deployed 13:58) cut timeouts, causing 1,240 failed orders over 42 minutes; rolled back to v2.30, 96 tickets, fix in v2.32.
Both summaries are accurate. They differ in what they kept. Without the hint, the model chose the deploy time and recovery time and dropped the ticket count and the fix version. With the hint, it kept every fact your team's rule asks for. The hint did not make the model better at summarizing; it told it which facts matter for this input.
The same test with a looser limit, two sentences, gave summaries that already included nearly every fact with or without the hint. With room to spare, current models keep the important details on their own. Hints pay off when space is tight or when "important" depends on something the model can't know.
[04]
Where the hint can come from
The value of DSP is a second component that knows something the large model doesn't. Options, from cheapest to most work:
Hint source | Example | Good for |
|---|---|---|
Rules or regex | Times, IDs, amounts, version numbers | Facts that must survive compression |
Your data | The customer's plan, open tickets, account owner | Replies that must reference account context |
Retrieval | Top three terms or passages from your docs | Answers that should use your terminology |
A small model | A cheap model writes keywords or a reply intent | Steering at scale, cheaper than a long prompt |
A trained policy model | The paper's T5, tuned on your metric | High-volume tasks with a clear score, such as ROUGE or a click rate |
Keep the hint short, labeled and separate from the instruction, so you can log it, test it and change the generator without touching the main prompt. If you keep prompts in a registry or as code, treat the hint as a template variable with its own tests.
[05]
When to use it (and when not to)
Use it when:
The same instruction runs on many inputs, and what "good" means depends on each input.
Output length is tight and the model drops facts you need.
You can compute the hint cheaply and reliably (rules, data, a small model).
Skip it when:
A fixed rule covers it. "Always include the ticket count" belongs in the instruction, not in a per-input hint.
The hint generator would need the same skill as the large model. Then you are running two models for one job.
You want to control tone or format. Write that in the instruction or use style controls and structured outputs.
What changes with reasoning models
Reasoning models follow detailed instructions well, so much of what DSP did in 2023 (getting the model to include specific content) now works with a clear instruction alone, as the two-sentence test showed. The paper's reasoning use, a per-question chain-of-thought trigger, matters little for models that reason internally. What stays useful is the architecture: a cheap, testable component that injects per-input facts or priorities into a fixed prompt. That is also how retrieval-augmented prompts work; see grounding with context.
[06]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
A hint that is a second instruction set | Conflicts with the main prompt; the model picks one | Keywords or one short cue, clearly labeled |
The same hint for every input | That is a rule, not a stimulus | Put fixed rules in the instruction |
Too many keywords for the length limit | The model crams or ignores some | Rank hints; fit the count to the budget |
No check that the hint was used | Silent misses go unnoticed | Check in code that required keywords appear |
Claiming the paper's gains without training | The 41.4% came from a trained policy model | Measure your prompt-only version on your own data |
[07]
Frequently asked questions
How does directional stimulus prompting improve the AI's response?
It gives the model information it would otherwise have to guess: which keywords, facts or actions matter for this input. A general instruction such as "summarize in 30 words" leaves the model to decide what to keep, and it often keeps the wrong things. A hint such as "14:05 UTC; v2.31; v2.30; 1,240 orders; 42 minutes; 96 tickets; v2.32" from the worked example points it at the parts you care about, so the output is more complete and more consistent. In the paper, a trained hint writer improved ChatGPT's dialogue performance by 41.4% using only 80 training dialogues from MultiWOZ.
Is Directional Stimulus Prompting the same as adding keywords to a prompt?
The prompt-only version is close to that, with one difference: the keywords are chosen per input by a separate component. In the paper, that component is a small model trained so its keywords lead to better outputs, which is where most of the reported improvement came from.
Do I need to train a model to use DSP?
No. Rules, retrieval or a cheap model can write the hint. Training a policy model, as in the paper, makes sense when you have a measurable target (a ROUGE score, a resolution rate) and enough volume to justify it.
How is DSP different from few-shot prompting?
Few-shot examples show the pattern of good outputs. A directional stimulus tells the model what to do for this specific input. They combine well: examples for format, a hint for content. See few-shot examples the right way.
Where do I put the hint in the prompt?
After the task and the input, in a labeled line such as "Hint (keywords the summary should include): …". Keeping it last and labeled makes it easy to log and to remove when testing whether it helps.
Can the hint be a reasoning cue?
The paper did that: the policy model wrote a chain-of-thought trigger for each question. With reasoning models this adds little, because they reason without a trigger. For the basics of step prompts, see chain-of-thought for beginners.
[08]
Next steps
Keep summaries dense and complete: summarization with chain of density.
Control tone and form: polish and style controls.
Hints from your own documents: grounding with context.
Examples for format: few-shot examples the right way.
Let a program find the prompt: auto-prompting with APE and ProTeGi.