An AI agent project needs more than agent code: the right environment variables, a way to see each step when an answer is wrong, production logs, and often an HTTP API. This guide shows how to do all of that for a Python agent with one command, promptise run, by building a small customer support agent and taking it from your laptop to a Docker container.
How do you run, debug and deploy a Python AI agent project?
Describe the project in a promptise.toml file (the main file, scripts and required environment), then run it with promptise run. Add --devtools to trace every LLM call and tool call, --tui for a terminal UI, --prod for JSON logs and a clean shutdown, and --serve for an authenticated HTTP API.
One manifest: promptise.toml works like package.json: main, [scripts], [env].
No code changes: your main file stays a normal Python script; every agent it builds is traced automatically.
Debugging: --devtools shows tools, arguments, results, tokens, latency and cost for each step.
Production: --prod adds JSON logs, checks before start and graceful shutdown; --serve adds health checks, invoke and streaming endpoints.
Version: everything here needs Promptise Foundry 1.4.1 or later.
[02]
What is promptise run?
promptise run is the project runner of Promptise Foundry, an open-source Python framework for AI agents. It reads a manifest, promptise.toml, that plays the role of package.json in a Node project:
npm | Promptise |
|---|---|
---|--- | |
package.json | promptise.toml (or [tool.promptise] in pyproject.toml) |
"main": "index.js" | main = "main.py" |
"scripts" | |
npm start | promptise run |
npm run dev | promptise run dev |
npm init | promptise init --project |
Your main file stays a normal Python program. promptise run runs it the way python main.py does, and adds the parts every agent project needs around it:
Environment: loads the .env files you list and checks required variables before anything starts.
Dev tools: --devtools prints every LLM call and tool call with tokens, latency and cost.
Terminal UI: --tui opens a full-screen view of the agent's chat, trace, tools, metrics, logs and approvals.
Production: --prod switches to JSON logs, checks the project before start and shuts down cleanly.
HTTP API: --serve puts your agent behind authenticated endpoints.
None of this needs changes to your agent code.
How it works
promptise run [flags] [file | script]
  ├─ find promptise.toml (current directory and up)  → project root
  ├─ load [env] and check required variables         → stop with exit code 2 if anything is missing
  ├─ install the run's hook in build_agent()          → every agent the program builds is traced
  └─ run main.py as __main__
        ├─ --devtools  trace on stderr, summary at the end
        ├─ --tui       program in a child process, events streamed to the terminal UI
        ├─ --prod      JSON logs, SIGTERM → clean shutdown
        └─ --serve     agent factory behind /healthz, /readyz, /v1/invoke, /v1/stream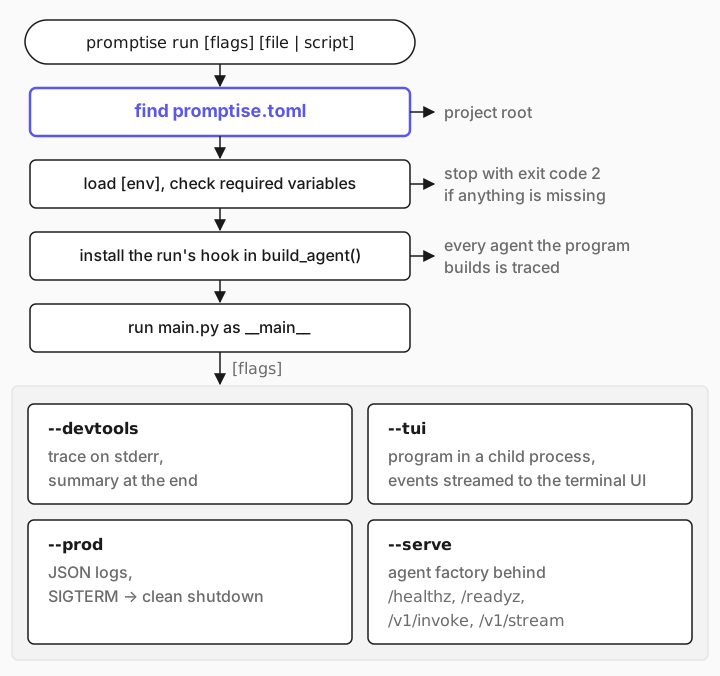
[03]
When to use promptise run (and when not to)
Use it when your agent is a project you run, debug and deploy: a script that builds an agent with build_agent(), a support bot, a background worker, an internal API. It gives every project the same commands, so a teammate can run yours with promptise run without reading a README.
You don't need it for a notebook experiment, or when the agent lives inside an existing web app that already has its own server, logging and deployment. In that case, call build_agent() from your app and use observability in code instead.
[04]
What you need
Python 3.10 or later
Promptise Foundry 1.4.1 or later (
pip install -U "promptise>=1.4.1")An API key for your model provider (this guide uses OPENAI_API_KEY with gpt-5-mini)
Docker, only for the last step
[05]
Step 1: Create a project
promptise init --project support-bot
cd support-bot
cp .env.example .env    # then put your OPENAI_API_KEY in .env
promptise init --project creates a working project: promptise.toml, agent.py with the agent, main.py with the program, .env.example, a README.md and .gitignore entries for .env and the run reports. The rest of this guide uses a slightly larger version of that project: a support agent for an outdoor shop that looks up orders, searches help center articles and opens tickets for a person.
[06]
Step 2: Describe the project in promptise.toml
# The support bot's manifest: how `promptise run` runs this project.
# Reference: https://docs.promptise.com/core/projects/

name = "support-bot"
version = "0.1.0"
description = "Answers customer support tickets for a small online shop"
main = "main.py"                    # the program `promptise run` runs
agent = "agent.py:create_agent"     # the agent factory for --serve, -i and chat mode

[scripts]                           # `promptise run <name> [args]`, like `npm run`
dev = "promptise run --devtools --watch"
ui = "promptise run --tui"
chat = "promptise run --tui --mode chat"
start = "promptise run --prod"
serve = "promptise run --serve"
check = "promptise run --prod --check"

[env]
files = [".env"]                    # loaded in order; never overrides a variable already set
required = ["OPENAI_API_KEY"]
vars = { SUPPORT_BOT_MODEL = "openai:gpt-5-mini" }   # a default; set the variable to change it

[dev]                               # with --devtools, --tui and --watch
observe = "full"
watch = ["."]
report = ".promptise/last-run.json" # a JSON run report, written on exit

[prod]                              # with --prod
log_format = "json"
log_level = "INFO"
shutdown_timeout = 20

[serve]                             # with --serve
host = "127.0.0.1"
port = 8080
max_concurrency = 4

# USD per 1M tokens, for the cost estimates in --devtools and --tui.
# Check your provider's current prices before you rely on these numbers.
[pricing]
"gpt-5-mini*" = { input = 0.25, output = 2.0 }
What each part does:
`main` is the program promptise run runs. If you leave it out, main.py, agent.py or app.py is used, whichever exists.
`agent` points at a function that builds and returns the agent (an agent factory). You need it to chat with the agent, ask it one question from the command line, or serve it over HTTP.
`[scripts]` holds named commands, run with promptise run <name>.
`[env]` lists the .env files to load and the variables that must be set. A variable that is already set in your shell is never overwritten.
`[dev]` controls the dev tools: how much to record, what to watch, and where to write a run report.
`[prod]` and `[serve]` configure production logs, shutdown and the HTTP API.
`[pricing]` holds your model prices in USD per million tokens, for cost estimates. Promptise ships no price list, because prices change.
Unknown keys are errors, so a typo like mian = "main.py" stops the run with mian: unknown key instead of being ignored. The manifest holds no secrets: API keys and tokens come from the environment.
[07]
Step 3: Write the agent and the program
Put the agent in a factory function. promptise run calls it with a RunContext (project, mode, flags, the --model override), and your own code can call it without one:
"""The support bot's agent: the factory and three local tools.

The tools read and write an in-memory shop, so the example needs no network
apart from the model itself.  ``main.py`` calls ``create_agent()``;
``promptise run`` calls ``create_agent(ctx)`` for ``--serve``, ``-i`` and chat
mode.
"""

from __future__ import annotations

import json
import os

from langchain_core.tools import tool
from promptise import PromptiseAgent, build_agent
from promptise.run import RunContext

DEFAULT_MODEL = "openai:gpt-5-mini"

INSTRUCTIONS = """\
You are the support agent of Trailhead, a small online outdoor shop.

- Before you say anything about an order, look it up with lookup_order.
- Answer policy questions (returns, refunds, shipping) from search_help_center,
  never from memory.
- Refunds and damaged items need a person: open a ticket with open_ticket and
  give the customer the ticket ID.
- Never invent order details. If an order ID is missing, ask for it.
- Be brief and friendly. Sign off as "Trailhead Support".
"""

ORDERS: dict[str, dict[str, str]] = {
    "A1001": {"item": "Rain jacket", "status": "delivered", "delivered_on": "2026-10-12"},
    "A1002": {
        "item": "Hiking boots",
        "status": "in transit",
        "carrier": "DHL",
        "expected_on": "2026-10-19",
    },
    "A1003": {"item": "Steel water bottle", "status": "delivered", "delivered_on": "2026-10-15"},
}

ARTICLES: dict[str, str] = {
    "Returns": (
        "Unworn items can be returned within 30 days of delivery. Start a return at "
        "trailhead.example.com/returns; the return label is free."
    ),
    "Refunds": (
        "Refunds go to the original payment method 3 to 5 business days after the "
        "returned item arrives. Damaged items are refunded without a return."
    ),
    "Shipping": (
        "Standard shipping takes 3 to 5 business days. The tracking link is in the "
        "shipping confirmation email."
    ),
}

TICKETS: list[dict[str, str]] = []
"""Tickets opened for a person (in memory; a real bot would call a help desk API)."""


@tool
def lookup_order(order_id: str) -> str:
    """Look up an order by its ID, for example A1002. Returns the item, status and dates."""
    key = order_id.strip().upper()
    order = ORDERS.get(key)
    if order is None:
        return f"No order {order_id!r}. Order IDs look like A1002."
    return json.dumps({"order_id": key, **order})


@tool
def search_help_center(query: str) -> str:
    """Search the help center articles (returns, refunds, shipping). Returns the best matches."""
    words = [w.strip(".,?!").lower() for w in query.split() if len(w) > 3]
    scored = []
    for title, text in ARTICLES.items():
        haystack = f"{title} {text}".lower()
        score = sum(word in haystack for word in words)
        if score:
            scored.append((score, title, text))
    if not scored:
        return "No article matches. Try other words, or open a ticket for a person."
    scored.sort(reverse=True)
    return "\n".join(f"{title}: {text}" for _, title, text in scored[:2])


@tool
def open_ticket(customer_email: str, summary: str, priority: str = "normal") -> str:
    """Hand a case to a person on the support team. Use it for refunds, damaged items and
    anything you cannot solve. priority is low, normal or high."""
    ticket_id = f"T-{len(TICKETS) + 1:04d}"
    TICKETS.append(
        {"id": ticket_id, "email": customer_email, "summary": summary, "priority": priority}
    )
    return (
        f"Opened {ticket_id} ({priority}) for {customer_email}. "
        "A person replies within one business day."
    )


async def create_agent(ctx: RunContext | None = None) -> PromptiseAgent:
    """Build the support agent.

    The model is the ``--model`` override when ``promptise run`` passes one,
    else ``SUPPORT_BOT_MODEL`` (a default in ``promptise.toml``), else
    ``openai:gpt-5-mini``.
    """
    model = (
        (ctx.model if ctx is not None else None)
        or os.environ.get("SUPPORT_BOT_MODEL")
        or DEFAULT_MODEL
    )
    return await build_agent(
        model=model,
        instructions=INSTRUCTIONS,
        extra_tools=[lookup_order, search_help_center, open_ticket],
    )
The program is an ordinary script. It builds the agent, answers the tickets in its inbox (or the one you pass), and shuts the agent down:
"""The support bot's program: answer the tickets in the inbox, or the one you pass.

A normal Python script::

    python main.py                                  # the three sample tickets
    python main.py "Where is my order A1002?"       # one ticket

``promptise run`` runs it the same way and adds the project's environment,
dev tools, the terminal UI or production behavior, with no changes here::

    promptise run --devtools
    promptise run main.py "Where is my order A1002?"
"""

from __future__ import annotations

import asyncio
import sys

from agent import TICKETS, create_agent

INBOX = [
    "Hi, where is my order A1002? It was supposed to arrive by now.",
    "How do I return a jacket that doesn't fit?",
    "My order A1003 arrived dented. I'd like a refund please. I'm lee@example.com.",
]


async def main() -> None:
    tickets = [" ".join(sys.argv[1:])] if len(sys.argv) > 1 else INBOX
    agent = await create_agent()
    try:
        for number, ticket in enumerate(tickets, 1):
            print(f"--- Ticket {number}: {ticket}")
            result = await agent.ainvoke({"messages": [{"role": "user", "content": ticket}]})
            print(result["messages"][-1].content)
            print()
    finally:
        await agent.shutdown()
    if TICKETS:
        print(f"Handed to a person: {', '.join(t['id'] for t in TICKETS)}")


if __name__ == "__main__":
    asyncio.run(main())
python main.py works on its own. Nothing in either file depends on promptise run.
[08]
Step 4: Run the project
promptise run main.py "Hi, where is my order A1002? It was supposed to arrive by now."--- Ticket 1: Hi, where is my order A1002? It was supposed to arrive by now.
Thanks — I looked up order A1002. It's for "Hiking boots" and is currently in transit with DHL. The expected delivery date is 2026-10-19 (today is 2026-10-17), so it should arrive by the 19th.
If you want me to open a ticket to investigate or follow up with DHL after the 19th, I can do that — would you like me to open one?
Trailhead SupportHow it works:
1. promptise run looks for promptise.toml in the current directory and its parents, the way npm finds package.json, and treats that directory as the project root. 2. It loads [env]: your .env files, then the defaults in vars. 3. It checks the project: the manifest is valid, the main file exists, and every required variable is set. If something is wrong, it lists every problem at once and exits with code 2. 4. It runs main.py from the project root with your arguments in sys.argv, and exits with your program's exit code.
Two more commands help here. promptise run --check runs the checks without starting anything, which is useful in CI. promptise run --list prints the scripts:
script  command
dev     promptise run --devtools --watch
ui      promptise run --tui
chat    promptise run --tui --mode chat
start   promptise run --prod
serve   promptise run --serve
check   promptise run --prod --check
To pass arguments to the main file, name the file first (promptise run main.py ARGS). A bare word after promptise run is read as a script name.
[09]
Step 5: Debug the agent with dev tools
When the agent gives a wrong answer, you need to see what it did: which tools it called, with which arguments, what came back, and how many tokens each step used. Add --devtools:
promptise run --devtools main.py "Hi, where is my order A1002? It was supposed to arrive by now."promptise run support-bot · main.py · script · devtools on (observe full)
● agent model openai:gpt-5-mini 3 tool(s) 0 MCP server(s) observe full
--- Ticket 1: Hi, where is my order A1002? It was supposed to arrive by now.
▸ agent Hi, where is my order A1002? It was supposed to arrive by now.
◆ llm gpt-5-mini-2025-08-07 1.44s in 368 out 26 tok $0.0001 → lookup_order
⚙ lookup_order({'order_id': 'A1002'})
✓ lookup_order 1ms → {"order_id": "A1002", "item": "Hiking boots", "status": "in transit", "carrier": "DHL", "expected_on": "2026-10-19"}
◆ llm gpt-5-mini-2025-08-07 7.26s in 442 out 711 tok $0.0015
◂ agent done · 8.72s · 2 llm call(s) · 1 tool call(s) · 1547 tok
Thanks — I checked your order A1002. It's for Hiking boots, currently "in transit" with DHL and the expected delivery date is 2026-10-19.
If you'd like, I can open a support ticket to investigate with the carrier — want me to do that?
Trailhead Support
■ agent shut down
promptise run · exit 0 · 9.1s · 2 llm call(s) · 1547 tok (in 810 out 737) · 1 tool call(s) · 0
error(s) · cost $0.0017
agent model llm calls tokens tool calls errors cost
agent openai:gpt-5-mini 2 1547 1 0 $0.0017
tool calls errors avg ms
lookup_order 1 0 1
report: .promptise/last-run.jsonHow to read the trace, which goes to stderr while your program's output stays on stdout:
`● agent` is printed when the agent is built: its model, how many tools and MCP servers it has, and the observability level.
`▸ agent` marks a new request, with the user's message.
`◆ llm` is one model call: the model, its latency, input and output tokens, its estimated cost, and after → the tools the model asked for.
`⚙` is a tool call with its arguments, and `✓` or `✗` its result and latency.
`◂ agent done` closes the request with its totals.
The table at the end sums up LLM calls, tokens, tool calls, errors and cost per agent, per model and per tool.
What to look for: a tool called with wrong arguments means the tool's description or schema needs work. The same tool called again and again means the agent is stuck in a loop. A call with many input tokens means too much context. A slow model call is usually the one writing the final answer, and reasoning models count their reasoning as output tokens.
How it works: while promptise run runs your program, build_agent() asks it for settings before it builds each agent. It turns on observability for agents that set none, gives each agent a name, and sends the agent's events to the trace. Anything you set yourself wins. An agent built with observe=False stays unobserved, and an agent with its own observability settings keeps them. A plain promptise run without flags adds nothing.
Add --report run.json (or [dev] report) to save the whole run as JSON, which you can attach to a bug report or compare between runs.
[10]
Step 6: Restart on every change with --watch
promptise run dev # the dev script: promptise run --devtools --watch--watch runs your program in a child process and restarts it whenever a Python, TOML, YAML, JSON or .env file in the project changes. Folders like .git, .venv, __pycache__ and node_modules are ignored. Use [dev] watch and [dev] ignore to change what is watched. When the program finishes on its own, the watcher waits for the next change instead of restarting it in a loop.
[11]
Step 7: Use the terminal UI
promptise run --tui                 # run main.py in the UI (also -t or -tui)
promptise run --tui --mode chat     # chat with the agent from the factory
--tui opens a full-screen view of the run. Your program runs in a child process and its output is captured, so nothing it prints breaks the screen.
Key | Tab | What it shows |
|---|---|---|
---|---|--- | ||
1 | Chat / Console | The chat with the agent (answers stream in, tool calls inline), or your program's output with an input line for its stdin |
2 | Trace | Every LLM call and tool call of every agent, with the full details beside it |
3 | Tools | Each tool call's arguments, result and latency, and every tool each agent has |
4 | Metrics | Tokens, cost, latency, and totals per agent, model and tool |
5 | Events | Agent events such as slow tools, guardrail blocks and approvals |
6 | Approvals | Tool calls waiting for a person: a approves, d denies |
7 | Agents | Each agent's model, tools, MCP servers and features |
8 | MCP | The MCP servers and their tools |
9 | Logs | Python logs and stderr, filterable by level |
0 | Run | The project, the process, the environment (names only, never values) and the manifest |
r restarts your program, s stops it, ? lists the keys and q quits. Combine it with --watch and the program restarts inside the UI on every save.
The Approvals tab is useful when your agent can do something risky, like issuing a refund. Give the agent an ApprovalPolicy with a QueueApprovalHandler for those tools, and each call waits in the tab until you approve or deny it. Human-in-the-loop approval for AI agents explains approval policies in detail. Screenshots of every tab are in the promptise run documentation.
[12]
Step 8: Automate with scripts
[scripts] works like npm scripts:
[scripts]
dev = "promptise run --devtools --watch"
eval = "python evals/run.py"
check = "promptise run --prod --check"promptise run eval smoke # runs: python evals/run.py smoke
promptise run dev --model openai:gpt-5Anything after the script name is added to the command. Flags like --model are passed on when the script is itself a promptise command, so promptise run dev --model openai:gpt-5 runs your dev setup on another model, and --model replaces the model of every agent your program builds. Scripts run from the project root, with your project's Python environment first on PATH, so python, pytest and promptise in a script are the ones from that environment.
[13]
Step 9: Ask the agent one question from the command line
For quick checks and CI jobs, -i builds the agent from the factory, asks one question and prints the answer:
promptise run -i "How do I return a jacket that doesn't fit?" --json{"output": "You can return unworn items within 30 days of delivery. Start a return at trailhead.example.com/returns \u2014 the return label is free.\n\nWould you like me to start the return for you? If so, please share your order ID (or the email used for the order) and I\u2019ll help you from there.\n\nTrailhead Support", "error": null, "duration_ms": 8125.0, "usage": {"llm_calls": 2, "prompt_tokens": 783, "completion_tokens": 806, "total_tokens": 1589, "tool_calls": 1, "tool_errors": 0, "errors": 0, "retries": 0, "cost_usd": 0.0018077500000000001, "unpriced_models": [], "latency_p50_ms": 4353.9, "latency_p95_ms": 4353.9}}--json adds the token usage and cost, and -i - reads the question from stdin. The exit code is 0 when the agent answered and 1 when it failed, so a CI step can depend on it. Without -i, promptise run agent.py opens an interactive chat with /stats, /tools and /reset commands.
[14]
Step 10: Run the agent in production
promptise run --prod--prod changes three things:
Logs are JSON, one object per line on stderr, ready for Datadog, Grafana Loki, CloudWatch or any log pipeline. Your program's stdout is untouched.
Checks fail fast. If a required variable is missing, the run logs one preflight failed line listing every problem and exits with code 2, before any agent is built.
SIGTERM shuts down cleanly. When your orchestrator stops the container, the program gets the same signal as Ctrl+C: finally blocks run, agents close their MCP connections, and the process exits with 143.
To log each agent step too, set [prod] observe = "basic" (or pass --observe basic). Here are the log lines of one run, filtered with jq:
promptise run --prod --observe basic main.py "Where is A1003?" 2>&1 >/dev/null \
| jq -c 'select(.logger == "promptise.run.events") | {msg, agent, event: .entry.event_type} | del(..|nulls)'{"msg":"run.start"}
{"msg":"agent.built","agent":"agent"}
{"msg":"timeline","agent":"agent","event":"agent.input"}
{"msg":"event","agent":"agent"}
{"msg":"timeline","agent":"agent","event":"tool.call"}
{"msg":"timeline","agent":"agent","event":"tool.result"}
{"msg":"timeline","agent":"agent","event":"agent.output"}
{"msg":"event","agent":"agent"}
{"msg":"agent.closed","agent":"agent"}
{"msg":"run.exit"}
{"msg":"stats"}The last line of every run carries its totals (LLM calls, tokens, tool calls and cost), so you can chart cost per run from your logs.
[15]
Step 11: Serve the agent as an HTTP API
export PROMPTISE_SERVE_TOKEN="a-long-random-secret"
promptise run --serve --port 8765
--serve builds the agent from the factory and serves it:
Endpoint | What it does |
|---|---|
---|--- | |
GET /healthz | Liveness: the process is up |
GET /readyz | Readiness: the agent is built and accepting requests |
GET /v1/info | The project, model and tools |
POST /v1/invoke | Ask the agent; returns the answer and token usage |
POST /v1/stream | Ask the agent; streams tokens and tool calls as server-sent events |
curl -s -X POST localhost:8765/v1/invoke \
  -H "Authorization: Bearer $PROMPTISE_SERVE_TOKEN" -H "Content-Type: application/json" \
-d '{"input": "Where is my order A1002?"}'{"output":"Your order A1002 (Hiking boots) is in transit with DHL and is expected to arrive on 2026-10-19. \n\nIf you want me to look up tracking details or check further, tell me and I’ll help.\n\nTrailhead Support","duration_ms":6462.2,"usage":{"llm_calls":2,"prompt_tokens":790,"completion_tokens":408,"total_tokens":1198},"request_id":"9ae9deb1430f426c83fcd75e1130c17c"}Requests to /v1/* need the bearer token from the variable [serve] auth_token_env names. Pass a session_id to keep a conversation going when your agent has a conversation store. When the server is stopped, it answers new requests with 503, lets running requests finish, and exits with code 0.
To run it in Docker:
FROM python:3.12-slim
WORKDIR /app
COPY . .
RUN pip install --no-cache-dir "promptise>=1.4.1"
# Configuration comes from the container's environment, not from a .env file.
# Set OPENAI_API_KEY and PROMPTISE_SERVE_TOKEN when you start the container.
ENV PROMPTISE_NO_DOTENV=1
CMD ["promptise", "run", "--prod", "--serve", "--host", "0.0.0.0", "--port", "8080"][16]
Common problems and fixes
Symptom | Cause | Fix |
|---|---|---|
---|---|--- | ||
| A bare word after promptise run is read as a script name | Name the main file first: |
| The variable is not in your shell or in the .env files listed under [env] files | Add it to .env (copy .env.example), or export it |
|
| Build it in a factory, async def create_agent(ctx=None), and set agent = "agent.py:create_agent" |
| A typo in promptise.toml | Fix the key; unknown keys are always errors |
Cost shows — | The model has no entry in [pricing] | Add "model-name*" = { input = ..., output = ... } in USD per million tokens |
| Serving on a network address with no bearer token | Set PROMPTISE_SERVE_TOKEN (or the variable [serve] auth_token_env names) |
--tui fails in CI | The terminal UI needs an interactive terminal | Use --check, --devtools, --report or -i --json in CI |
The container uses an old key | A .env file was copied into the image | Set PROMPTISE_NO_DOTENV=1 and pass configuration through the container's environment |
An agent shows no trace | It was built with observe=False, which promptise run respects | Remove observe=False, or set your own observe level |
[17]
Best practices
Keep one agent factory per project and use it everywhere: in main.py, in tests, and in promptise run --serve. Then the agent you debug is the agent you deploy.
Add a check script (
promptise run --prod --check) and run it in CI, so a missing variable or a broken manifest fails the build instead of the deployment.Fill in [pricing] for the models you use, so the cost shows up while you develop, not on your invoice.
Save a run report ([dev] report) when you reproduce a bug, and compare the tool calls between a good run and a bad one.
Use --model to try the same project on another model before you change any code.
[18]
Limitations
promptise run runs one process. Scaling, TLS and routing stay with your platform (Kubernetes, Cloud Run, a load balancer).
Serve mode has one bearer token, not per-user accounts. Put it behind your own gateway when users authenticate.
Costs are estimates from your [pricing] table, not your provider's invoice.
The terminal UI needs an interactive terminal.
[19]
FAQ
How do I run a Python AI agent project?
Describe it in a promptise.toml with a main file, then run promptise run from anywhere in the project. It loads your environment, checks the project, and runs the main file like python main.py. promptise init --project creates a project to start from.
How do I debug an AI agent in Python?
Run it with promptise run --devtools. You see every model call with its tokens, latency and cost, every tool call with its arguments and result, and a summary at the end. For a full-screen view with a trace you can browse, use promptise run --tui.
How do I see the token usage and cost of my agent?
--devtools prints the tokens and estimated cost of each LLM call and the totals per agent and model. -i --json returns them with the answer, --serve returns them in each /v1/invoke response, and --prod logs them at the end of every run. Add your prices to [pricing] for the cost.
Do I have to change my agent code to use promptise run?
No. Your main file is a normal Python script, and the dev tools work by hooking into build_agent() while promptise run is running. You only need an agent factory for chat mode, -i and --serve.
How do I deploy an AI agent as an API?
Run promptise run --prod --serve with a bearer token in the environment. It exposes health and readiness checks, an invoke endpoint and a streaming endpoint, and drains running requests on shutdown. Deploy AI agents in production covers the rest of a production setup.
Does promptise run work with MCP servers?
Yes. MCP servers you pass to build_agent() work as usual, and their tool calls appear in the dev tools, the Trace and Tools tabs, and the MCP tab. Connect MCP servers to an AI agent shows how to add them.
[20]
Next steps
Gate risky tool calls with human-in-the-loop approval, then answer them from the TUI's Approvals tab.
Give the agent real tools with MCP servers.
Learn what to record in production in AI agent observability.
Put a ceiling on spend with AI agent cost control.
Catch regressions before you deploy with AI agent evaluation in Python.
Plan the rest of the rollout with deploying AI agents in production.