Contents · 6 sections↓
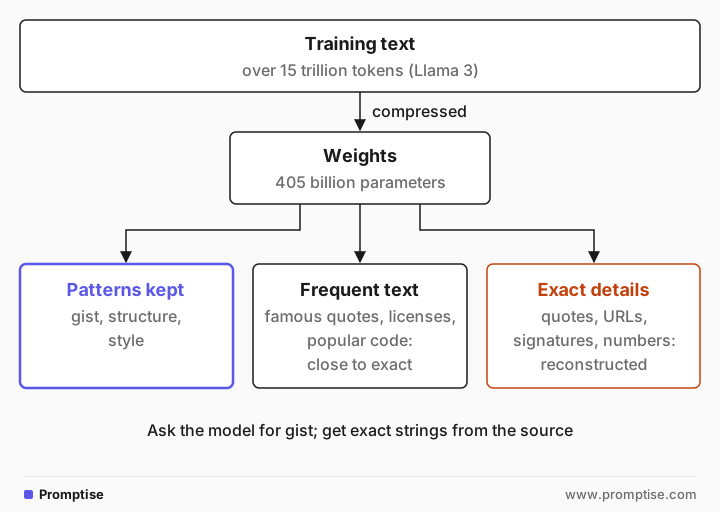
Ted Chiang called ChatGPT "a blurry JPEG of the web". The comparison holds up better than most metaphors: a model squeezes a huge amount of text into a fixed set of weights, keeps the patterns and loses the exact bytes. This essay, part of the Mental Models learning path, explains what that means technically, which outputs survive compression (gist, structure, style) and which don't (quotes, URLs, signatures, numbers), with a real example of the model "quoting" Python documentation.
Is an LLM a lossy compression of its training data?
In a useful sense, yes. Predicting the next token well is mathematically equivalent to compressing text well, and a model's weights are far smaller than the text it trained on, so it can't keep everything. What it keeps are the regularities: how ideas relate, how documents are structured, how a topic is usually explained. Exact wording is kept only for text repeated many times. When you ask for a verbatim string, the model reconstructs something plausible from the pattern.
Key takeaways:
Ask the model for gist; get exact strings from the source. Quotes, URLs, version numbers and API signatures are where compression shows.
Fluent is not faithful. A reconstruction reads as smoothly as the original.
Transforming text you supply is the model's strong suit. Summarizing, restructuring and explaining work from the real bytes in the prompt.
[02]
Why it's true
Language Modeling Is Compression (Delétang et al., ICLR 2024) makes the equivalence concrete: any model that predicts the next symbol can drive an arithmetic coder, and better prediction means smaller files. Chinchilla 70B, trained mainly on text, compressed ImageNet patches to 43.4% of raw size and LibriSpeech audio to 16.4%, beating PNG (58.5%) and FLAC (30.3%).
The size gap does the rest. Meta's Llama 3 paper (2024) describes training on over 15 trillion tokens; the largest model has 405 billion parameters. The weights are a fraction of the training text, so most passages can't be stored word for word. Some are: Extracting Training Data from Large Language Models (Carlini et al., 2021) recovered memorized sequences from GPT-2, and Quantifying Memorization (Carlini et al., 2023) found memorization grows with model size, with how often a sequence is duplicated in the data, and with how much context the prompt gives. Frequent text comes back close to exact; ordinary text comes back as its gist.
Chiang's New Yorker essay (2023) drew the practical conclusion: compression artifacts in text look like plausible facts, which is what makes them hard to spot.
[03]
Example: "quoting" the Python docs
Quote, verbatim and complete, the docstring of each of these Python standard library objects (CPython 3.12). Use a heading line '### name' before each docstring and output nothing else.
textwrap.dedent
shutil.copy2
itertools.groupby
str.partition
The model's str.partition:
Split the string at the first occurrence of sep, and return a 3-tuple
containing the part before the separator, the separator itself, and the
part after the separator.
…
The real CPython 3.12 docstring (inspect.getdoc(str.partition)):
Partition the string into three parts using the given separator.

This will search for the separator in the string.  If the separator is found,
returns a 3-tuple containing the part before the separator, the separator
itself, and the part after it.
…
Same meaning, different words. The model's version is almost word for word the entry in the online library reference, a different and much more widely copied text. Asked for one text, it returned the more frequent one. For itertools.groupby it went further and added an example that is not in the docstring:
    >>> for key, group in groupby('AaaBBcCc'):
    ...     print(key, list(group))
    A ['a', 'a']
    B ['a']
    …
Running that code prints A ['A'], then a ['a', 'a'], then B ['B', 'B']. The invented example has invented output. The textwrap.dedent and shutil.copy2 "quotes" were also paraphrases with different content from the real docstrings. Results vary by model, but no current model can promise a verbatim quote from memory.
[04]
What it changes in practice
Split requests into gist and exact parts. "Explain how groupby works" is a good use of compressed knowledge. "Give me the exact signature" or "quote the clause" needs the source.
Put exact strings in the context, or give the model a tool. Paste the document, run help(), fetch the page, or expose a lookup tool through tool calling. Then ask the model to quote from what it was given, and check the quote is a substring of the source in code.
Distrust specifics that arrive without a source. Citations, URLs, statistics, version numbers and legal wording from memory are reconstructions. Treat them as leads to check, not facts.
[05]
Frequently asked questions
What does "ChatGPT is a blurry JPEG of the web" mean?
It is Ted Chiang's 2023 analogy: like a JPEG, a language model stores a compressed approximation of its input. It keeps the overall picture and loses fine detail, and when you ask for detail it fills in something plausible, the way a JPEG decoder fills in pixels.
Do LLMs memorize their training data?
Some of it. Text that appears many times, such as famous quotes, licenses and popular code, can be reproduced nearly verbatim, and larger models memorize more. Most text is not stored word for word.
Why can't the model give me an exact quote or URL?
Because exact strings are the details lossy compression drops first. The model generates a string that fits the pattern of the source, which is often close and sometimes entirely made up. Supply the source and verify quotes mechanically.
Is lossy compression the same as hallucination?
It is one cause. Reconstructing a detail that wasn't stored produces a confident, plausible error. Hallucinations also come from missing knowledge and from training that rewards guessing.
[06]
Next steps
Why LLMs get niche facts wrong: how often a fact appears predicts whether it survives.
LLM hallucinations: quick checks: includes a quote-matching check in Python.
Grounding LLM answers: put the source in the prompt.
LLM as a tool orchestrator: fetch exact data through tools.
Mental Models: How to Think with LLMs: the full learning path.