Contents · 6 sections↓
The most expensive LLM mistakes aren't the obvious ones. They're outputs that look exactly like correct work: a regex that reads as thorough, a package name that sounds real, a function with a sensible docstring. This essay explains why models produce plausible-but-wrong artifacts, why reading them is a weak check, and how to make every important output checkable by running it. It's for developers and anyone who ships what a model writes.
Why does AI-generated code look right when it's wrong?
Because the model is trained to produce text that resembles correct text, and resemblance is what you check when you read. Looking right and being right are different properties, and only the first one is optimized directly. So errors land where a reader won't notice: an unbalanced parenthesis in a long regex, a leap-year rule that's almost complete, an import of a package that doesn't exist. Running the code catches what reading misses.
Key takeaways:
Plausibility is the default output. Next-token prediction and RLHF both reward answers that look complete and competent.
Reading is a weak check. Reviewers, including you, tend to approve fluent work. In one study, people with an AI assistant wrote less secure code and were more confident it was secure.
Execution is a strong check. Compile it, run it, test it, import it, look it up.
Ask for checkable output. Request tests and use well-known library functions, so verification is cheap.
[02]
Why it's true
During pretraining the model learns what code and prose usually look like. During instruction tuning and RLHF (Ouyang et al., 2022), it's tuned toward answers human raters prefer, and raters judge mostly by reading. Neither stage runs the code. The model gets very good at producing the shape of a correct answer, and the shape is usually, but not always, accompanied by correctness.
Two research results show the cost. Perry et al., Do Users Write More Insecure Code with AI Assistants? (CCS 2023), found that participants with an AI assistant wrote significantly less secure code than those without one, and were more likely to believe their code was secure. Spracklen et al., We Have a Package for You! (USENIX Security 2025), tested code-generating models and found that on average at least 5.2% of recommended packages from commercial models, and 21.7% from open-source models, didn't exist: 205,474 unique made-up package names. Attackers can register those names and wait for someone to pip install them.
[03]
Example: a date regex that looks thorough
A common request, run on gpt-5-mini; results vary by model.
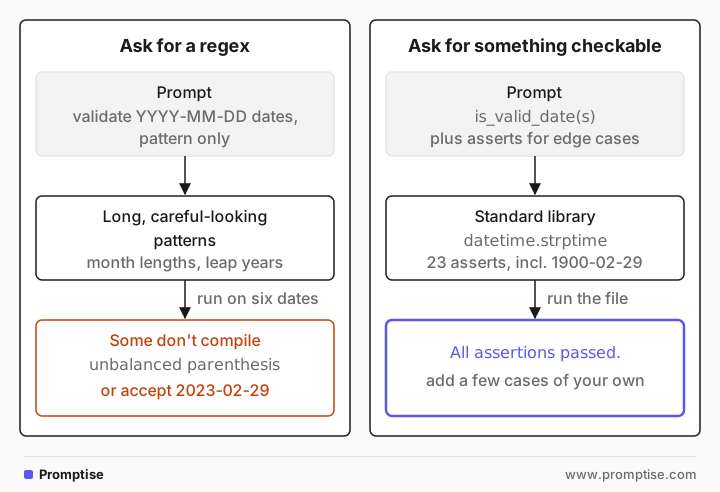
Write a Python regular expression that validates calendar dates in YYYY-MM-DD format.
Reply with the pattern only, no explanation.
Each answer was a long, careful-looking pattern with month lengths and leap-year rules. One of them:
^(?:(?:[0-9]{4})-(?:(?:(?:0[13578]|1[02])-(?:0[1-9]|[12][0-9]|3[01]))|(?:(?:0[469]|11)-
(?:0[1-9]|[12][0-9]|30))|(?:02-(?:0[1-9]|1[0-9]|2[0-9]))))|(?:(?:[0-9]{2}(?:0[48]|[2468]
[048]|[13579][26])|(?:[02468][048]00|[13579][26]00))-02-29))$
Run against six test dates:
Some of the patterns don't compile: unbalanced parenthesis.
One that compiles accepts 2023-02-29, a date that doesn't exist.
None of this is visible by reading. Now a prompt that asks for something checkable:
Write a Python function is_valid_date(s: str) -> bool that accepts only real calendar
dates in YYYY-MM-DD format. Use the standard library rather than a regex if that is more
reliable. Below it, write plain assert statements covering edge cases: leap years
(including century years), invalid months and days, wrong separators, extra whitespace.
Output one Python code block and nothing else.
The model used datetime.strptime plus a round-trip check, and wrote 23 asserts, including 1900-02-29 (not a leap year) and 2000-02-29 (a leap year). Running the file:
All assertions passed.Two changes made the difference. The function delegates the hard part to a tested library instead of a hand-built pattern, and the tests turn "looks right" into "ran and passed". Model-written tests can share the code's blind spots, so add a few cases of your own for the inputs you care about.
[04]
What it changes in practice
Verify by execution, not inspection. Compile and run generated code, and run its tests. For SQL, run it on a copy with known data. For config, validate against the schema.
Check every dependency. Before installing a package a model suggested, confirm it exists on the registry, is the one you meant, and is maintained. Pin versions.
Prefer boring, verifiable building blocks. Ask for standard-library or well-known library calls over clever hand-written logic, and ask for tests with the code.
Raise the bar with the stakes. A throwaway script needs a run. Code that handles money, auth or user data needs tests you wrote and a human review.
[05]
Frequently asked questions
What is an AI code hallucination?
Generated code that refers to things that don't exist or behave differently than claimed: made-up functions, wrong parameters, nonexistent packages, or logic that doesn't do what the comments say. It's the code version of a factual hallucination.
What is slopsquatting?
Registering a package name that LLMs tend to invent, so that developers who install the suggested package get the attacker's code. Spracklen et al. found that many hallucinated names come back when the same prompt is repeated, which makes this practical.
Can the model check its own code?
Self-review catches some errors, but it's the same model with the same blind spots. Running the code gives feedback the model can't fake. See the guide on LLM self-correction for why external feedback matters.
Are model-written tests enough?
They're a good start and catch real bugs, but they test what the model thought of. Add tests for your own edge cases and real data, especially where errors would be costly.
[06]
Next steps
Execute model code without risk: AI agent code execution sandbox.
Dependency and model supply-chain risks: LLM supply chain security.
Check outputs before using them: output verification.
Token-level blind spots: why LLMs can't count letters.
Test prompts like code: test LLM prompts in Python.