Contents · 7 sections↓
"Stochastic parrot" is the best-known criticism of large language models: they repeat patterns from their training text without understanding it. This essay explains where the term comes from, which parts hold up and which don't, and the one practical habit it should leave you with: a model's answer reflects what text usually says, not what is true for your case, unless you put your case in the prompt. It's for anyone building with or relying on LLM output.
Are LLMs stochastic parrots?
Partly. The term comes from Bender, Gebru, McMillan-Major and Shmitchell, On the Dangers of Stochastic Parrots (FAccT 2021). They describe a language model as stitching together word sequences from its training data by probability, "without any reference to meaning." That is a fair description of the training objective. Whether models therefore understand nothing is still debated, and some evidence points to internal models of the world. The practical part isn't in dispute: without your facts in the context, the model gives you the typical answer.
Key takeaways:
The objective is prediction. A base model is trained to predict the next token of internet-scale text. Instruction tuning and RLHF shape how it answers, not where its knowledge comes from.
Fluency is not evidence. A well-formed answer tells you the pattern is common, not that it applies to you.
No facts in, typical facts out. If the prompt doesn't contain your policy, prices or code, the model fills the gap with what similar text usually says.
"Just a parrot" undersells it. Models can learn internal models of the world. That's a reason to use them, not to trust them blindly.
[02]
Why the description is partly true
A model learns from text alone. During pretraining it sees trillions of tokens and adjusts its weights to make the next token more likely. It never sees the things the words refer to: the tent, the refund, the customer. Bender and Koller made this argument earlier in Climbing towards NLU (ACL 2020): a system trained only on form can't learn meaning in the full sense, because meaning connects words to things and intentions outside the text.
You can see traces of this in how knowledge is stored. Berglund et al., The Reversal Curse (2023), showed that models fine-tuned on "A is B" often fail to answer "who is B?" The knowledge sits in the direction the text was written. Famous examples get fixed in later models, partly because the papers become training data.
The paper's main concern was consequences: training data over-represents some voices, and a model that reproduces its data reproduces that skew, fluently.
[03]
Why "just a parrot" goes too far
Parrots don't generalize. Models do, at least sometimes. Li et al., Emergent World Representations (ICLR 2023), trained a small transformer only on sequences of Othello moves and found an internal representation of the board state that they could read and edit, changing the moves it predicted. That's a world model learned from sequences alone, in a toy domain.
Post-training matters too. Instruction tuning and RLHF (Ouyang et al., 2022) make the model follow instructions and give answers people rate highly, which also makes it eager to give a complete, confident answer.
The working position is: a prediction machine with real but uneven abilities, whose knowledge comes from text statistics, not from your situation.
[04]
What it changes in practice
Put the facts in the prompt. For anything specific to you (policies, prices, product names, your codebase), include the source text or retrieve it. The model can't know it otherwise, and it won't always say so.
Tell it what to do when the source doesn't cover the question. Give it a way out: "say so and hand over to a person". Without one, the trained urge to be helpful fills the gap.
Read fluent answers as "typical", not "checked". Check the parts that matter against a source.
[05]
Example: the typical answer vs your answer
A support assistant without the shop's return policy. Run on gpt-5-mini; results vary by model.
System: You are the customer support assistant for Northwind Outdoor, an online shop.
User: How long do I have to return a tent I bought?
Every answer gave a confident, detailed policy. None existed:
Thanks — I can help with that. Our standard return window for tents is 30 days from
the date of delivery for unused, undamaged items returned in their original packaging.
A few important details:
- The tent must be clean, free of dirt, odors (including smoke), pet hair, and mildew.
…
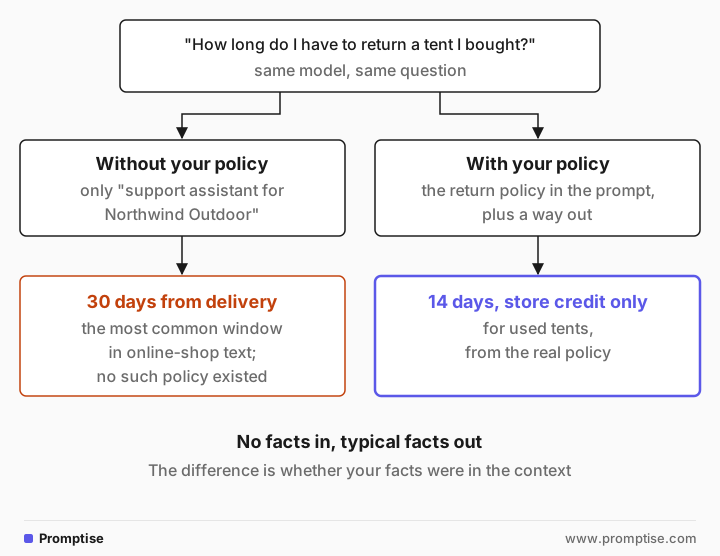
Thirty days is the most common return window in online-shop text, so that's what came out. Now with the real policy and a way out:
System: You are the customer support assistant for Northwind Outdoor, an online shop.
Answer only from the policy below. If it doesn't cover the question, say so and offer
to connect the customer to a person.

Return policy (Northwind Outdoor, updated 2026-03): Unused items: 60 days from delivery.
Tents and sleeping bags that have been used: 14 days, store credit only. Sale items: final sale.

User: How long do I have to return a tent I bought? I set it up once in the garden.Tents that have been used (set up even once) can be returned within 14 days of delivery,
and they are eligible for store credit only.Same model, same question. The difference is whether your facts were in the context.
[06]
Frequently asked questions
What does "stochastic parrot" mean?
It's a term from Bender et al. (2021) for a language model that strings words together based on how often they appear together in its training data, with no grasp of what they refer to. "Stochastic" means probabilistic: the model samples from a distribution over next tokens.
Do LLMs understand what they say?
It depends on what you mean by understand. They have no direct contact with the world and no communicative intent in the human sense. But research such as the Othello-GPT study shows they can learn internal representations that track a state of the world. Most researchers place current models somewhere between "parrot" and "understanding", and the debate is open.
Does RLHF stop models from parroting?
No. Instruction tuning and RLHF change how the model answers: it follows instructions, refuses some requests and formats answers helpfully. Its knowledge still comes from pretraining text. RLHF can even make gap-filling more convincing, because it rewards complete, confident answers.
How do I stop a model from making things up about my product?
Give it the source text in the prompt (or retrieve it with RAG), tell it to answer only from that text, and tell it what to do when the text doesn't cover the question. Then check answers against the source in tests.
[07]
Next steps
Ground answers in your own documents: context is king: grounding.
Build retrieval on a small corpus: RAG from zero to one.
Spot and check made-up answers: hallucination basics and quick checks.
Why familiar patterns override what you wrote: why LLMs fail modified puzzles.
How knowledge is stored, and lost: LLM as a compression engine of human knowledge.