Contents · 8 sections↓
Skeleton-of-Thought (SoT) prompting writes a long answer in two stages: one call produces a short outline, then each outline point is expanded in its own call, all at the same time. The goal is lower latency for long, list-like answers, with structure as a side benefit. This guide is for developers generating reports, guides or multi-part answers. It covers how SoT works, a runnable Python version with section word budgets and real output, and when the extra calls are not worth it.
What is Skeleton-of-Thought prompting?
Skeleton-of-Thought asks the model for the skeleton of its answer first, a handful of short numbered points, and then expands every point in parallel API calls. Because the points are written at the same time, total time is close to the skeleton call plus the slowest point, instead of the whole answer written token by token. A per-point word budget keeps sections even and the total length predictable.
Key takeaways:
SoT is a latency technique, not a reasoning technique. It helps when the answer is long and its parts are independent.
Section budgets come almost free: each point call gets its own word limit, and the model tends to follow it.
It does not fit step-by-step answers: math, code, or arguments where point 3 depends on point 2.
Parallel points can't see each other. Check the assembled answer for repeats, gaps and invented numbers.
[02]
How Skeleton-of-Thought works
Skeleton-of-Thought: Prompting LLMs for Efficient Parallel Generation (Ning, Lin, Zhou, Wang, Yang and Wang, 2023) starts from a simple observation: models decode one token after another, so a long answer takes long. People often outline first and fill in later. SoT copies that:
Skeleton stage. A prompt asks for a numbered list of short points, with no details.
Point-expanding stage. One prompt per point, each containing the question, the full skeleton and the instruction to write only that point. These run as parallel API calls, or as one batch on your own hardware.
Assembly. Concatenate the expanded points in order.
The paper reported considerable speed-ups across 12 models and better answer quality on some question categories. It also noted that SoT suits answers made of independent points, and proposed a router (SoT-R) that sends other questions to normal generation.
[03]
Worked example: cutting a cloud bill
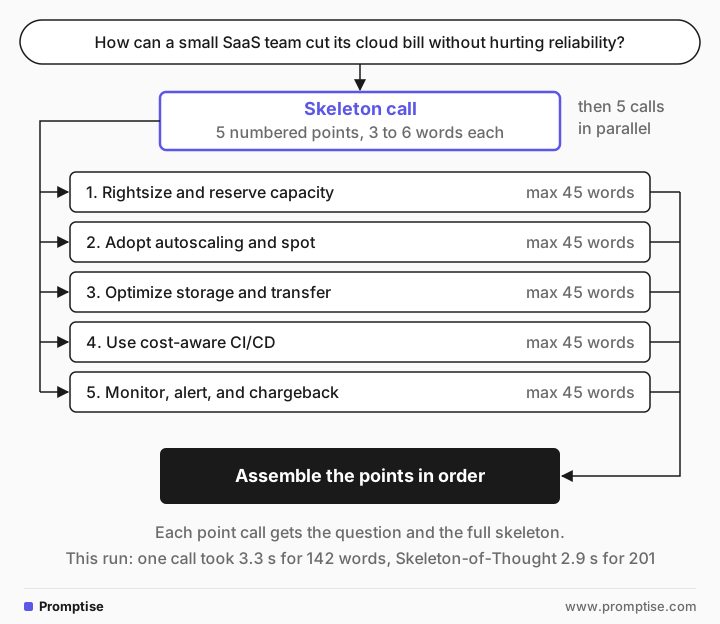
The question: "How can a small SaaS team cut its cloud bill without hurting reliability?" The baseline is one call asking for 4 to 6 numbered points of at most 45 words each. The SoT version uses two prompts:
Question: {question}
Write only the skeleton of the answer: 4 to 6 numbered points, each 3 to 6 words. No details.Question: {question}
Skeleton of the full answer:
{skeleton}
Write point {i} only ("{point}") in at most {budget} words. Be concrete. Do not repeat other points.
Start with the point text, no number.And the code that runs them:
import asyncio
import re
from openai import AsyncOpenAI

client = AsyncOpenAI()


async def ask(prompt: str) -> str:
    r = await client.chat.completions.create(
        model="gpt-5-mini", messages=[{"role": "user", "content": prompt}], reasoning_effort="minimal")
    return r.choices[0].message.content


async def skeleton_of_thought(q: str, budget: int = 45) -> str:
    skeleton = await ask(SKELETON.format(question=q))
    points = re.findall(r"^\s*\d+[.)]\s*(.+)$", skeleton, flags=re.M)
    bodies = await asyncio.gather(*[
        ask(EXPAND.format(question=q, skeleton=skeleton, i=i, point=p, budget=budget))
        for i, p in enumerate(points, 1)
    ])
    return "\n".join(f"{i}. {b.strip()}" for i, b in enumerate(bodies, 1))
SKELETON and EXPAND are the two prompts above. The skeleton came back as:
1. Rightsize and reserve capacity
2. Adopt autoscaling and spot
3. Optimize storage and transfer
4. Use cost-aware CI/CD
5. Monitor, alert, and chargeback
And the timing line plus the assembled answer (trimmed):
one call: 3.3s, 142 words
skeleton-of-thought: 2.9s, 201 words

1. Rightsize and reserve capacity — audit instance/memory/CPU usage, downsize oversized VMs and databases, replace underutilized dedicated instances with smaller tiers, and buy reserved/commitment plans for steady baseline load (1–3 year reservations or savings plans) to cut unit costs 30–70%.
2. Adopt autoscaling and spot
Enable horizontal autoscaling with conservative min/max to match load; use CPU/RPS-based metrics and cooldowns. …
4. Use cost-aware CI/CD: run tests on smaller runners, cache dependencies, parallelize smartly, fail fast, gate expensive end-to-end suites to nightly or main-branch only, …
…
Three things to read from this output:
The speed-up was small. With a fast model at minimal reasoning and short sections, one call is already quick, and SoT adds a round trip for the skeleton. The gain grows with longer sections and slower models, because parallel points then save more time than the skeleton costs. Timings vary from run to run.
The budgets held. Each point came back at 38 to 41 words against a limit of 45. Per-call budgets are easier for the model to follow than one overall length limit.
Isolation shows. Point 2 repeated its heading on its own line, and point 1 included a "30–70%" figure that no source backs. Each point call writes without seeing the others' text, so formatting drifts and unsupported numbers slip in. Normalize the format in code and review numbers before publishing.
The SoT answer is also more specific: point 4 (CI/CD costs) is a topic the one-call answer did not cover. A fixed outline spreads attention across topics instead of letting the first points take most of the space.
[04]
Section budgets without parallel calls
You can keep the structure benefit in a single call. Write or generate the outline, then give each section a budget in one prompt:
Write the answer with exactly these sections, in this order:
1. Rightsize and reserve capacity (max 45 words)
2. Adopt autoscaling and spot (max 45 words)
3. Optimize storage and transfer (max 45 words)
Do not add sections. Do not repeat a point in two sections.
This is slower than parallel SoT for long outputs, but each section sees the previous ones, so repetition drops. For long documents, budgets per section work better than one total word count; see long-form control.
[05]
When to use Skeleton-of-Thought (and when not to)
Use it for | Skip it for |
|---|---|
Long answers made of independent parts: tips, comparisons, FAQ drafts, report sections | Math, code and proofs, where each step depends on the last |
Streaming UIs where the outline can be shown first | Short answers, where the skeleton call costs more than it saves |
Documents that must hit a section structure and length | Narrative text where flow between sections matters |
Batch jobs on your own GPUs, where batched decoding is cheap | Strict per-request rate limits, since SoT multiplies requests |
What changes with reasoning models
SoT is about output length, not thinking, so reasoning models do not replace it. They change two things. First, each parallel point call may spend reasoning tokens of its own, which adds cost and time; run point expansion at the lowest reasoning setting and keep any heavy reasoning for the skeleton. Second, a reasoning model often produces a good plan internally, so if latency is not a problem, one call with a section list and budgets gives a coherent answer at lower cost.
[06]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Skeleton points written as full sentences | Points overlap and expansions repeat each other | 3 to 6 words per point, no details |
Expanding a point without the full skeleton | The model doesn't know what other points cover | Include the whole skeleton in every point prompt |
Using SoT for dependent steps | Point 3 can't use point 2's result | Normal generation, or least-to-most |
One overall word limit | Some sections run long, others get one line | A budget per section |
No assembly check | Duplicate headings, mixed formats, unsupported numbers | Normalize format in code; review figures |
Heavy reasoning on every point call | Cost and time grow with the number of points | Minimal reasoning for expansion |
[07]
Frequently asked questions
Does Skeleton-of-Thought improve quality or only speed?
Mainly speed. The paper also reported better answers on some question categories, and an outline tends to cover more ground evenly, as in the example above. It can hurt coherence because points are written independently, so check the assembled text.
How many skeleton points should I ask for?
Four to eight works for most answers. Fewer points save little time; many points mean many parallel requests and more overlap between them.
Can I stream a Skeleton-of-Thought answer?
Yes. Show the skeleton as soon as it arrives, then fill in each point as its call finishes. Users see structure quickly, which makes the response feel faster.
What's the difference between Skeleton-of-Thought and an outline prompt?
An outline prompt asks one call to plan and write. SoT separates the two and expands points in parallel. If you don't need the speed, the single-call outline with section budgets is simpler.
Does SoT work with structured output?
Yes. Ask for the skeleton as JSON (a list of point titles) with your API's structured-output mode, which makes the parsing step reliable. See structured outputs.
[08]
Next steps
Length and density across a document: long-form control.
Reasoning that depends on order: chain-of-thought for beginners and least-to-most.
Parse the skeleton reliably: structured outputs.
Check the numbers each section invents: verification loops.
Show the format you want: few-shot examples the right way.