Contents · 6 sections↓
LLMs are good at problems they have seen many times, and that strength becomes a bias when your problem only looks like a famous one. Change one detail of a well-known riddle and the model often answers the original. This essay explains why that happens, what research says about it, and how to work around it when your real task resembles a common template but differs in a way that matters. It's for anyone who uses models for reasoning, code or analysis.
Why do LLMs fail modified puzzles?
Because a model predicts the most likely continuation, and for a familiar-looking problem the most likely continuation is the familiar answer. When your version changes a detail, the pull of the memorized pattern can outweigh the words you actually wrote. McCoy et al., Embers of Autoregression (2023), found that GPT-4 decoded a simple cipher with 51% accuracy when the answer was a high-probability sentence and 13% when it was low-probability, on the same task.
Key takeaways:
Familiar surface, familiar answer. The closer your problem looks to a common one, the stronger the pull toward the common solution.
Explicit text doesn't always win. In the example below, the model quotes the changed detail and still gives the classic answer.
More reasoning isn't a guaranteed fix. Higher reasoning effort didn't help in the example.
Change the surface. Restating the problem in neutral terms, without the famous framing, helps more than warnings do.
[02]
Why it happens
Pretraining rewards predicting text as it usually appears. A riddle that shows up thousands of times online, always with the same answer, becomes a strong pattern: the opening sentences make the classic answer very likely before the model reaches your changed detail. McCoy et al. call this sensitivity to probability: models do better when the task, the input or the output is common in training data, even when the logic is identical.
Wu et al., Reasoning or Reciting? (2023), tested "counterfactual" versions of tasks: arithmetic in base 9 instead of base 10, chess with the knight and bishop starting positions swapped, code in a variant of Python with 1-based indexing. Performance dropped on the variants across tasks, which suggests part of what looks like reasoning is recall of the default case.
None of this means models can't reason. It means they reason best on the version of a problem they saw most, and you can't see from the output which mode you got.
[03]
Example: the surgeon riddle, changed
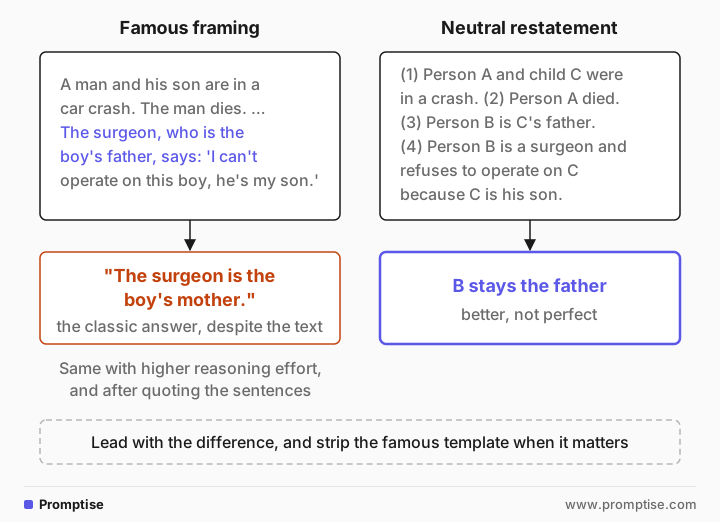
The classic riddle has a surgeon say "I can't operate, he's my son" after the father dies; the answer is that the surgeon is the boy's mother. This version states outright that the surgeon is the father. Run on gpt-5-mini; results vary by model.
A man and his son are in a car crash. The man dies at the scene. The boy is rushed to
hospital. The surgeon, who is the boy's father, looks at him and says: 'I can't operate
on this boy, he's my son.' How is this possible? Answer in two sentences.
The model gave the classic answer every time, contradicting the text:
The surgeon is the boy's mother. The surgeon could be female, so she is both the boy's
parent and the surgeon.
Higher reasoning effort gave the same answer. Asking it to quote the relevant sentences first didn't help either:
"The surgeon, who is the boy's father, looks at him and says: 'I can't operate on this
boy, he's my son.'"
…
Answer (two sentences): The surgeon is the boy's mother. The apparent paradox arises
from the assumption that surgeons are male.
What helped was removing the famous surface and stating the facts neutrally:
Facts: (1) Person A and child C were in a crash. (2) Person A died. (3) Person B is C's
father. (4) Person B is a surgeon and refuses to operate on C because C is his son.
Question: how can facts 1-4 all be true at once? Answer in two sentences.
Most answers now kept B as the father, for example:
Person B is the surgeon who refuses to operate because the child C is his son — and
Person A, who died in the crash, is C's other parent (the child's mother). …
That's better, not perfect, which is the honest state of things.
[04]
What it changes in practice
Riddles are a clean demonstration. The same pull shows up in real work whenever your task is a near-copy of a common one: a fiscal year that starts in April, a week that starts on Sunday, an API that looks like a popular one but takes different arguments, a contract clause that differs from the standard template.
Lead with the difference. Put what's unusual about your case first and state it plainly ("Unlike standard X, ours does Y"), instead of burying it in the middle of a familiar description.
Strip the template when it matters. If the problem has a famous shape, restate it in neutral terms: plain facts, renamed entities, no well-known framing.
Check the deviation specifically. When you review output, look first at the one place your case differs from the default. That's where errors cluster. A test that exercises the unusual rule catches this quickly.
Explicit instructions usually do work for ordinary tasks. A FizzBuzz request that said "Buzz for multiples of 7" used 7 every time. The risk is highest when the famous pattern is strong and your change is small.
[05]
Frequently asked questions
Do reasoning models still fall for modified riddles?
Less often, but yes. In the example above, a reasoning model with medium effort still answered the classic version. Reasoning helps when the model notices the conflict; it doesn't help if the familiar reading wins before reasoning starts.
Is this the same as the model being biased?
It's a statistical bias, not a social one: a pull toward high-probability answers from training data. It can overlap with social bias, as in the surgeon riddle, where the classic answer is itself about a stereotype.
Does chain-of-thought fix this?
Sometimes. Step-by-step reasoning helps the model notice a stated fact, but its reasoning can also follow the familiar path. Restating the problem in neutral terms is more reliable than asking for more steps.
How do I test whether a model is reasoning or reciting?
Make a counterfactual variant: change one rule or detail that would change the answer, and see whether the answer changes. That's the method in Wu et al. If the answer stays the same, the model is likely recalling the common case.
[06]
Next steps
Why the default answer is the typical one: are LLMs stochastic parrots?
Get the reasoning out before the answer: LLM as a probability map.
Step-by-step prompting: chain-of-thought lite.
Break problems into sub-questions: self-ask and decomposition prompts.
Why a model's own explanation can mislead: LLM as a glass box.