Contents · 10 sections↓
- 01What is RAG, and how do you build a simple one?
- 02How RAG works
- 03Step 1: Load and chunk the documents
- 04Step 2: Embed and retrieve
- 05Step 3: Answer from the passages, with citations
- 06Step 4: Handle questions the documents don't cover
- 07When to use simple RAG (and when not)
- 08Common mistakes
- 09Frequently asked questions
- 10Next steps
RAG (retrieval-augmented generation) means finding the passages in your own documents that relate to a question and giving them to the model, so it answers from your text instead of from memory. This guide is for developers who want to understand RAG by building the smallest version that works: a handful of Markdown files, about 50 lines of Python, answers with citations, and an honest "not covered" when the documents don't say. Real output included.
What is RAG, and how do you build a simple one?
RAG has two parts: retrieval finds the most relevant chunks of your documents for a question, and generation asks the model to answer using only those chunks, citing them. To build one: split documents into chunks, turn each chunk into an embedding (a vector of numbers that captures meaning), embed the question the same way, take the closest chunks, and put them in a grounded prompt.
Key takeaways:
Retrieval decides the answer. If the right chunk isn't retrieved, the model can't use it.
Chunk by meaning. Paragraphs or sections, each tagged with an id you can cite.
Retrieval always returns something, even for questions your documents don't cover. The prompt must allow "not covered".
For a tiny corpus, skip the infrastructure. A list in memory and a dot product are enough.
Check citations, not just answers.
[02]
How RAG works
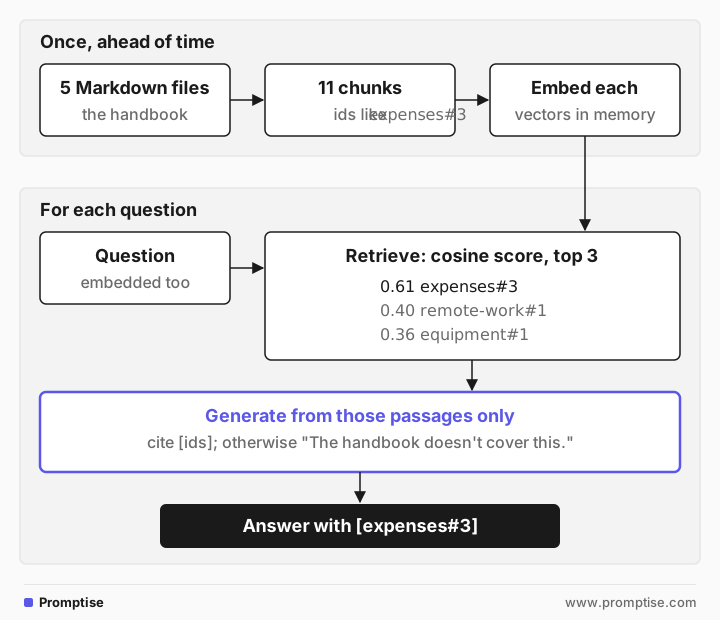
The term comes from Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks (Lewis et al., 2020), which combined a neural retriever over Wikipedia with a text generator. Today "RAG" usually means the simpler pipeline in this guide, built around an off-the-shelf embedding model and a chat model:
Chunk. Split each document into passages small enough to be about one thing.
Embed. Convert each chunk to a vector with an embedding model. Similar meanings give similar vectors.
Retrieve. Embed the question, score every chunk by cosine similarity, keep the top k.
Generate. Send the question and the top chunks to the model with rules: use only these passages, cite them, say so if the answer isn't there.
Why bother? Without retrieval, the model answers from general knowledge. Asked "Can I expense a coworking space when I work from another city?" with no documents, it replied:
Possibly — if your employer reimburses it or their travel/temporary-work policy allows, a coworking fee for a business trip or temporary work location can be expensed. If you’re self‑employed, coworking is generally deductible … note that most W‑2 employees in the U.S. cannot deduct unreimbursed work expenses since 2018. Check your employer’s policy and local tax rules to be sure.A reasonable generic answer, including US tax rules nobody asked about. Your handbook has the actual rule.
[03]
Step 1: Load and chunk the documents
The corpus here is a fictional company handbook: five short Markdown files (expenses, remote work, equipment, travel, time off), each starting with a # Title line. For example, expenses.md:
# Expenses
Submit expenses in the Ledgerly app within 30 days of purchase. Attach a photo of the receipt for anything over 25 EUR.

Meals with clients are reimbursed up to 60 EUR per person. Alcohol is not reimbursed.

Coworking day passes are reimbursed up to 25 EUR per day, at most 4 days per month, when you work away from home for a full day.
One chunk per paragraph, with the title prepended so each chunk makes sense on its own, and an id like expenses#3 for citations:
from pathlib import Path
import numpy as np
from openai import OpenAI

client = OpenAI()

def load_chunks(folder):
    chunks = []
    for path in sorted(Path(folder).glob("*.md")):
        first_line, body = path.read_text().split("\n", 1)   # first line is "# Title"
        title = first_line.lstrip("# ")
        paragraphs = [p.strip() for p in body.split("\n\n") if p.strip()]
        for i, p in enumerate(paragraphs, start=1):
            chunks.append({"id": f"{path.stem}#{i}", "text": f"{title}: {p}"})
    return chunks
The five files give 11 chunks. Real documents need more care (headings, tables, long sections), but the rule is the same: a chunk should answer one kind of question and carry enough context to stand alone.
[04]
Step 2: Embed and retrieve
def embed(texts):
    r = client.embeddings.create(model="text-embedding-3-small", input=texts)
    v = np.array([d.embedding for d in r.data])
    return v / np.linalg.norm(v, axis=1, keepdims=True)   # unit vectors: dot product = cosine similarity

def retrieve(question, chunks, vectors, k=3):
    scores = vectors @ embed([question])[0]
    best = np.argsort(-scores)[:k]
    return [(chunks[i], float(scores[i])) for i in best]
Embed the chunks once and keep the vectors. For a few hundred chunks, a NumPy array in memory is fast enough; a vector database earns its place at much larger sizes or when documents change constantly. Always use the same embedding model for chunks and questions.
[05]
Step 3: Answer from the passages, with citations
SYSTEM = """Answer questions about the company handbook using only the passages provided.
- Cite the passage id in square brackets after each claim, like [travel#2].
- If the passages don't contain the answer, reply exactly: "The handbook doesn't cover this." Then suggest who to ask.
- Keep answers to 1-3 sentences."""

def ask(question, chunks, vectors):
    hits = retrieve(question, chunks, vectors)
    passages = "\n\n".join(f"[{c['id']}]\n{c['text']}" for c, _ in hits)
    user = f"Passages:\n<passages>\n{passages}\n</passages>\n\nQuestion: {question}"
    r = client.chat.completions.create(model="gpt-5-mini", messages=[
        {"role": "system", "content": SYSTEM}, {"role": "user", "content": user}])
    return hits, r.choices[0].message.content

chunks = load_chunks("handbook")
vectors = embed([c["text"] for c in chunks])
The delimiters and the "only the passages" rule are the grounding pattern. The output for the same question, with the retrieval scores:
Q: Can I expense a coworking space when I work from another city?
  0.61  expenses#3
  0.40  remote-work#1
  0.36  equipment#1
A: Yes — coworking day passes are reimbursed up to 25 EUR per day, up to 4 days per month, when you work away from home for a full day [expenses#3]. Also remember to tell your manager at least one week before you leave if you're working from another city within the EU [remote-work#1].
The right chunk scored highest by a clear margin, the answer uses its numbers, and each claim cites its source.
[06]
Step 4: Handle questions the documents don't cover
Q: How many weeks of parental leave do I get?
  0.39  time-off#1
  0.35  remote-work#1
  0.34  time-off#2
A: The handbook doesn't cover this. Ask HR or your manager for parental leave details.
Retrieval still returned three chunks, because top-k always returns k results. Notice the scores: all low and close together, unlike the clear winner above. The prompt's exit rule did the work here. You can add a second guard in code, such as flagging answers when the best score is below a threshold you pick by looking at real questions; similarity scores vary by embedding model, so don't copy a threshold from elsewhere.
[07]
When to use simple RAG (and when not)
Use it when answers live in documents the model hasn't seen: internal policies, product docs, support articles, notes. For a few pages, you may not need retrieval at all: paste everything into the prompt. RAG pays off once documents exceed what you want to send on every request.
Move beyond this version when retrieval misses, for example because questions use different words than the documents (add keyword search alongside embeddings), answers need several documents (retrieve more, or let an agent search repeatedly, see agentic RAG), or documents come from untrusted sources (see RAG security).
[08]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Embedding whole documents | One vector blurs many topics | Chunk by paragraph or section |
Chunks without context | "Up to 25 EUR" means nothing alone | Prepend the document title or heading |
No "not covered" rule | Top-k always returns something; the model stretches it | Give an exact abstain sentence |
Different embedding models for chunks and questions | The vectors aren't comparable | Use one model for both |
Only checking answers | A right answer can cite the wrong chunk | Spot-check that cited chunks support the claim |
Copying a score threshold | Scores differ by model and corpus | Pick thresholds from your own questions |
[09]
Frequently asked questions
Do I need a vector database for RAG?
Not for a small corpus. A few thousand chunks fit in memory and a dot product is fast. Use a vector database when you have many documents, frequent updates, filtering needs or multiple users.
What chunk size should I use?
Start with natural units: paragraphs or sections of a few hundred words. Too large and one chunk covers several topics; too small and chunks lose the context that makes them meaningful. Test with real questions and adjust.
How many chunks should I retrieve?
Start with 3 to 5. Retrieve more if answers often need several passages; fewer if irrelevant passages confuse the answer. Look at what was retrieved for questions that went wrong.
Does RAG stop hallucinations?
It reduces them when the answer is in the retrieved text and the prompt requires using only that text. The model can still misread a passage or cite the wrong one. See LLM hallucinations.
Is RAG better than fine-tuning?
They solve different problems. RAG gives the model facts at question time and is easy to update; fine-tuning changes behavior and style. For "answer from our documents", start with RAG.
[10]
Next steps
The prompt side of RAG: grounding LLM answers.
Let an agent search for itself: agentic RAG in Python.
Protect the pipeline: RAG security.
Measure answer quality on real questions: beginner eval loops.
Catch unsupported claims: LLM hallucinations.