Contents · 9 sections↓
Multimodal prompting means sending a model an image together with text instructions, and getting back an answer about the image. This guide is for developers and practitioners who want usable data from photos, screenshots, receipts or whiteboards, not a friendly description. It shows how to send an image, how to write the instruction, a real receipt example with model output, and how to check the result in code.
How do you prompt an LLM with an image?
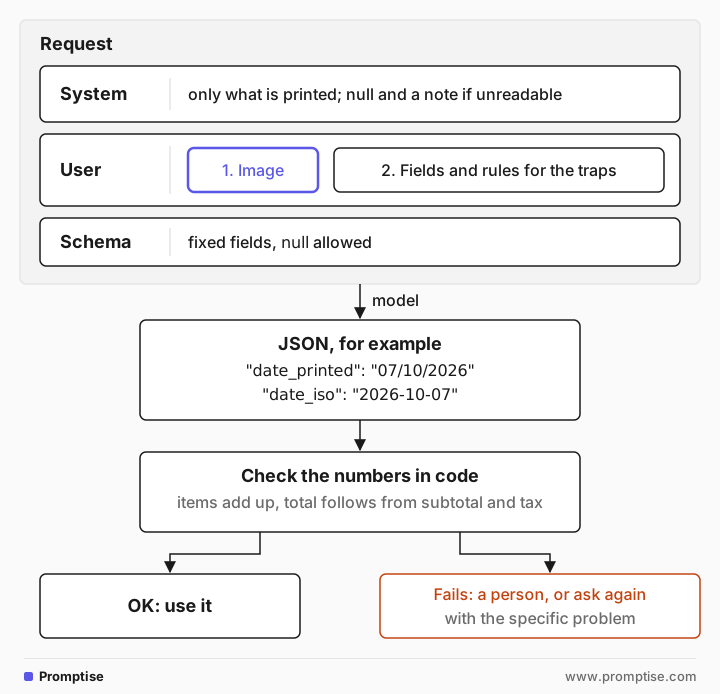
Send the image as a content block in the user message, ideally before your instruction. In the instruction, name the exact fields you want, define the rules for tricky cases (which total, which date format, what to do when something is unreadable), and enforce a JSON schema. Then check what you can in code, such as whether the line items add up.
Key takeaways:
Ask for fields, not a description. "What's on this receipt?" gets prose your code can't use.
Write rules for the traps: several totals, ambiguous dates, tips, tax included or added.
Give the model a way out: null plus a note when something is unreadable.
Check the arithmetic in code. Numbers on a document usually have to agree with each other.
Know the limits: small or rotated text, counting and exact positions are weak spots.
[02]
How image input works
Vision models turn the image into tokens alongside your text, so the image costs tokens and counts toward the context window. Most APIs accept an image as a URL, a base64 data URL, or an uploaded file ID, as a content part in the user message.
Order can matter. Anthropic's vision docs say Claude works best when images come before text, although other orders still work. Putting the image first is a safe default for any model. With several images, label them ("Image 1:", "Image 2:") so your instruction can refer to each one.
Resolution matters too. OpenAI's images and vision guide offers a detail setting that controls how the image is preprocessed. For OCR, small objects and other fine detail, it recommends "detail": "original" where the model supports it. The same guide lists limitations worth knowing before you build: small, rotated or non-Latin text can be misread, counts are approximate, and precise spatial reasoning is weak.
[03]
The vague prompt
The image is a photo of a café receipt (synthetic, made for this guide): three items, a subtotal of 21.30, "incl. VAT 8.1% 1.60", "TOTAL CHF 21.30", then a suggested tip of 3.20 and "Total with tip: 24.50". The date is printed as 07/10/2026.
The prompt: "What's on this receipt?" The output, trimmed:
Summary of the receipt:
- Business: CAFE LINDE
- Address: Lindenhofstrasse 4, 8001 Zurich
- Date: 07/10/2026
…
Totals:
- Subtotal: 21.30 CHF
- Included VAT 8.1%: 1.60 CHF
- TOTAL: 21.30 CHF
…
Suggested tip and final:
- Suggested tip 15%: 3.20 CHF
- Total with tip: 24.50 CHF
The model read every line correctly. The problem is the shape: it's prose, it contains two different "totals", and it leaves the date as printed, which could be July 10 or October 7. Code that parses this has to guess, and so would a person skimming it.
[04]
The extraction prompt
A system prompt sets the behavior once:
You extract data from photos of receipts.
Use only what is printed. Never guess a value you cannot read; use null and explain in notes.
The user message puts the image first, then the instruction:
Extract the receipt in the image.
Rules:
- total: the amount labeled TOTAL or Amount due. Ignore suggested tips and "total with tip" lines.
- date_printed: copy the date exactly as printed.
- date_iso: YYYY-MM-DD only if the format is unambiguous for the receipt's country; otherwise null and say why in notes.
- tax_included: true if the receipt says tax is included in the prices.
- Amounts are numbers without currency symbols.
A JSON schema, enforced with structured outputs, fixes the fields: merchant, country, both dates, currency, items, subtotal, tax, tax_included, total and notes, with null allowed where a value may be missing. In Python with the OpenAI SDK, the message looks like this:
messages = [
    {"role": "system", "content": SYSTEM},
    {"role": "user", "content": [
        {"type": "image_url", "image_url": {"url": "data:image/png;base64," + image_b64}},
        {"type": "text", "text": TASK},
    ]},
]
response = client.chat.completions.create(
    model="gpt-5-mini", messages=messages,
    response_format={"type": "json_schema", "json_schema": RECEIPT_SCHEMA},
)
The output:
{
  "merchant": "CAFE LINDE",
  "country": "Switzerland",
  "date_printed": "07/10/2026",
  "date_iso": "2026-10-07",
  "currency": "CHF",
  "items": [
    {"description": "Cappuccino", "quantity": 2, "amount": 11.0},
    {"description": "Croissant", "quantity": 1, "amount": 3.8},
    {"description": "Orange juice", "quantity": 1, "amount": 6.5}
  ],
  "subtotal": 21.3,
  "tax": 1.6,
  "tax_included": true,
  "total": 21.3,
  "notes": "All values taken exactly from printed receipt. Date interpreted as DD/MM/YYYY (Switzerland uses day/month/year), so ISO date set to 2026-10-07. Suggested tip and 'Total with tip' ignored per instructions."
}
The total ignores the tip line, VAT is marked as included, and the date decision is explained. Keeping date_printed next to date_iso means a person can still check the interpretation. If your receipts come from many countries, you may prefer the stricter rule: never convert DD/MM versus MM/DD dates, always return null and let a person decide.
[05]
Check the numbers in code
Receipts, invoices and forms have built-in checks: the items add up to the subtotal, and the total follows from subtotal and tax.
def check(r):
    problems = []
    items_sum = round(sum(i["amount"] for i in r["items"]), 2)
    if r["subtotal"] is not None and items_sum != r["subtotal"]:
        problems.append(f"items add up to {items_sum}, subtotal says {r['subtotal']}")
    expected = r["subtotal"] if r["tax_included"] else round((r["subtotal"] or 0) + (r["tax"] or 0), 2)
    if r["total"] != expected:
        problems.append(f"total {r['total']} != expected {expected}")
return problems or ["OK: line items, subtotal and total agree"]OK: line items, subtotal and total agreeWhen a check fails, send the image to a person, or ask the model again with the specific problem ("the items add up to 20.30, but you returned a subtotal of 21.30; reread the amounts").
[06]
When to use image prompting (and when not)
Good fits: receipts and invoices, screenshots of dashboards or error messages, whiteboard photos turned into action items, slides, product photos for catalog fields. Use a dedicated OCR or document-parsing service when you need character-perfect text at high volume, exact coordinates, or reliable counts of many small objects. Don't use general vision models for medical diagnosis or to identify people.
[07]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
"What's in this image?" for data | You get prose, not fields | Name fields and enforce a schema |
No rule for multiple totals | The model may pick the tip line | Say which label counts and what to ignore |
Converting ambiguous dates silently | 07/10 can mean two dates | Keep the printed value; convert only when unambiguous |
No "unreadable" option | The model guesses a plausible number | null plus a note |
Low resolution or heavy compression | Small text becomes unreadable | Send a clear, upright, cropped image |
Trusting extracted numbers | Misreads happen | Check sums and totals in code |
[08]
Frequently asked questions
Should the image go before or after the text?
Before is a safe default. Anthropic's docs recommend image-then-text for Claude, and other models handle it well too. With several images, label each one so the instruction can refer to it.
Can vision models read handwriting?
Often, if it's clear. Accuracy drops with messy handwriting, small text and rotation. Ask for null when a value is unreadable, and review those cases by hand.
How do I get JSON back from an image prompt?
The same way as with text: describe the fields and use your provider's structured output or JSON schema feature. Validate the result, then run domain checks such as totals.
How much does an image cost?
Images are converted to tokens, and the count depends on the image size, the model and the detail setting. Check your provider's vision docs, and downscale or crop large images when you don't need the detail.
Can I send several pages or images at once?
Yes. Most APIs accept multiple images in one message. Put them in reading order and label them, and ask for one result per page if the pages are independent.
[09]
Next steps
Get reliable JSON back: structured outputs.
Write instructions the model can't misread: clear prompts.
Flag uncertain fields: confidence fields.
Test the extractor on many images: beginner eval loops.
The other direction, text to image: consistent AI image generation.