Contents · 10 sections↓
- 01How do you keep AI-generated images consistent?
- 02Does JSON prompting work for image generation?
- 03Step 1: Write the spec
- 04Step 2: Render it into a prompt
- 05Step 3: Change the scene, text only
- 06Step 4: Use the first image as a reference
- 07Tips that hold across image models
- 08Common mistakes
- 09Frequently asked questions
- 10Next steps
Consistent AI image generation means getting the same character, product or style across many images, while the scene changes. This guide is for anyone producing a series of images: a mascot across a website, a character through a story, a product in several settings. It shows how to keep a JSON spec of what must not change, render it into a clear text prompt, and use your first image as a reference, with a real example from an image model.
How do you keep AI-generated images consistent?
Write down what must stay the same (face, hair, outfit, palette, art style) once, in a spec, and reuse it word for word in every prompt. Change only the scene fields between images. Then give the model your best earlier image as a reference image and tell it what to keep identical. Text alone gets you a family resemblance; a reference image gets you much closer to the same character.
Key takeaways:
JSON is for you, not the model. Image models read text. A JSON spec keeps your invariants stored, versioned and reusable.
Render the spec into a labeled prompt: Style, Character, Scene, Constraints. Official guidance favors skimmable, consistent prompt structure.
Change one thing at a time and restate the invariants on every request.
Use a reference image for identity. It is the biggest lever for consistency.
Expect trade-offs: a reference keeps the face but can pull the pose toward the original.
[02]
Does JSON prompting work for image generation?
Partly, and not for the reason people often give. OpenAI's image prompting guide says minimal prompts, paragraphs, JSON-like structures, instruction-style and tag-based prompts "can all work well" as long as intent and constraints are clear, and recommends a skimmable template for production. The format isn't magic. What helps is what JSON forces you to do: split the description into fixed fields, keep the identity text identical between images, and change only the fields you mean to change.
So this guide keeps the spec in JSON and sends the model a labeled text version of it. You can send the JSON directly if you prefer; the discipline is what matters.
[03]
Step 1: Write the spec
SPEC = {
    "use": "illustration for a cafe's website, no text in the image",
    "style": "flat vector illustration, clean outlines, soft grain texture, warm palette of coffee brown, cream and teal",
    "character": {
        "name": "Lina, a barista",
        "face": "round face, dark brown almond eyes, small beauty mark under the left eye, light freckles across the nose",
        "hair": "short black bob with blunt bangs",
        "outfit": "teal apron over a cream long-sleeved shirt, sleeves rolled to the elbow",
        "props": "small silver hoop earrings",
    },
    "shot": {
        "scene": "behind the cafe counter in the morning, espresso machine behind her",
        "action": "pouring latte art into a white cup",
        "framing": "waist-up, three-quarter view, eye level",
    },
    "constraints": ["no text, letters or logos", "no watermark", "one person only"],
}
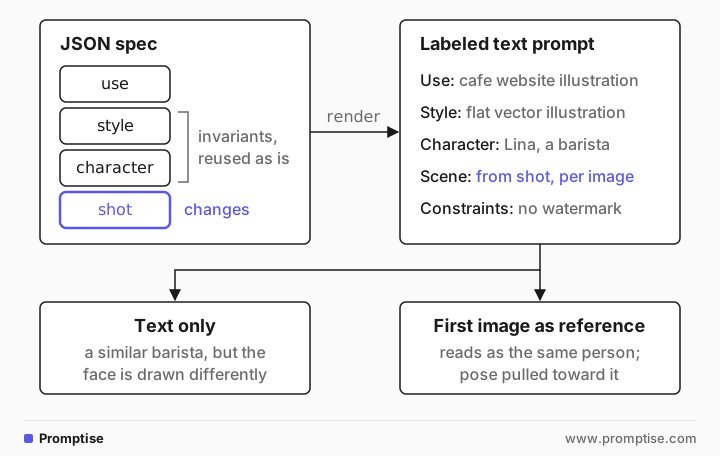
style and character are the invariants. shot is the only part you change between images. Describe the character with a few distinctive, visible features rather than many vague ones; "small beauty mark under the left eye" is something you can check in the result.
[04]
Step 2: Render it into a prompt
def render(spec):
    c, s = spec["character"], spec["shot"]
    return "\n".join([
        f"Use: {spec['use']}.",
        f"Style: {spec['style']}.",
        f"Character: {c['name']}. Face: {c['face']}. Hair: {c['hair']}. Outfit: {c['outfit']}. Accessories: {c['props']}.",
        f"Scene: {s['scene']}. Action: {s['action']}. Framing: {s['framing']}.",
        "Constraints: " + "; ".join(spec["constraints"]) + ".",
    ])

result = client.images.generate(model="gpt-image-2", prompt=render(SPEC), size="1024x1024", quality="low")
The order (use, style, subject, scene, constraints) follows the cookbook's advice to write prompts in a consistent order and to state the intended use. Exclusions go in the prompt as plain constraints ("no watermark"); there is no separate negative-prompt parameter in this API.
What came back. The first image showed Lina behind the counter pouring a leaf pattern into a white cup, with an espresso machine behind her: black bob with blunt bangs, teal apron, cream shirt, silver hoops, freckles. Two details drifted from the spec even here: the look was a textured, painterly illustration rather than clean flat vector, and the beauty mark was hard to place relative to "left". Treat the first image as a draft of the character; if it's not right, fix the spec and regenerate before making a series.
[05]
Step 3: Change the scene, text only
Keep style and character, replace shot:
shot2 = {"scene": "at a small cafe table by a rainy window in the afternoon",
         "action": "writing the day's specials on a small chalkboard",
         "framing": "waist-up, side view facing right, eye level"}
result = client.images.generate(model="gpt-image-2", prompt=render({**SPEC, "shot": shot2}),
                                size="1024x1024", quality="low")
What came back. A recognizable relative: same haircut, apron, shirt, earrings and freckles, in a side view at a rainy window with a blank chalkboard. But the face was drawn differently (different eye shape and proportions), and the colors were darker and more muted. A reader would see "a similar barista", not clearly the same one. That's the normal limit of text-only consistency: the description constrains the category of person, not the exact face.
[06]
Step 4: Use the first image as a reference
Pass the anchor image to the edit endpoint, label it, and list what must stay identical:
prompt = ("Image 1 shows Lina, our recurring character. Create a new image of the same character.\n"
          + render({**SPEC, "shot": shot2})
          + "\nKeep identical to Image 1: face, beauty mark, freckles, hairstyle, outfit, earrings, art style and palette."
          " Change only the scene, action and framing.")
with open("lina_anchor.png", "rb") as ref:
    result = client.images.edit(model="gpt-image-2", image=[ref], prompt=prompt,
                                size="1024x1024", quality="low")
What came back. This one read as the same person: the eye and eyeliner shape, the downcast smile, the bangs and the warm color grading matched the first image closely. The trade-off: the requested "side view facing right" became closer to a three-quarter view, nearer the anchor's pose. If the pose matters, say so more strongly, or generate the pose first and fix identity in a second edit.
The pattern of naming each input image and listing what to preserve comes from the OpenAI cookbook, whose children's book example builds a "character anchor" image and reuses it for each page. Reference images add input tokens, so they cost more than text-only generation. Other tools work similarly: Google's Gemini image models accept reference images and recommend multi-turn conversation for iterating on an image.
[07]
Tips that hold across image models
Start at low quality while you tune the spec, then raise quality for final assets. OpenAI's guide recommends this to save time and cost.
Restate the preserve list on every request, even in a multi-turn edit. Drift builds up when you rely on "same as before".
One change per iteration ("make the lighting warmer"), so you know what caused a difference.
Pick a reference you're happy with. Every later image inherits its flaws.
Put literal text in quotes if the image must contain words, and check the spelling yourself.
[08]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Rewriting the character description each time | Small wording changes become visible changes | Keep it in a spec and reuse it verbatim |
Expecting JSON syntax to improve results | The model reads text; format alone isn't the lever | Use JSON to organize, send clear labeled text |
Text-only prompts for a recurring face | Descriptions fix the type of person, not the face | Use a reference image |
Many vague traits | Hard to follow and hard to check | A few distinctive, visible features |
Changing scene, style and pose at once | You can't tell what caused drift | One change per image |
Not reviewing the anchor | Flaws repeat across the series | Fix the spec first, then generate the set |
[09]
Frequently asked questions
What is JSON prompting for images?
Writing an image prompt as structured fields (style, subject, scene, constraints) instead of a paragraph. Its main benefit is consistency in your own process: fixed fields you reuse and vary deliberately. Official guidance says many prompt formats work if they're clear.
Can I use a seed for consistency?
Some image tools expose a seed, which makes a repeat of the same prompt reproducible. It doesn't keep a character the same across different prompts. OpenAI's image API has no seed parameter; use a reference image instead.
How many reference images should I use?
Start with one good image of the character. Add more (for example a face close-up and a full-body view) when one view isn't enough, and label each one so the prompt can say what to take from which.
Do negative prompts work?
Models without a negative-prompt parameter follow exclusions written in the prompt, such as "no text, no watermark". Keep the list short and specific.
Why does my character still change slightly?
Generation is not deterministic, and every new pose or scene asks the model to redraw the face. Use a reference, keep the invariants identical, and expect to pick the best of a few attempts for important images.
[10]
Next steps
The other direction, images as input: multimodal prompting.
Structured fields for text output: structured outputs.
Clear instructions in general: ask, role, constraints, format.
Improve a prompt step by step: iterative prompt refinement.