Contents · 6 sections↓
A prompt that feeds another program is code. It has inputs, an expected output type and edge cases, and like code it can be underspecified. The difference is the "compiler": an LLM fills the gaps with the most plausible guess, and guesses vary from run to run. This essay, part of the Mental Models learning path, explains how to write prompts as specifications, enforce their output shape, and test them like code, with a real example where a vague extraction prompt returns prose and a specified one returns data plus the assumptions it made.
How do you treat prompts as code?
Write the prompt as a specification: the input, the output type, and a rule for every ambiguity you can foresee. Enforce the output shape with a schema the API guarantees, and validate the meaning in code, because a schema can only promise the shape. Keep prompts in version control with a set of test cases, and rerun the cases on every change to the prompt or the model. The model works like a compiler that fills missing parts of the spec with the most likely guess.
Key takeaways:
Every unstated decision becomes a sample. Ambiguity in the prompt shows up as variance in the output.
Schemas fix shape, not meaning. Constrained decoding guarantees valid JSON; it can't guarantee the right date.
Make the model report its assumptions, so the ambiguous cases surface instead of being silently decided.
Test prompts like functions: fixed inputs, expected outputs, run on every change.
[02]
Why the compiler analogy works
A compiler turns a specification into behavior and rejects what it can't resolve. An LLM never rejects; it predicts the most likely continuation of whatever it was given. If the prompt doesn't say which date format, which time zone, or what "next Thursday" means, the model picks a plausible answer, and sampling means it may pick differently next time. That is the probabilistic part.
Two developments make the analogy practical. Structured outputs use constrained decoding: at each step, tokens that would break the supplied JSON Schema are excluded, so the response is guaranteed to parse and match the schema (OpenAI structured outputs guide; other providers offer similar modes). And prompt compilation treats the prompt itself as a build artifact. DSPy (Khattab et al., ICLR 2024) has you declare modules with input and output signatures plus a metric, then "compiles" the pipeline by searching for prompts and few-shot examples that maximize the metric on your data. You don't need DSPy to use the idea: a spec, a metric and test cases are what turn a prompt into maintainable code.
[03]
Example: extracting a meeting time
The email:
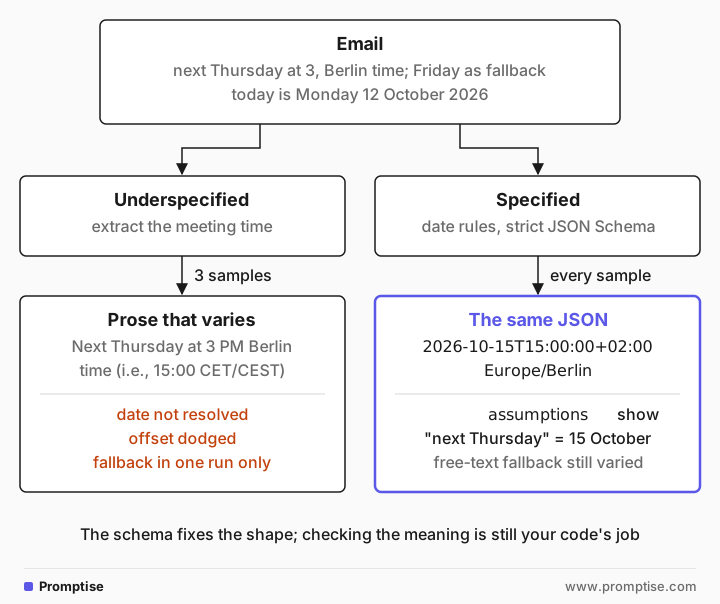
Hi both, can we move the vendor review to next Thursday at 3? Berlin time, since Ana is joining from there. If that doesn't work, Friday morning is fine too. Today is Monday 12 October 2026. - TomAn underspecified prompt:
Extract the meeting time from this email.Three samples:
Next Thursday at 3 PM Berlin time (i.e., 15:00 CET/CEST).
Next Thursday at 3 PM Berlin time (i.e., 15:00 CET/CEST).
Next Thursday at 3 PM Berlin time (or Friday morning as backup).
Readable, but no program can use it. The date isn't resolved, "CET/CEST" dodges the offset, and the fallback appears in one run only.
A specified prompt, with a strict JSON Schema passed as the response format (fields: proposed_start as ISO 8601 with offset, timezone as an IANA name, fallback as string or null, assumptions as a list):
Extract the proposed meeting slot from the email. Resolve relative dates against the date stated in the email. If the hour is ambiguous between AM and PM, pick the business-hours reading and record it in assumptions.{"proposed_start":"2026-10-15T15:00:00+02:00","timezone":"Europe/Berlin","fallback":"Friday morning (alternative)","assumptions":["'next Thursday' relative to 'Today is Monday 12 October 2026' means Thursday 15 October 2026","'3' interpreted as 3:00 PM (business-hours reading) in Berlin timezone","'Friday morning' left as an imprecise fallback, not converted to a specific datetime"]}Every sample parsed and agreed on 2026-10-15T15:00:00+02:00. The assumptions field earned its place: it exposed that "next Thursday" was read as 15 October, when some readers would mean the 22nd. That is a spec bug only a human can resolve, and now it is visible. The free-text fallback field still varied between runs ("Friday morning (alternative)" and "Friday morning (2026-10-16)"), which is the cue to give it a type too. Results vary by model.
[04]
What it changes in practice
Write the spec before the prose. List the inputs, the output schema and the ambiguity rules: relative dates, missing values, conflicting instructions. Each rule you write is one less thing the model decides at random.
Enforce shape with the API, check meaning in code. Use structured outputs where available. Then validate what the schema can't express: dates in the future, totals that add up, IDs that exist. Fail loudly, like a type error.
Version and test prompts. Keep a few dozen real inputs with expected outputs, including edge cases, and run them on every prompt edit and model upgrade. If you use Promptise Foundry, its prompt testing utilities provide a PromptTestCase with schema and content assertions; any test runner works for the same job.
[05]
Frequently asked questions
What is a probabilistic compiler?
It is a mental model for LLMs: like a compiler, the model turns a specification (your prompt) into output, but it fills gaps with the most likely guess instead of raising an error, and sampling means the guess can change between runs. The fix is the same as for code: tighter specs and tests.
Do structured outputs guarantee correct answers?
No. They guarantee the response matches your JSON Schema: required fields present, types right, enums respected. A well-formed object can still hold a wrong date or a made-up value. Validate content separately.
What is DSPy?
DSPy is a framework from Stanford in which you declare LLM pipeline steps as modules with typed signatures and a metric, and an optimizer "compiles" them into effective prompts and examples. It applies software-engineering ideas, such as modules and optimization against tests, to prompting.
How many test cases does a prompt need?
Enough to cover the cases that matter: typical inputs, each ambiguity rule, and every bug you've fixed. For many production prompts that is 20 to 100 cases. Add each failure you find in production as a new case.
[06]
Next steps
Structured outputs: reliable JSON: schemas, validation and Pydantic.
How to test LLM prompts in Python: build a regression suite.
How to write clear prompts: asks, constraints and format.
Prompts as interfaces, not commands: the companion essay on prompt design.
Mental Models: How to Think with LLMs: the full learning path.