Contents · 11 sections↓
- 01How do you get an LLM to plan API calls safely?
- 02How plan-then-execute works
- 03When to plan up front (and when not to)
- 04Step 1: Describe the tools and the plan rules
- 05Step 2: Get a plan
- 06Step 3: Validate the plan in code
- 07Step 4: Execute with references and safe conditions
- 08Running plans in production
- 09Common mistakes
- 10Frequently asked questions
- 11Next steps
LLM tool call planning means asking the model for the whole sequence of API calls up front, as structured data, so your code can check it before anything runs. For multi-step requests, a plan lets you catch unknown tools, invented arguments and unguarded writes before they touch real systems. This guide shows the plan format, the prompt, a validator and an executor in Python, with a real plan where validation caught an invented value. It's for developers wiring LLMs to their own APIs.
How do you get an LLM to plan API calls safely?
Give the model the tool list and ask for a JSON plan: steps with a tool name, arguments that come from the request or from earlier steps (as references like $s1.customer_id), and a checkable condition on every step that changes data. Validate the plan in code (known tools, exact arguments, allowed values, references to earlier steps, guards on writes) and only then execute it, resolving references from real results.
Key takeaways:
Plan as data, not prose. A JSON plan can be validated; a paragraph can't.
No invented values. Every argument comes from the request or a previous step.
Writes need conditions code can evaluate, not judgment the model applies later.
Put allowed values in the tool description. Validation catches invented values; good descriptions prevent them.
Never
eval()conditions. Parse a small set of allowed forms.
[02]
How plan-then-execute works
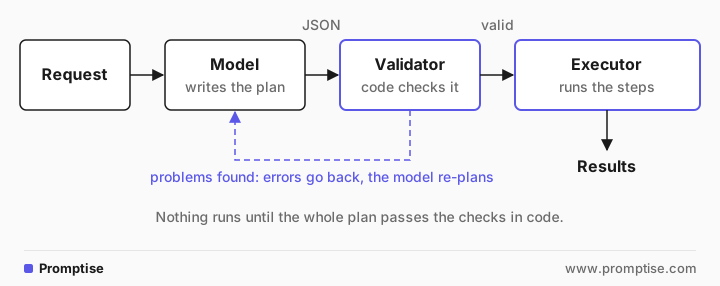
In a ReAct-style loop the model picks one call, sees the result, then picks the next. Planning ahead separates the two. ReWOO (Xu et al., 2023) planned all tool calls with placeholders for future results and reported 5x token efficiency on HotpotQA compared with interleaved reasoning. LLMCompiler (Kim et al., ICML 2024) builds a dependency graph of calls and runs independent ones in parallel, reporting up to 3.7x lower latency than ReAct.
For this guide, the main benefit is control: you see every call, with its arguments and guards, before the first one runs.
[03]
When to plan up front (and when not to)
Plan up front | Decide step by step (ReAct) |
|---|---|
The steps are predictable from the request | The next step depends on what you find |
Some steps change data (refunds, emails, updates) | Exploration: search, browse, debug |
You need approval or audit before execution | Results are cheap and reversible |
Several calls can run in parallel | Few calls, latency is not an issue |
Many systems combine them: plan, execute, and re-plan if a step fails or returns something unexpected. For a full agent built that way, see plan-and-execute agents in Python.
[04]
Step 1: Describe the tools and the plan rules
TOOLS = {
    "get_order":    {"args": {"order_id": "str"}, "returns": "{order_id, customer_id, total_cents, delivered_on}", "writes": False},
    "get_customer": {"args": {"customer_id": "str"}, "returns": "{customer_id, email, name}", "writes": False},
    "issue_refund": {"args": {"order_id": "str", "amount_cents": "int", "reason": "str"}, "returns": "{refund_id}", "writes": True},
    "send_email":   {"args": {"to": "str", "template": "str", "variables": "object"}, "returns": "{message_id}", "writes": True},
}

PLAN_PROMPT = f"""You plan API calls. You don't execute them.
Tools:
{TOOL_DOC}

Return a JSON plan. Rules:
- Use only the tools listed. If the request needs something no tool can do, put it in "unsupported".
- Never invent values. Take every argument from the request or from an earlier step, written as "$s1.field".
- A step that changes data must have a "condition" that code can check, written as an expression over earlier
  step results, for example "days_since($s1.delivered_on) < 30". Use "true" only if the request has no condition.
- Read steps first, then writes. At most 6 steps.
Today is 2026-10-18."""
TOOL_DOC renders the dictionary as one line per tool, marking writes with [changes data]. Request the plan with a JSON schema (structured output), so every step has id, tool, args and condition. The "unsupported" list gives the model a legitimate place to put what it can't do, instead of inventing a tool.
[05]
Step 2: Get a plan
The request:
Order A-1043 arrived broken. If it was delivered less than 30 days ago, refund it in full,
email the customer a confirmation, and add a 10% coupon to their account.
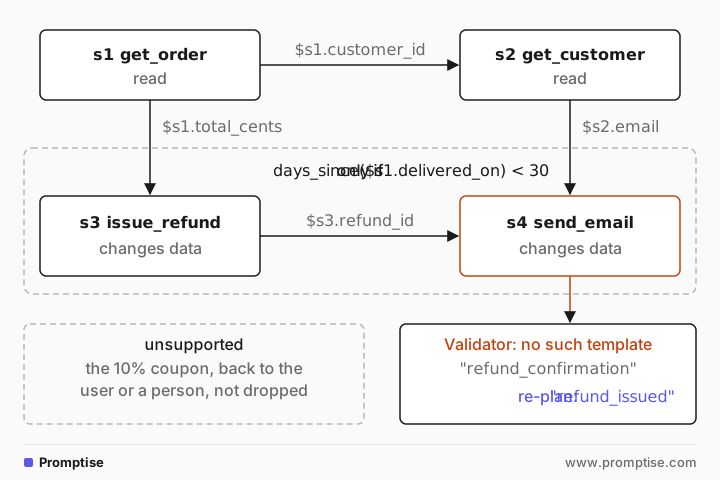
The model's plan (condensed to one line per step):
s1 get_order      order_id="A-1043"                                                  condition: ""
s2 get_customer   customer_id="$s1.customer_id"                                      condition: ""
s3 issue_refund   order_id="$s1.order_id", amount_cents="$s1.total_cents",
                  reason="Order arrived broken"                                      condition: days_since($s1.delivered_on) < 30
s4 send_email     to="$s2.email", template="refund_confirmation",
                  variables={order_id, refund_id: $s3.refund_id, amount_cents, customer_name}
                                                                                     condition: days_since($s1.delivered_on) < 30
unsupported: "There is no available tool to add a 10% coupon to the customer's account. …"
Most of this is right. Reads come first, the refund amount comes from the order instead of being guessed, the 30-day rule became a checkable condition, and the coupon went to unsupported instead of a made-up add_coupon call. One value was invented: the email template refund_confirmation. The request never named a template, and no tool description listed any.
[06]
Step 3: Validate the plan in code
def validate(plan):
    problems, seen = [], set()
    for s in plan["steps"]:
        spec = TOOLS.get(s["tool"])
        if spec is None:
            problems.append(f'{s["id"]}: unknown tool {s["tool"]}'); continue
        names = {a["name"] for a in s["args"]}
        for missing in set(spec["args"]) - names:
            problems.append(f'{s["id"]}: missing argument {missing}')
        for extra in names - set(spec["args"]):
            problems.append(f'{s["id"]}: unknown argument {extra}')
        for a in s["args"]:
            for ref in re.findall(r"\$(s\d+)", a["value"]):
                if ref not in seen:
                    problems.append(f'{s["id"]}: {a["name"]} refers to {ref}, which has not run yet')
        if spec["writes"] and s["condition"].strip() == "true":
            problems.append(f'{s["id"]}: {s["tool"]} changes data but has no condition')
        seen.add(s["id"])
    return problems

TEMPLATES = {"refund_issued", "order_update"}   # what send_email really accepts

def validate_values(plan):
    return [f'{s["id"]}: template "{a["value"]}" does not exist (use one of {sorted(TEMPLATES)})'
            for s in plan["steps"] if s["tool"] == "send_email"
for a in s["args"] if a["name"] == "template" and a["value"] not in TEMPLATES]VALIDATION: ['s4: template "refund_confirmation" does not exist (use one of [\'order_update\', \'refund_issued\'])']Structural checks (tools, argument names, references, guards) catch a broken plan. Value checks catch a plausible plan with a made-up value. Without the second check, this plan would most likely have failed at the email API, after the refund had already gone out.
Send the problems back once and ask for a corrected plan:
The plan failed validation:
s4: template "refund_confirmation" does not exist (use one of ['order_update', 'refund_issued'])
Return a corrected plan.VALIDATION after re-plan: ok
s4 send_email: template = "refund_issued"The better fix is upstream: list the allowed templates in the send_email description, ideally as an enum in the tool schema, so the model can't pick an invalid one in the first place. Keep the validator anyway; descriptions guide, validators enforce.
[07]
Step 4: Execute with references and safe conditions
def resolve(value, results):
    return re.sub(r"\$(s\d+)\.(\w+)", lambda m: str(results[m.group(1)][m.group(2)]), value)

def check_condition(cond, results):
    """Only the condition forms we allow. Anything else is refused, never eval()'d."""
    cond = cond.strip()
    if cond in ("", "true"):
        return True
    m = re.fullmatch(r"days_since\(\$(s\d+)\.(\w+)\)\s*<\s*(\d+)", cond)
    if not m:
        raise ValueError(f"unsupported condition: {cond}")
    days = (TODAY - date.fromisoformat(str(results[m.group(1)][m.group(2)]))).days
    return days < int(m.group(3))

def execute(plan):
    results = {}
    for s in plan["steps"]:
        if not check_condition(s["condition"], results):
            print(f'{s["id"]} {s["tool"]}: skipped, condition false'); continue
        args = {a["name"]: resolve(a["value"], results) for a in s["args"]}
        # (type coercion for ints and JSON objects omitted)
        results[s["id"]] = IMPL[s["tool"]](**args)
        print(f'{s["id"]} {s["tool"]}({args}) -> {results[s["id"]]}')
Run against stub implementations, with the order delivered on 2026-10-02:
s1 get_order({'order_id': 'A-1043'}) -> {'order_id': 'A-1043', 'customer_id': 'C-77', 'total_cents': 4999, 'delivered_on': '2026-10-02'}
s2 get_customer({'customer_id': 'C-77'}) -> {'customer_id': 'C-77', 'email': 'sam@example.com', 'name': 'Sam'}
s3 issue_refund({'order_id': 'A-1043', 'amount_cents': 4999, 'reason': 'Order arrived broken'}) -> {'refund_id': 'R-501'}
s4 send_email({'to': 'sam@example.com', 'template': 'refund_issued', 'variables': {'order_id': 'A-1043', 'refund_id': 'R-501', 'amount_cents': '4999', 'customer_name': 'Sam'}}) -> {'message_id': 'M-9'}
The condition was evaluated by code from real data (16 days since delivery), not by the model's guess. If the order had been delivered 40 days ago, steps 3 and 4 would print skipped, condition false and nothing would change. The coupon from the unsupported list should go back to the user or a person, not be dropped silently.
[08]
Running plans in production
Approval before writes. Show a person the validated plan (it's readable) and execute after approval. See human-in-the-loop approval for agent tool calls.
Idempotency. Pass an idempotency key to write APIs (for example the plan id plus step id), so a retry after a timeout doesn't refund twice.
Re-plan on failure, not on every step. If a step errors or returns something the plan didn't expect (no delivered_on), stop and re-plan from the results so far.
Log the plan and the results. The plan is the audit record of what the model intended.
Permissions still apply. The executor should run with the user's permissions, not an admin key.
[09]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Free-text plans | Can't be validated or executed reliably | JSON schema with steps, args, conditions |
Letting the model fill in amounts, ids and names | Invented values look plausible | Values only from the request or earlier steps; validate allowed values |
Writes without guards | One misread request changes real data | Code-checkable condition on every write, plus approval for risky ones |
eval() on conditions or arguments | Model output becomes code execution | Parse a small, explicit grammar |
No "unsupported" outlet | The model invents a tool to satisfy the request | Give it a field for what it can't do |
Executing all steps after one fails | Later steps act on missing data | Stop, report, re-plan |
[10]
Frequently asked questions
Isn't native function calling enough?
Function calling gives you one structured call at a time, which is ideal for step-by-step loops. Planning asks for the whole sequence first. Use planning when you want to review, approve or parallelize calls before any run; use step-by-step calling when each step depends on the last result.
What's the difference between ReWOO and ReAct?
ReAct interleaves reasoning, one action and its observation, repeatedly. ReWOO plans all actions first, using placeholders for results not yet known, then executes them and has a final step combine the evidence. ReWOO uses fewer tokens; ReAct adapts better when results are surprising.
How do I handle steps that depend on each other?
Use references ($s1.customer_id) and check in the validator that every reference points to an earlier step. Steps without references to each other can run in parallel, as in LLMCompiler.
Should conditions be evaluated by the model?
No. The model writes the condition; your code evaluates it on real results. That keeps business rules such as "less than 30 days" deterministic and auditable.
What if the request is ambiguous?
Add a "questions" field to the plan schema and tell the model to use it instead of guessing. If it's non-empty, ask the user before executing anything.
[11]
Next steps
Full agents that plan, act and verify: plan-and-execute agents in Python.
The step-by-step alternative: ReAct agent from scratch.
Approvals for risky calls: AI agent human in the loop.
Getting reliable JSON: structured outputs.
Writing tool descriptions models use well: too many MCP tools.