Contents · 11 sections↓
- 01How do you improve a prompt step by step?
- 02Round 0: the first prompt
- 03Round 1: add the facts
- 04Round 2: add audience and format
- 05The loop, in short
- 06Diagnose the failure before you change the prompt
- 07Keep every version
- 08When to iterate (and when to write the full prompt up front)
- 09Common mistakes
- 10Frequently asked questions
- 11Next steps
Iterative prompt refinement means improving a prompt in short rounds: run it, see what the output got wrong, change one thing in the prompt, and run it again. This guide is for anyone whose first prompt gave a usable but wrong-shaped result and who wants a method instead of random rewording. It walks through three real rounds on one task, with the model's output each time.
A note on the name: in machine learning, "instruction tuning" means fine-tuning a model on instruction-following examples, as in Finetuned Language Models Are Zero-Shot Learners (Wei et al., 2021). This guide doesn't change the model. It tunes your instructions.
How do you improve a prompt step by step?
Run the prompt and read the output against what you need. Name the biggest gap in one phrase: invented facts, wrong length, wrong audience, wrong format. Change the prompt to fix only that gap, run it again, and compare. Repeat until the output is usable, usually two to four rounds. Save each version so you can go back.
Key takeaways:
The first output is a diagnosis. It shows what the model assumes when you don't say.
Fix the worst problem first. Invented facts before tone, content before format.
One change per round, so you know what worked.
Add facts, audience and format, in roughly that order. These three fix most first drafts.
Keep the versions. A later round can break something an earlier one fixed.
[02]
Round 0: the first prompt
The task: announce a new on-call rotation to the team in Slack.
Write a Slack message announcing our new on-call rotation.The output (256 words), trimmed:
Hi team — quick announcement about a change to our on-call rotation.

What’s changing
- We’re moving to a 2-week on-call rotation starting Monday, May 4.
- Each rotation covers NOC/pager duty Mon 00:00 — Sun 23:59 (UTC).
…
Who’s on-call
- Week A (May 4–May 17): Alice (primary), Bob (secondary)
- Week B (May 18–May 31): Carlos (primary), Dana (secondary)
…
- Primary: respond to pagers within 15 minutes during your rotation …
Well structured and entirely made up: the start date, the two-week cycle, the names, the 15-minute response rule. The model had no facts, so it supplied plausible ones. Diagnosis: missing facts. That's the most dangerous gap, because the output looks finished.
[03]
Round 1: add the facts
Write a Slack message announcing our new on-call rotation.

Facts (use only these):
- Starts Monday, November 3.
- Weekly rotation, Monday 09:00 to Monday 09:00 CET. Six engineers in the backend team.
- Schedule and swaps live in PagerDuty. Swap with a teammate, then tell Priya.
- On-call week pays a flat 300 EUR bonus.
The output (84 words):
Heads-up: we’re starting a new backend on-call rotation.

- Starts: Monday, November 3.
- Cadence: weekly rotation, Monday 09:00 → next Monday 09:00 CET.
- Team: six backend engineers.
- Schedule & swaps: live in PagerDuty. If you need to swap a week, arrange the swap with a teammate in PagerDuty, then notify Priya.
- Pay: each on-call week pays a flat 300 EUR bonus.

If you have questions about PagerDuty access or the process for notifying Priya, reply here and I’ll help coordinate.
Every fact is now real, and the length dropped by two thirds without being asked, because there was less to invent. Diagnosis: no clear ask. The readers need to do something this week, and the message doesn't say what. The closing line is filler.
[04]
Round 2: add audience and format
Write a Slack message announcing our new on-call rotation.

Audience: the six backend engineers. They know what on-call is; they want the dates and what to do.

Facts (use only these):
- Starts Monday, November 3.
- Weekly rotation, Monday 09:00 to Monday 09:00 CET. Six engineers in the backend team.
- Schedule and swaps live in PagerDuty. Swap with a teammate, then tell Priya.
- On-call week pays a flat 300 EUR bonus.

Format: under 80 words. One opening sentence, then 3-4 short bullets, then one action for this week:
"check your weeks in PagerDuty by Friday". No emojis, no headings.
The output (54 words):
New on-call rotation starts Monday, November 3.

- Weekly shifts: Monday 09:00 to Monday 09:00 CET.
- Six backend engineers rotating.
- Schedule and swaps live in PagerDuty; swap with a teammate and notify Priya.
- On-call week pays a flat 300 EUR bonus.

Action this week: check your weeks in PagerDuty by Friday.
Ready to post. Strictly, this round changed two things (audience and format). That's fine when both address the same gap; if the result had gotten worse, you'd split them to find out which one did it.
[05]
The loop, in short
Run the prompt on a real input.
Diagnose the biggest gap in one phrase. Common ones, in the order to fix them: invented or missing facts; wrong audience or purpose; wrong structure or length; wrong tone.
Change one thing that addresses that gap. Add a fact list, name the reader, give a format, show an example.
Rerun and compare with the previous output. Keep the change only if it helped.
Stop when the output is usable as is. Then test the final prompt on a few other inputs; a prompt tuned on one input can fail on the next.
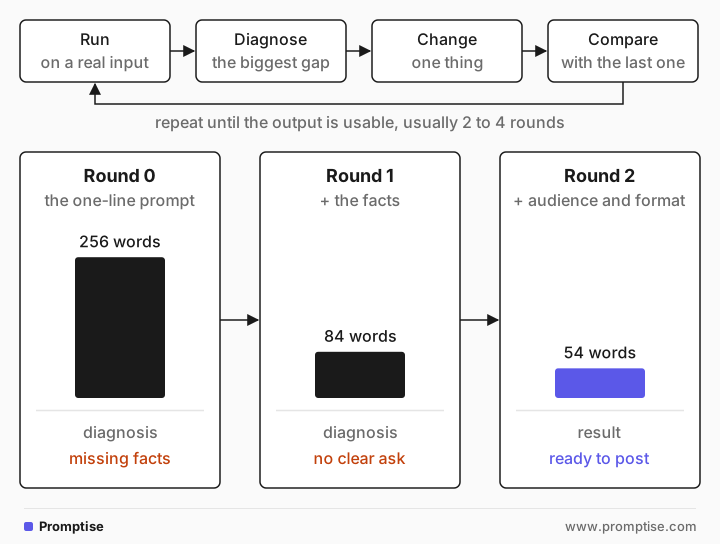
Step 5 is where iteration meets testing. Once the prompt will run on many inputs, switch from eyeballing one output to a small eval loop.
[06]
Diagnose the failure before you change the prompt
Step 2 is the one that decides whether a round helps. Not every bad output means the wording is wrong: some failures belong in the context, some in your spec, some in code. Find the kind first, then fix it in the right place.
Failure | What you see | Where to fix it |
|---|---|---|
Missing information | Plausible but invented names, dates, numbers, steps | Context: supply the facts, or allow "not known" |
Unclear instruction | Right content, wrong audience, length or emphasis | Prompt: name the reader, purpose and limits |
Undefined case | A reasonable answer to a case your rules don't cover | Your spec: decide the rule, then write it down |
Wrong format | Extra text, broken JSON, missing labels | Code: structured outputs and validation |
Beyond the model | Wrong arithmetic, long multi-step logic, exact counting | Code or tools, or a stronger model |
The third row is the one people miss. If two reasonable people could disagree about the right output, the model can't be "wrong": the prompt is incomplete. Decide the rule yourself, add it, and the failure disappears for good.
[07]
Keep every version
Save each round's prompt with a version number and a one-line note on what changed and why. A text file works. If your prompts live in Python, Promptise Foundry's prompt registry versions them and can roll back:
from promptise.prompts import prompt
from promptise.prompts.registry import registry, version

@version("1.1.0")   # round 1: added the fact list
@prompt(model="openai:gpt-5-mini")
async def oncall_announcement(facts: str) -> str:
    """Write a Slack message announcing our new on-call rotation.

Facts (use only these):
{facts}"""

latest = registry.get("oncall_announcement")[08]
When to iterate (and when to write the full prompt up front)
Iterate when you don't yet know what you want, or when you're learning how a model handles a task. Write the full prompt up front when you already know the facts, the reader and the format: round 2 above could have been the first prompt. Most people end up with a personal checklist (facts, reader, purpose, format, example) and need fewer rounds over time. See how to write clear prompts.
There is also a research version of this loop where the model critiques and revises its own output: Self-Refine (Madaan et al., 2023). It's covered in teach models to improve themselves. The manual loop here is simpler and keeps you in control of what "better" means.
[09]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Rewording the whole prompt each round | You can't tell what helped | Change one thing per round |
Fixing tone before facts | Polished text with invented details | Fix facts and content first |
Adding rules for every small issue | Long prompts get partly ignored | Fix the biggest gap; drop rules that didn't help |
Tuning on one input only | The prompt overfits that input | Test the final version on several inputs |
Changing the task mid-loop | Earlier rounds no longer apply | Start a new loop for a new task |
Not saving versions | You can't go back when a change breaks things | Number versions and note each change |
[10]
Frequently asked questions
Is prompt iteration the same as instruction tuning?
No. Instruction tuning fine-tunes a model's weights on instruction-following data. Prompt iteration changes only your prompt, so it's instant and needs no training data.
How many rounds should it take?
Usually two to four for a single task. If you're past five rounds, the problem may be missing information the model can't have, or a task better split into two prompts.
Should I ask the model to improve my prompt?
It can suggest missing details, which is useful early. Judge its suggestions against real outputs, though: a rewritten prompt that reads better isn't necessarily one that works better.
What should I change first?
Whatever makes the output wrong rather than unpolished. Missing facts, a wrong audience and a wrong task come before length, format and tone.
How do I tell an undefined case from a model mistake?
Ask whether a careful new colleague, given only your prompt, would know the right answer. If not, the case is undefined: write the rule. If yes and the model still gets it wrong, it's a model mistake: try an example, a clearer rule or a stronger model.
How do I know a change helped?
Compare the new output with the previous one on the same input, then confirm on a few other inputs. For prompts that run often, use an eval loop with a fixed set of cases.
[11]
Next steps
Turn bad outputs into test cases: a simple eval loop.
Let a model search for better prompts: automatic prompt optimization.
The parts of a clear prompt: ask, role, constraints, format.
Lock in the tone once you have it: style guide prompts.
Let the model revise itself: self-improvement loops.