Contents · 6 sections↓
Using one LLM call to decide which output is better, LLM-as-a-judge, is now a standard way to evaluate prompts, agents and RAG answers. It is also easy to get wrong: a single judge has measurable biases, and its verdict can flip when you swap the order of the answers. This essay, part of the Mental Models learning path, explains where judge bias comes from, what a "jury" of checks looks like, and how to set one up, with a real example of a judge contradicting itself.
LLM as a judge vs a jury: what's the difference?
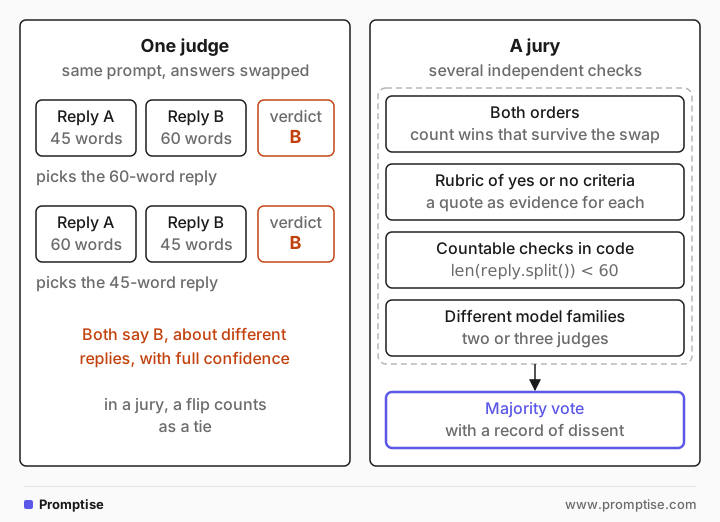
An LLM judge is one model, one prompt, one verdict. A jury spreads the decision across several independent checks: both answer orders, explicit yes-or-no criteria with quoted evidence, and ideally several models from different families, aggregated by a vote. Research shows a single strong judge can agree with human raters about as often as humans agree with each other, but it is biased toward the first or longer answer and toward its own outputs. A jury averages out those biases.
Key takeaways:
Swap the order every time and count only wins that survive the swap.
Replace "which is better?" with a rubric of yes/no criteria, each backed by a quote.
Use different model families on the panel; same-model judges share the same blind spots.
Anything countable belongs in code, not in the judge prompt.
[02]
Why a single judge is unreliable
Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena (Zheng et al., 2023) found that strong judges such as GPT-4 reached over 80% agreement with human preferences, about the level humans reach with each other. The same paper documented three biases: position bias (favoring an answer because of where it appears), verbosity bias (favoring longer answers), and self-enhancement bias (favoring answers written by the judge's own model). It recommended swapping positions and counting a win only when it holds both ways.
The biases follow from how the judge works. A verdict is a sampled continuation like any other output, shaped by the order of the text and by preferences learned in post-training. Replacing Judges with Juries (Verga et al., 2024) tested a Panel of LLM evaluators (PoLL) built from smaller models of disjoint families. The panel outperformed a single large judge across three judge settings and six datasets, showed less intra-model bias, and was over seven times cheaper.
[03]
Example: the same judge, both orders
Two support replies to "Can I change the delivery address after my order has shipped?" One is 45 words, the other 60. Both are reasonable. The judge prompt:
You are judging two support replies.
[question]
Reply A: [reply]
Reply B: [reply]
Which reply is better? Answer with 'A' or 'B' on the first line, then one sentence why.
With the 60-word reply in position B:
B

Reply B is clearer and more customer-friendly by explicitly asking the customer to reply if carrier can't help and outlining that the team will look into options including return and reshipment.
Swap the order, so the 45-word reply is now B:
B

Reply B is slightly better because it's brief, clear, and gives the customer a direct course of action (use carrier tracking link, or contact us to arrange return) without extra hedging.
Both verdicts say "B" about different replies, with opposite reasons: detail wins once, brevity the next. Across repeated samples the swapped order also split between A and B. A single call would have reported either result with full confidence.
A rubric judge asks narrower questions and requires evidence:
Score this support reply against the rubric. For each criterion answer yes or no with a short quote from the reply as evidence, then give the total number of yes answers.
1. States clearly that the shop can't change the address after shipping.
2. Gives a concrete next step the customer can take now.
3. Says what happens if that step fails.
4. Is under 60 words.1. … Yes — "Once an order has shipped we can't change the address ourselves"
2. … Yes — "use the carrier's tracking link to request a redirect or hold at a pickup point"
3. … Yes — "If that isn't possible, contact us and we'll arrange a return once the parcel comes back."
4. Is under 60 words.
No — The reply is Thirty-three? Wait count: "Once(1) an2 order3 … 45 words — that's under 60, so Yes.Criteria 1 to 3 are now checkable against the quotes. Criterion 4 shows the limit: the model started with "No", then counted and reversed itself. len(reply.split()) < 60 does that job exactly. Results vary by model.
[04]
What it changes in practice
Treat a single verdict as one juror. Run each pairwise comparison in both orders. A consistent win counts; a flip is a tie.
Decompose quality into criteria. Yes/no questions with a required quote are easier for the model to answer and for you to audit than "which is better". Anything countable, such as length, format, required fields or valid links, goes to code instead.
Mix model families and vote. Two or three judges from different providers, majority vote, and a record of dissent. Check the panel against a few dozen human labels before trusting it at scale.
[05]
Frequently asked questions
What is LLM-as-a-judge?
LLM-as-a-judge means using a language model to score or compare outputs from another model, instead of human raters or exact-match metrics. It scales evaluation of open-ended text such as summaries, support replies and agent answers. It works best with clear criteria and bias controls.
What is position bias in LLM judges?
Position bias is a judge's tendency to prefer an answer because of where it appears, often the first, regardless of quality. The standard fix is to evaluate both orders and only count a win that holds both times (Zheng et al., 2023).
How many judges do I need?
Start with one judge run in both orders plus a rubric. Add a second and third model from different families when results drive real decisions. Verga et al. (2024) found a panel of smaller models beat a single large judge at a fraction of the cost.
Can an LLM judge replace human evaluation?
Not entirely. Use humans to label a small sample, measure how often the judge or jury agrees with them, and recheck when you change models or prompts. Keep humans on high-stakes or subjective calls.
[06]
Next steps
How to evaluate AI agents in Python: build an eval set and run it.
Beginner eval loops: test prompts against fixed cases.
Why LLMs give similar answers: generate candidates worth judging.
Why LLMs mirror you: framing bias also affects judges.
Rank-then-respond and prompt ensembles: ranking candidates inside one pipeline.
Mental Models: How to Think with LLMs: the full learning path.