Contents · 9 sections↓
LLM self-correction means having a model review and revise its own output at inference time, with no fine-tuning: draft, get feedback, rewrite. Self-Refine, Reflexion and CRITIC are the best-known versions. They work well when the feedback carries real information, such as a failing test, a search result or a checklist the model can verify, and much less when the model just rereads its own answer. This guide explains each method, shows a real case where self-review missed a bug that a test caught, and gives a loop you can reuse.
Can an LLM correct its own mistakes?
Sometimes. A model can improve its output when the feedback adds information it didn't use the first time: test failures, tool results, a rubric with checkable items. Without external feedback, self-correction on reasoning tasks is unreliable. Large Language Models Cannot Self-Correct Reasoning Yet (Huang et al., ICLR 2024) found models struggled to fix reasoning without external feedback and sometimes got worse. The practical rule: give the critic something to check against.
Key takeaways:
External feedback beats self-review. Tests, validators, search results and code checks give the model facts, not opinions.
Self-Refine works best for quality and style, where "better" is visible in the text.
Reflexion stores lessons across attempts, which helps when a task is retried.
Cap the loop. One or two revisions capture most of the benefit; stop when checks pass.
Each round costs a full call. Use it where errors are expensive.
[02]
How the main self-correction methods work
Method | Paper | Feedback comes from | Loop |
|---|---|---|---|
Self-Refine | Madaan et al., 2023, arXiv:2303.17651 | The same model, critiquing its own output | Generate, feedback, refine, repeat |
CRITIC | Gou et al., 2023, ICLR 2024, arXiv:2305.11738 | Tools: search, a code interpreter, a toxicity API | Generate, verify with tools, revise |
Reflexion | Shinn et al., 2023, arXiv:2303.11366 | Task signals (tests, environment), turned into written reflections | Attempt, reflect, store reflection in memory, retry |
Constitutional AI (critique step) | Bai et al., 2022, arXiv:2212.08073 | A list of written principles | Critique against a principle, revise |
Self-Refine uses one model as generator, critic and reviser, and reports around 20% absolute improvement on average across seven tasks, from dialog responses to math, with GPT-3.5 and GPT-4. CRITIC's paper concludes by highlighting "the crucial importance of external feedback". Reflexion reported 91% pass@1 on HumanEval by reflecting on failed unit tests. The common thread in the strongest results is a signal from outside the model.
Constitutional AI's critique-and-revise step was used to generate training data, but the prompting pattern (critique this against principle X, then revise) works at inference time too.
[03]
Worked example: self-review vs test feedback
The task, at minimal reasoning effort:
Write a Python function parse_duration(s: str) -> int that returns a duration in seconds.
Accept strings like "1h30m", "45s", "2h", "1h 5m 10s" and "90m".
Raise ValueError for anything else. Return only the code.
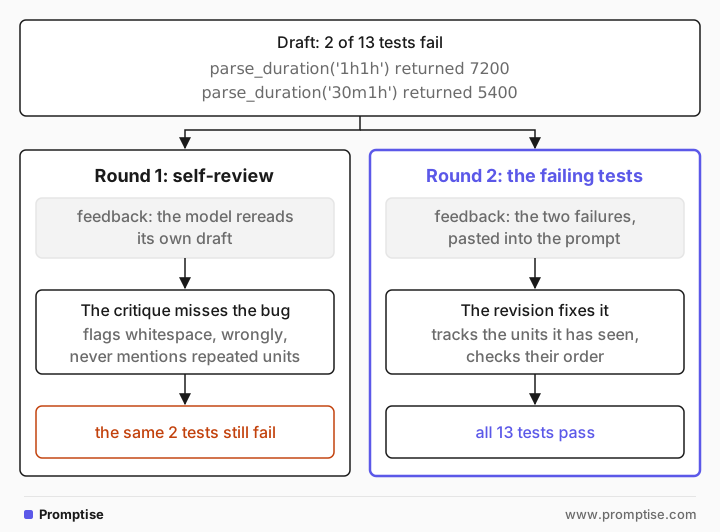
The draft was reasonable: it stripped whitespace, matched number-unit pairs with a regex and rejected garbage between them. Thirteen test cases found two failures:
parse_duration('1h1h') returned 7200, expected ValueError
parse_duration('30m1h') returned 5400, expected ValueError
The draft accepts repeated units and units out of order. "Raise ValueError for anything else" arguably covers both, but the model didn't read it that way.
Round 1: ask the model to review its own code
<task>

Here is a draft:
<draft>

Review the draft for bugs and unhandled edge cases. List what you find in at most 5 short bullets,
then give the corrected code in one Python code block.- The code rejects strings with leading whitespace (e.g. " 1h") because the first token start != pos and the matched_any check prevents treating leading whitespace as OK.
- The matched_any check in the gap validation is unnecessary; you should allow whitespace between tokens (including before the first token).
- The trailing-character check is correct but the error messages can be simplified; keep consistent ValueError usage.
- Otherwise the token parsing (digits + optional internal spaces + unit h/m/s) is fine; keep re.IGNORECASE to accept upper/lowercase units.The first bullet is wrong: the draft calls s.strip() before parsing, so leading whitespace never reaches that check. The real problems, repeated and out-of-order units, aren't mentioned. Run against the tests, the "corrected" code fails the same two cases. In an earlier self-review with a different prompt, the model did notice that "5s1h" and "1h30m15m" were accepted, then called them acceptable "depending on spec" and "probably acceptable". Either way, self-review didn't change the outcome.
Round 2: give the model the failing tests
<task>

Here is a draft:
<draft>

The draft fails these tests:
parse_duration('1h1h') returned 7200, expected ValueError
parse_duration('30m1h') returned 5400, expected ValueError

Fix the code so these pass without breaking the valid formats. Return only the code.
The revision added a set of seen units and an order check (trimmed):
    seen_units = set()
    for m in token_re.finditer(s):
        …
        if unit in seen_units:
            # duplicate unit (e.g. "1h1h" or "30m1m") is invalid
            raise ValueError(f"duplicate unit: {unit}")
        seen_units.add(unit)
    …
    # enforce ordering: hours, then minutes, then seconds if multiple units provided
All 13 tests pass. The test output told the model exactly what "anything else" meant, which no amount of rereading could. That's the CRITIC and Reflexion insight in one example. Results vary by model and task; a stronger reasoning setting might have caught these cases in the draft.
[04]
When to use self-correction (and when not to)
Use a revise loop when:
You have a checker: unit tests, a schema validator, a linter, a SQL EXPLAIN, a fact lookup.
The output must meet a checklist: required facts, length, forbidden words, format. Check what you can in code and give the model the result.
Style and clarity matter and a second pass is cheap compared to a human edit.
Skip it when:
You'd only ask "are you sure?" on a reasoning answer. That tends to produce changes, not improvements.
Latency matters more than the last bit of quality. Each round is a full model call.
The first output already passes all checks. Stop, don't polish.
[05]
A reusable revise loop
def generate_with_feedback(task: str, check, max_rounds: int = 2) -> str:
    """check(output) returns a list of problems; empty means done."""
    output = llm(task)
    for _ in range(max_rounds):
        problems = check(output)
        if not problems:
            return output
        output = llm(
            f"{task}\n\nHere is a draft:\n{output}\n\n"
            "It has these problems:\n" + "\n".join(f"- {p}" for p in problems) +
            "\n\nFix every problem without changing anything that already works. "
            "Return only the corrected output."
        )
    return output  # still failing: log it and escalate
check is where the value comes from. For code, run the tests. For structured output, validate against the schema. For writing, count words and search for banned phrases in code, and use a model only for the checks code can't do, such as "does this contradict the source?".
If you build prompts with Promptise Foundry, a self_critique strategy adds a critique-and-revise pass to a prompt function. It's the self-review half of this loop; pair it with a guard or validator for the external half.
[06]
Reflexion: keep the lessons
Reflexion adds memory. After a failed attempt, the model writes a short reflection ("I accepted repeated units; the tests require each unit at most once") and that text is added to the prompt for the next attempt. It helps when the same kind of task is retried many times, as in coding agents or game environments. Keep the reflections short, specific and tied to the signal that produced them; vague lessons ("be more careful") add tokens and nothing else. For agents that store lessons from failed tool calls across runs, see self-improving AI agents.
[07]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
"Review your answer" with no new information | The model rereads its own reasoning and keeps its blind spots, or changes correct parts | Add tests, tool results or a checklist |
Unlimited revise rounds | Cost grows, output drifts, correct parts get rewritten | Stop when checks pass; cap at 1-2 rounds |
Feedback as vague opinion ("make it better") | The revision changes style at random | List specific, checkable problems |
Conflicting instructions in the critique prompt | The model spends the round deciding which to follow | Restate the task without contradictory rules |
Trusting the critique | Critiques can be wrong, as above | Verify the revised output with the same checks |
LLM-judging what code can check | Slower, costlier, less reliable | Word counts, schemas, tests in code |
[08]
Frequently asked questions
What is Self-Refine?
A method from Madaan et al. (2023) where one model generates an output, writes feedback on it, and revises using that feedback, repeating until a stop condition. It needs no training data or fine-tuning and works best on tasks where quality is visible in the text, like dialog, code readability or rewriting.
What's the difference between Reflexion and Self-Refine?
Self-Refine improves one output within a single task. Reflexion runs repeated attempts at a task, turns each failure signal (such as failed tests) into a written reflection and keeps those reflections in memory for later attempts.
Why doesn't asking the model to double-check always work?
Without new information the model reviews its answer with the same knowledge and blind spots that produced it. Huang et al. (2023) found intrinsic self-correction often didn't help on reasoning and sometimes hurt. Feedback from tests, tools or retrieved facts gives it something new to act on.
How many revision rounds should I run?
Usually one or two. Stop as soon as the checks pass. If the output still fails after two rounds, the model may lack the knowledge or the task may be ambiguous; escalate instead of looping.
Is self-correction the same as fine-tuning?
No. Nothing about the model changes. Improvement happens in the prompt: feedback, critiques and stored reflections. Remove them and the model behaves as before.
[09]
Next steps
Model-based fact checking: verification loops: CoVe and SelfCheckGPT.
Check outputs in code first: LLM output validation.
Improve the prompt instead of each output: automatic prompt optimization.
Agents that learn from failed tool calls: self-improving AI agents.
Use a model as a grader: LLM as a jury, not a judge.