Contents · 7 sections↓
Rank-then-respond means generating several candidate answers, ranking them with a judge, and returning the winner. A prompt ensemble produces those candidates by running different prompt variants on the same input. Together they help when one prompt gives uneven results and a wrong or weak answer is costly: customer replies, product copy, summaries, code review comments. This guide shows a real three-variant ensemble with an LLM judge, the position bias that flipped its verdict, and the fixes: hard rules in code, judging in both orders, and adding up ranks.
What is rank-then-respond with prompt ensembles?
Run two to five prompt variants (or one prompt sampled several times) to get candidate answers, score them against a written rubric with a judge prompt, and return the top-ranked one. The judge is usually an LLM. Because LLM judges favor certain positions and styles, a reliable setup checks hard constraints in code first, judges in more than one order, and aggregates.
Key takeaways:
Variety comes from the prompts. Different instructions (tone first, facts first, brevity) produce different strengths to choose from.
Put measurable rules in code, not in the rubric. The judge in the example claimed a 177-word draft was "under 120 words".
Judge in at least two orders. Swapping the order changed the winner in the example.
Use it where quality varies and matters. For a short factual answer, one good prompt or self-consistency is cheaper.
[02]
How it works, and where it comes from
The pattern has two stages: propose, then select. Several papers shaped how to do each well:
Prompt ensembles. Ask Me Anything (Arora et al., 2022) ran several imperfect prompt reformulations and combined their answers. Boosted Prompt Ensembles for Large Language Models (Pitis, Zhang, Wang and Ba, 2023) built a set of few-shot prompts, each adding examples the previous ensemble was unsure about. Both target tasks with short answers that can be combined by voting or weighting.
Ranking and fusing free-form candidates. LLM-Blender (Jiang, Ren and Lin, 2023) ranks outputs from different models with a pairwise ranker (PairRanker), then merges the top ones with a fusion model (GenFuser). Universal Self-Consistency (Chen et al., 2023) asks the LLM itself to pick the most consistent answer among samples, which works for free-form text where voting doesn't.
Judge bias. Large Language Models are not Fair Evaluators (Wang et al., 2023) showed that changing the order of candidates can swing a judge's verdict; with ChatGPT as judge, Vicuna-13B could beat ChatGPT on 66 of 80 queries just by reordering. Their fixes include having the judge write its evidence before scoring and averaging over both orders. Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena (Zheng et al., 2023) also documents position, verbosity and self-enhancement bias.
[03]
Worked example: replying to an angry customer
The input is a ticket and the facts the reply must state:
Customer: I returned my headphones 3 weeks ago (order 48213). Your site said refunds take
5-7 business days. I still have nothing and support hasn't answered my two emails. I want my money.
Facts: the return arrived on day 4; the refund was approved today; card refunds post in 3-5 business days.three prompt variants
VARIANTS = {
    "plain": "Write a reply to this customer.",
    "empathy_first": "Write a reply to this customer. Open by acknowledging the delay and the unanswered emails, then give the facts.",
    "brief_actions": "Write a reply to this customer in at most 80 words: state what happened, when the money arrives, and one thing we will do if it doesn't.",
}
drafts = {name: ask(f"{TICKET}\n{FACTS}\n\n{instruction}") for name, instruction in VARIANTS.items()}
The three drafts came back at 177, 123 and 69 words. The shortest, in full:
Hi — thanks for your patience. Your return (order 48213) arrived on day 4, and we approved the refund today. Bank card refunds usually post in 3–5 business days, so you should see the credit by [date = today + 3–5 business days]. If the refund hasn't appeared after 5 business days, reply to this email and we'll escalate immediately and open an urgent investigation with our payments team.Correct facts and a next step, but no apology for the unanswered emails, and a template placeholder left in. The plain draft was thorough but long, with a subject line and sign-off placeholders. Each variant had a different weakness, which is what gives a judge something to choose between.
a rubric judge, run in two orders
You are ranking draft replies to a customer. Score each draft against this rubric:
1. States the refund date range correctly from the facts (most important).
2. Acknowledges the delay and the unanswered emails without excuses.
3. Gives a concrete next step if the money does not arrive.
4. Under 120 words, no invented facts or promises.

{ticket}
{facts}

{drafts}

Rank the drafts from best to worst.
The judge returns JSON with a ranking and a reason (structured output). Run once with the drafts in order plain, empathy_first, brief_actions, and once reversed:
order A: ['Draft plain', 'Draft empathy_first', 'Draft brief_actions'] | … Draft plain is best: it explicitly lists facts, apologizes, and provides a clear escalation step without invented promises and stays under 120 words …
order B: ['empathy_first', 'brief_actions', 'plain'] | … Plain is third because, while complete, it is verbose (over 120 words) and thus fails the word-limit criterion.
The same judge, the same drafts, two different winners. In order A it also said the 177-word draft "stays under 120 words". That is the order effect the Wang et al. paper describes, plus a judge that can't count.
rules in code, both orders, add up ranks
import json
from collections import defaultdict

RANK = {"type": "json_schema", "json_schema": {"name": "rank", "strict": True, "schema": {
    "type": "object", "additionalProperties": False, "required": ["ranking", "reason"],
    "properties": {"ranking": {"type": "array", "items": {"type": "string"}}, "reason": {"type": "string"}}}}}


def judge(order: list[str]) -> list[str]:
    labeled = "\n\n".join(f"Draft {name}:\n{drafts[name]}" for name in order)
    result = json.loads(ask(RUBRIC.format(ticket=TICKET, facts=FACTS, drafts=labeled), response_format=RANK))
    return [r.removeprefix("Draft ").strip() for r in result["ranking"]]


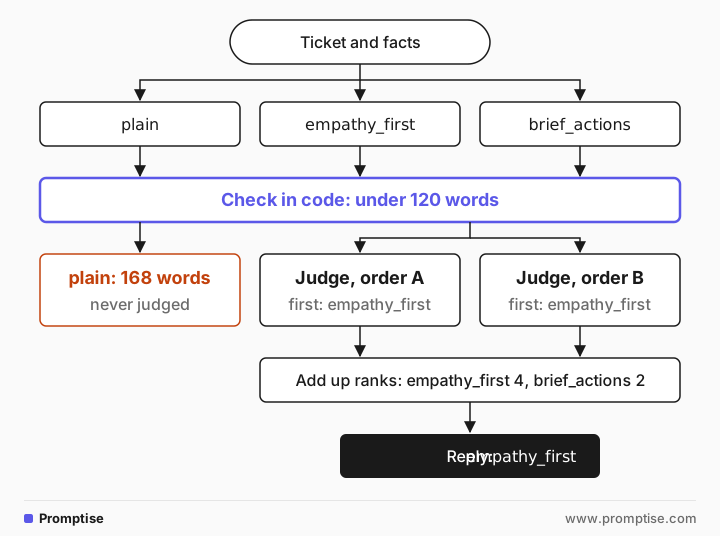
eligible = [name for name, text in drafts.items() if len(text.split()) <= 120]  # hard rule, checked in code
points = defaultdict(int)
for order in (eligible, eligible[::-1]):
    for place, name in enumerate(judge(order)):
        points[name] += len(eligible) - place
winner = max(points, key=points.get)
A run of the full pipeline (it generates fresh drafts, so word counts differ from the run above):
passed the word limit: ['empathy_first', 'brief_actions']
judge order ['empathy_first', 'brief_actions'] -> ['empathy_first', 'brief_actions']
judge order ['brief_actions', 'empathy_first'] -> ['empathy_first', 'brief_actions']
total points: {'empathy_first': 4, 'brief_actions': 2} -> winner: empathy_first
The plain draft (168 words this time) never reached the judge. Both orders agreed, so the result is stable. When the two orders disagree, treat it as a tie: return either, or send both to a person. Note the removeprefix line: the judge labeled drafts as "Draft plain" in one run and "plain" in another, and an unnormalized comparison would report a disagreement that isn't there.
[04]
When to use it (and when not to)
Situation | Use | Note |
|---|---|---|
Customer-facing text, high volume, uneven quality | Prompt ensemble plus judge | 2 to 3 variants, 2 judge calls |
One prompt is already good on your test set | Neither | Ensembles multiply cost for small gains |
Short answer you can compare | Voting, no judge needed | |
Output you can test (code, SQL) | Generate several, run the tests | Tests beat judges |
Choosing between plans or outlines | One level of this, then write | A light form of Tree of Thoughts |
What changes with reasoning models
A strong reasoning model often writes a reply that satisfies the whole rubric on the first try, if the rubric is in the prompt. Try that first: put the four rubric points into a single prompt and measure on 20 to 30 real tickets. The ensemble earns its cost when the best single prompt still varies a lot from input to input, or when you want a cheap model to propose and a stronger one to judge. Bias in the judge doesn't disappear with stronger models, so keep the order swap and the code checks either way.
[05]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Word counts and formats in the rubric | Judges misjudge length and structure | Check them in code before judging |
One judge pass, one order | Position bias can decide the winner | Judge both orders; aggregate ranks |
Variants that differ only in wording | Candidates are near-identical, so ranking adds nothing | Vary the approach: what to lead with, length, structure |
Vague rubric ("best reply") | The judge falls back on length and polish | Numbered criteria, the most important first |
Same model writes and judges without checks | Self-preference and shared blind spots | Code checks, a different judge model, or both |
Not normalizing judge labels | False disagreements break aggregation | Strip prefixes, match on IDs |
[06]
Frequently asked questions
How many candidates should a prompt ensemble produce?
Two to four. Each candidate adds a generation call and makes the judge's context longer, and judges get less reliable as the list grows. If you need more, compare candidates in pairs.
Pairwise or listwise judging?
Listwise (rank all at once) is cheaper for three or four candidates. Pairwise comparisons are more reliable for close calls and scale as a tournament, at the cost of more calls. Either way, swap the order.
Should the judge be a bigger model than the proposers?
It often helps: cheap proposers, one stronger judge. A judge with a precise rubric and code checks can also be a small model. Test on examples where you know the right ranking.
Can I merge the best candidates instead of picking one?
Yes. LLM-Blender's GenFuser does this with a trained model; with prompts, give the top two candidates to the model and ask for one reply that keeps the strengths of each. Re-check the fused output against the same code rules, because fusion can bring back problems you filtered out.
Is this the same as LLM-as-a-judge evaluation?
The judge is the same idea, used at runtime to choose an output instead of offline to score a system. The biases are the same too; see LLM as a jury, not a judge.
[07]
Next steps
Voting for short answers: self-consistency and least-to-most.
Why one judge is not enough: LLM as a jury, not a judge.
Measure before adding calls: beginner eval loops.
Steer the variants: few-shot examples the right way.
Reasoning basics: chain-of-thought for beginners.
Search over candidates: Tree of Thoughts.