Contents · 9 sections↓
Automatic prompt optimization uses a model to write and improve prompts for you, scored against labeled examples instead of judged by eye. You give it a task, a small dataset and a metric. It proposes instructions, measures them, studies the failures and edits the prompt. This guide explains the main methods (APE, ProTeGi, OPRO and multi-branch prompts like AMPO), then walks through one real optimization round on a ticket classifier in plain Python. It's for developers who already have a prompt in production and a few dozen labeled examples.
What is automatic prompt optimization?
Automatic prompt optimization treats the prompt as a parameter you search over. A model generates candidate instructions, each candidate is scored on labeled examples, and the best ones are kept or edited further. APE generates and selects candidates. ProTeGi critiques a prompt using its errors and edits it. OPRO shows the optimizer past prompts with their scores. The common requirement is a dataset and a score you trust.
Key takeaways:
No dataset, no optimization. You need labeled examples and a metric; 20 to 50 examples is a workable start.
Hold out a test set. Optimized prompts overfit the examples they were tuned on.
Learning from errors (ProTeGi-style) is the most practical loop for an existing prompt.
Read the winning prompt. It may encode rules you didn't intend.
Use a library at scale. DSPy and similar tools run these searches for you.
[02]
How the methods work
Method | Paper | How it works | What it's good at |
|---|---|---|---|
APE (Automatic Prompt Engineer) | Zhou et al., 2022, arXiv:2211.01910 | Shows the model input-output pairs, asks it to infer the instruction, generates many candidates, scores each, keeps the best | Writing a first instruction from examples |
ProTeGi / APO | Pryzant et al., 2023, EMNLP, arXiv:2305.03495 | Uses a minibatch of errors to write a natural-language "gradient" (a critique), edits the prompt "in the opposite semantic direction", beam search and bandit selection pick candidates | Improving an existing prompt |
OPRO | Yang et al., 2023, ICLR 2024, arXiv:2309.03409 | Puts previous prompts and their scores in the optimizer's prompt; the model proposes better ones each step | Searching when you can run many iterations |
AMPO | Yang et al., 2024, arXiv:2410.08696 | Builds a multi-branched prompt from failure cases, with pattern recognition, branch adjustment and branch pruning | Tasks where different inputs need different handling |
DSPy | Khattab et al., 2023, arXiv:2310.03714 | Declares the pipeline in code; optimizers tune instructions and few-shot demonstrations against a metric | Multi-step pipelines, production use |
The reported gains are on the papers' benchmarks: APE matched or beat human-written instructions on 19 of 24 tasks; ProTeGi improved initial prompts by up to 31%; OPRO's prompts beat human-designed ones by up to 8% on GSM8K and up to 50% on Big-Bench Hard tasks. Your gain depends on how weak the starting prompt is and how clean your labels are.
[03]
When to use automatic prompt optimization (and when not to)
Use it when:
The task has a clear right answer per example: classification, extraction, routing, short-form QA.
You have, or can label, at least a few dozen examples that look like production traffic.
You'll re-run it: when the model changes, when the label set changes, when new failures appear.
Skip it when:
You can't score outputs automatically. For open-ended writing, an LLM judge is possible, but you're now optimizing against the judge's taste.
The examples are unrepresentative. The optimizer learns your dataset, not your users.
A missing rule is obvious. If you already know the fix, write it.
[04]
Worked example: one optimization round on a ticket classifier
The task: label support tickets as billing, account_access, bug, feature_request or other. There are 12 labeled development examples and 8 held-out test examples, kept in DEV and TEST as lists of (ticket, label) pairs. The house rule is that a ticket about money or login goes to billing or account access even if it mentions an error, but the starting prompt doesn't say so.
Score the current prompt
import json
from openai import OpenAI

client = OpenAI()
LABELS = ["billing", "account_access", "bug", "feature_request", "other"]
SCHEMA = {"name": "label", "strict": True, "schema": {
    "type": "object", "additionalProperties": False,
    "properties": {"label": {"type": "string", "enum": LABELS}}, "required": ["label"]}}

def classify(instruction: str, ticket: str) -> str:
    r = client.chat.completions.create(
        model="gpt-5-mini", reasoning_effort="minimal",
        messages=[{"role": "system", "content": instruction}, {"role": "user", "content": ticket}],
        response_format={"type": "json_schema", "json_schema": SCHEMA})
    return json.loads(r.choices[0].message.content)["label"]

def score(instruction: str, data: list[tuple[str, str]]):
    errors = [{"ticket": t, "predicted": p, "expected": gold}
              for t, gold in data if (p := classify(instruction, t)) != gold]
    return len(data) - len(errors), errors

base = "Classify the support ticket as billing, account_access, bug, feature_request or other."
for name, data in [("dev", DEV), ("test", TEST)]:
    ok, errors = score(base, data)
    print(f"baseline {name}: {ok}/{len(data)}")
    if name == "dev":
        for e in errors:
print(f'- "{e["ticket"]}" -> predicted {e["predicted"]}, expected {e["expected"]}')baseline dev: 9/12
- "After the SSO update the login page shows error 500." -> predicted bug, expected account_access
- "When I try to downgrade my plan the page freezes." -> predicted bug, expected billing
- "The mobile app logs me out every few minutes." -> predicted bug, expected account_access
baseline test: 7/8The structured output with an enum matters: the classifier can only return a valid label, so the score measures judgment, not formatting.
Ask for a "gradient"
ProTeGi's first step is a critique written from the failures:
I'm writing a prompt for a support-ticket classifier.
My current prompt is:
"Classify the support ticket as billing, account_access, bug, feature_request or other."

It gets these examples wrong:
<the three errors>

Give 3 short reasons why the prompt could have produced these errors. Be specific about missing rules.1) No rule to prefer user-facing intent/category over technical symptom — the prompt doesn't say whether to classify by the user's problem domain (e.g., "can't access account") or by the technical failure mode (e.g., "server error"), so "error 500" and "page freezes" get treated as bugs instead of account_access or billing.
2) Missing explicit mappings for common keywords/contexts — there are no rules like "SSO, login, logout, session expiry → account_access" or "plan, downgrade, payment → billing", so the classifier defaults to generic "bug" when it sees errors or failures.
3) No tie-breaker for ambiguous tickets …That diagnosis is correct. It found the missing rule from three examples.
Edit the prompt and score the candidates
Current prompt:
"<base prompt>"

Problems found:
<the critique>

Write 3 different improved versions of the prompt that fix these problems. Each must still be a
general instruction (no copied example tickets) and under 120 words.
Each candidate is scored on the development set, and the best one on the test set it has never seen:
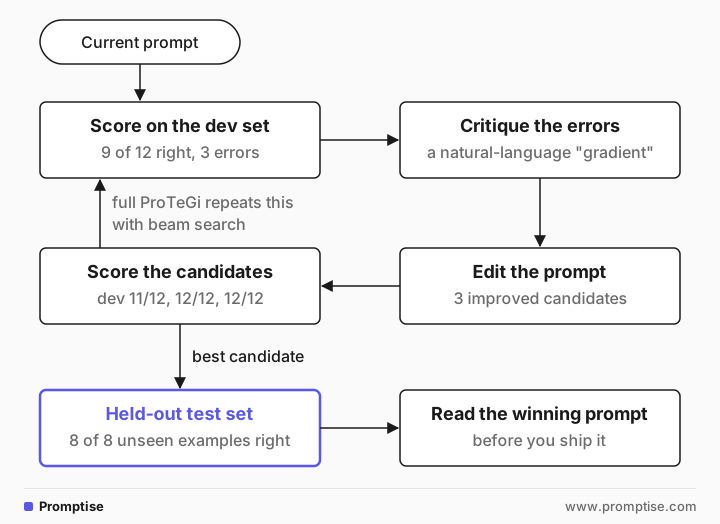
candidate 0: dev 11/12
candidate 1: dev 12/12
candidate 2: dev 12/12

best candidate on held-out test: 8/8
The winning prompt:
Assign one of: billing, account_access, bug, feature_request, other. Prefer user-facing intent: payment/plan/charge/refund/invoice → billing; login/SSO/session/password/account locked → account_access. Map explicit requests for new functionality to feature_request. Classify technical failures (error codes, crashes, page freezes, missing UI behavior) as bug only when no billing/account intent exists. If both intent and technical symptom occur, pick the user's intent. Use other for unclear or unrelated tickets.Read it before you ship it. It contains a keyword list ("SSO", "session") lifted from the failures, which is fine here but is how optimized prompts overfit. The held-out 8/8 says it generalized at least to those examples. With 20 examples in total, this is a sanity check, not a measurement; use more examples before trusting small differences.
The full ProTeGi algorithm repeats this with beam search over many candidates and bandit selection to save evaluation calls. One round already fixed the obvious gap.
What APE would have done
APE starts from examples instead of a prompt. Given six input-output pairs, the model inferred three instructions. Scored on the same development set:
candidate 0: dev 8/12
Classify each user message into one of these categories: billing, account_access, bug, or feature_request. Return only the single label for each input.
…
candidate 2: dev 10/12
Given a user complaint or request, decide which of these labels fits best: billing (payment/refund issues), account_access (login/2FA/SSO problems), bug (software defects), feature_request (new feature or improvement). Respond with only the label.
None of the candidates mentions other, because none of the six demonstrations was labeled other. APE can only infer what the examples show. Cover every label in the demonstrations, and generate many more candidates than three; the paper's strength comes from searching a large pool.
[05]
Multi-branch prompts
Look at the winning prompt again: "if both intent and technical symptom occur, pick the user's intent." That's a branch: different inputs follow different rules. AMPO (Yang et al., 2024) builds such branches deliberately. It groups failure cases into patterns, adds or adjusts a branch for each pattern, and prunes branches that don't help. The result reads like a decision procedure:
If the ticket asks for money back, a plan change or an invoice fix: billing, even if a bug caused it.
Else if the user can't sign in or stay signed in: account_access, even if an error code appears.
Else if something that exists doesn't work: bug.
Else if the user asks for something new: feature_request.
Else: other.
Branching helps when your task really has several input types. It also makes the prompt longer and harder to maintain, so prune branches that no longer change any score.
[06]
Running it for real
Keep prompts versioned. Store each candidate with its scores and the dataset version. In Promptise Foundry, PromptRegistry stores named, versioned prompts and supports rollback, so you can revert an optimized prompt that misbehaves in production.
Re-score on model changes. A prompt optimized for one model may score differently on another.
Grow the dataset from production failures. Every misrouted ticket is a new labeled example.
Use DSPy or a similar library when you have a pipeline with several steps, or want to optimize few-shot demonstrations together with the instruction.
[07]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Scoring on the examples you optimized on | You measure memorization | Keep a held-out test set |
A handful of examples | One example flips the score by 10 points | 20 to 50 or more, matching production |
Free-text outputs when scoring classification | Formatting noise counts as errors | Structured output with an enum |
Shipping the top-scoring prompt unread | It may contain copied examples or odd rules | Review it like code |
Demonstrations that miss labels | APE never learns those labels exist | Cover every label in the examples |
Optimizing against an LLM judge without checking the judge | You tune to the judge's bias | Validate the judge on human labels first |
[08]
Frequently asked questions
What's the difference between APE and ProTeGi?
APE writes candidate instructions from input-output examples and picks the best by score. ProTeGi starts from an existing prompt, writes a critique from its errors, edits the prompt to address the critique, and keeps the best edits. Use APE to bootstrap a prompt and ProTeGi to fix one.
How many examples do I need?
Enough that one example doesn't swing the score much. Twenty to fifty is a practical start for a classifier; more for many labels or subtle rules. Always keep some examples out of the optimization to test the final prompt.
Is DSPy the same as automatic prompt optimization?
DSPy is a framework that includes prompt optimizers. You declare the steps of your pipeline and a metric, and its optimizers tune instructions and few-shot examples. It saves you from writing the loop in this guide yourself.
Can I optimize prompts without labeled data?
Only with a substitute signal: an LLM judge, a code check (valid SQL, passing tests) or user feedback. Code checks are the most reliable. Judges work if you validate them against some human labels first.
Will an optimized prompt work on a different model?
Not necessarily. Prompts can depend on one model's habits. Re-score on the new model and re-run the optimization if the score drops.
[09]
Next steps
Build the dataset and checks first: beginner eval loops.
Improve prompts by hand first: simple instruction tuning by iteration.
Let models revise their outputs instead: self-refine and self-correction.
Prompt tests in CI: how to test LLM prompts in Python.
Choosing examples: few-shot prompting.