Contents · 6 sections↓
Ask a chat model for one idea eight times and you rarely get eight different ideas. You get variations on the same one. This essay, part of the Mental Models learning path, explains why instruction-tuned models converge on a "typical" answer, why re-rolling is a poor way to explore, and how to prompt for real variety in names, angles, test cases or synthetic data. It includes real output from a single-answer prompt and two better prompts.
Why do LLMs give similar answers to the same prompt?
Sampling should give a different answer each time, and it does, but the differences are small. Post-training with human feedback rewards the response raters like best, and raters tend to prefer familiar, typical text. The result is a sharp distribution: most of the probability sits on a few safe answers. Researchers call this mode collapse. You get more variety by asking for a set in one call, naming the axes the options should differ on, or asking the model to sample from its full range.
Key takeaways:
Re-rolling explores a small neighborhood. Independent samples share the same favorite answer.
A list in one call beats many single calls, because the model sees its earlier items and avoids repeating them.
Name the axes of variation. "Different" is vague; "one from each of these five sources" is not.
[02]
Why it's true
A pretrained model reflects the spread of text it was trained on. Instruction tuning and reinforcement learning from human feedback (RLHF) then push it toward responses people rate highly (Ouyang et al., 2022). That makes the model more helpful and also narrower. Understanding the Effects of RLHF on LLM Generalisation and Diversity (Kirk et al., 2023) found that RLHF generalizes better than supervised fine-tuning alone but "significantly reduces output diversity" across a range of measures.
Verbalized Sampling (Zhang et al., 2025) traces much of this to the preference data itself: annotators favor typical text, a typicality bias the authors link to findings in cognitive psychology. Their fix is a prompt, not retraining: ask the model for several candidates with the probability of each. They report diversity gains of 1.6 to 2.1 times over direct prompting in creative writing, without losing factual accuracy or safety.
[03]
Example: naming a coffee shop
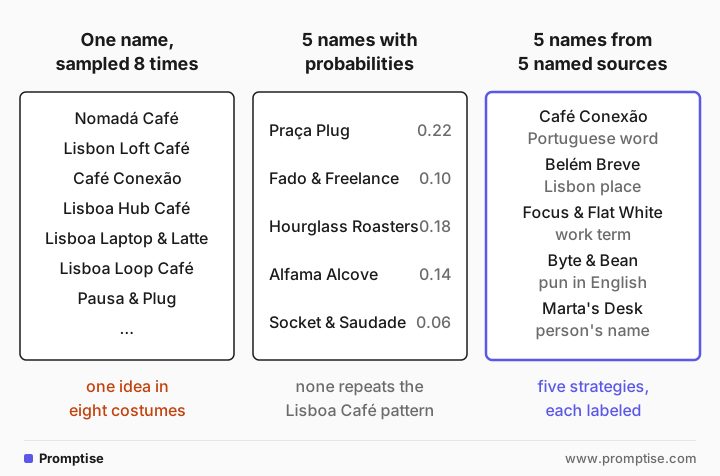
The single-answer prompt, sampled eight times:
Suggest a name for a small coffee shop in Lisbon aimed at remote workers. Reply with the name only.Nomadá Café
Lisbon Loft Café
Café Conexão
Lisboa Hub Café
Lisboa Laptop & Latte
Lisboa Loop Café
Pausa & Plug
Bica & BytesFour of eight start with "Lisbon" or "Lisboa", five contain "Café". That is one idea, the city name plus a coffee word, in eight costumes.
A verbalized-sampling prompt asks for the range directly:
Suggest names for a small coffee shop in Lisbon aimed at remote workers. Generate 5 candidates sampled from the full range of names you could give, including unusual ones, not just the most likely. For each, give the name and your estimated probability (0-1) that you would have given it as a single answer. Format: name | probability1. Praça Plug | 0.22
2. Fado & Freelance | 0.10
3. Hourglass Roasters | 0.18
4. Alfama Alcove | 0.14
5. Socket & Saudade | 0.06Treat the probabilities as a nudge toward the tail, not as measurements; they don't even sum to 1. The useful part is that none of the five repeats the "Lisboa Café" pattern.
When you know which dimensions matter, name them:
Suggest 5 names for a small coffee shop in Lisbon aimed at remote workers. Each name must come from a different source: 1) a Portuguese word, 2) a Lisbon place or landmark, 3) a work or productivity term, 4) a pun in English, 5) a person's name. One line each: name - source - why it fits.Café Conexão - Portuguese word ('conexão' = connection) - evokes Wi‑Fi, networking and community for remote workers.
Belém Breve - Lisbon place (Belém) - references a well‑known neighborhood and pastry heritage…
Focus & Flat White - work/productivity term (focus) combined with a coffee staple…
Byte & Bean - English pun ('byte' ~ computer data + 'bean' coffee)…
Marta’s Desk - person’s name (Marta, common in Portugal) - feels personal and inviting…Five distinct strategies, each labeled, so you can compare like with like. Results vary by model and run.
[04]
What it changes in practice
Generate sets, not singles. For brainstorming, test inputs, personas or synthetic data, ask for N items in one call with an instruction that they differ. Use the API's n parameter or repeated calls only when you want independent samples, for example to measure consistency.
Specify the axes. Audience, tone, mechanism, risk level, source of the idea. Axes turn "five cousins" into five options you can actually choose between, and they make gaps visible.
Push into the tail on purpose. Ask for unusual candidates and their probabilities, or ask for options "the obvious answer would miss". Then select hard: diversity is only useful with a clear rule for picking. The jury essay covers how to judge candidates fairly.
[05]
Frequently asked questions
What is mode collapse in LLMs?
Mode collapse is when a model puts most of its probability on a few typical outputs, so samples look alike even at normal temperature. It is mostly a side effect of post-training on human preferences, which reward familiar, safe responses over unusual ones.
Does raising the temperature fix it?
Partly. Higher temperature spreads probability to less likely tokens, but the extra variety is often in wording rather than in ideas, and quality drops as it rises. Some reasoning models accept only the default temperature. Prompt structure, such as sets and named axes, usually gives more useful diversity.
What is verbalized sampling?
A prompting method from Zhang et al. (2025): instead of asking for one response, you ask for several responses with the probability of each. Asking for a distribution leads the model to cover more of its range. It needs no training or special API.
When do I want low diversity?
For extraction, classification, code that must pass tests, and anything with one correct answer. There, consistent output is the goal and variety is noise. Use diversity techniques for open-ended work only.
[06]
Next steps
LLM as a judge vs a jury: pick the best candidate without biased judging.
How LLMs generate text: next-token sampling, temperature and top-p.
Rank-then-respond and prompt ensembles: generate several drafts and rank them.
Few-shot prompting: examples also narrow the output, for better and worse.
Mental Models: How to Think with LLMs: the full learning path.