Contents · 10 sections↓
- 01When should you use a small model vs a large model?
- 02How LLM routing works
- 03Routing signals, cheapest first
- 04Worked example: an LLM router with a rubric
- 05A routing design you can ship
- 06Route on reasoning effort, not only model size
- 07When routing pays off (and when it doesn't)
- 08Common mistakes
- 09Frequently asked questions
- 10Next steps
LLM routing sends each request to the cheapest model (or reasoning setting) that can handle it well, and saves the large, expensive one for requests that need it. Paying large-model prices for simple lookups is waste; sending a hard request to a small model costs you a wrong answer. This guide covers the main routing strategies (rules, an LLM router, learned routers, cascades), shows a real router misrouting a request and why, and gives a design you can ship. It's for developers who run LLM features at volume.
When should you use a small model vs a large model?
Use a small model (or low reasoning effort) for tasks with one step and a clear answer: classification, extraction, rewording, single-fact lookups, short replies from one document. Use a large model (or higher reasoning effort) for multi-step reasoning, calculations over user data, comparisons, ambiguous or high-stakes requests, and anything where a wrong answer costs money. Route with cheap signals first, then a classifier, and escalate when a check on the small model's output fails.
Key takeaways:
Start with rules. Task type, length and customer tier already separate a lot of traffic.
A router can be wrong. Test it on labeled requests, like any classifier.
Bias toward escalation on uncertain or high-stakes requests; a wrong cheap answer is the expensive outcome.
Cascades need a real check. Escalate on failed validation, not on the small model's own confidence alone.
Reasoning effort is a routing dimension too, not only model size.
[02]
How LLM routing works
There are two basic shapes:
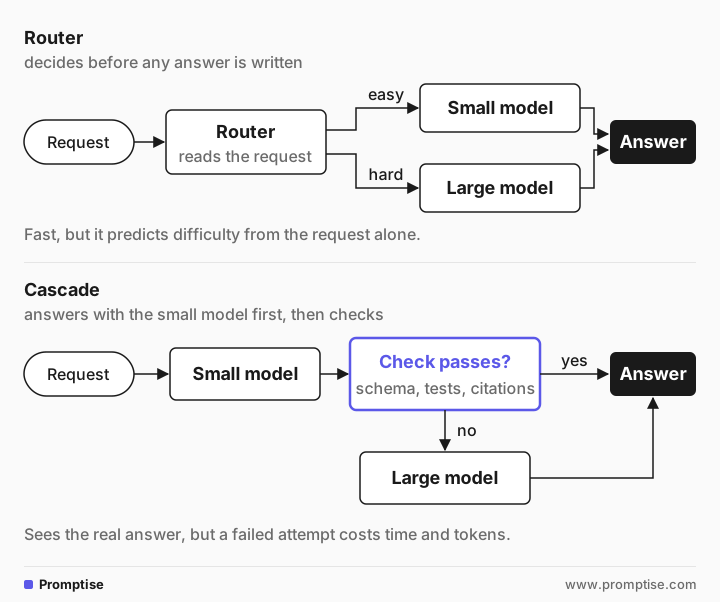
A router decides before any answer is generated. It's fast, but it has to predict difficulty from the request alone. A cascade tries the cheap model first and escalates if the output fails a check. It sees the actual answer, but a failed attempt costs time and tokens.
The research behind both:
Approach | Paper | Idea | Reported result |
|---|---|---|---|
Cascade | FrugalGPT, Chen, Zaharia and Zou, 2023, arXiv:2305.05176 | Query models in order of cost; a scorer decides whether to accept or escalate | Matched the best single model with up to 98% cost reduction on their tasks |
Learned router | Hybrid LLM, Ding et al., ICLR 2024, arXiv:2404.14618 | Predict query difficulty; tune the quality threshold at test time | Up to 40% fewer calls to the large model with no drop in quality |
Learned router | RouteLLM, Ong et al., 2024, arXiv:2406.18665 | Train routers on human preference data between a strong and a weak model | Costs reduced by over 2x in some cases without quality loss; routers transferred to new model pairs |
RAG vs long context | Self-Route, Li et al., EMNLP 2024, arXiv:2407.16833 | The model decides whether retrieved chunks suffice or the full context is needed | Comparable to long context at much lower cost |
Those results depend on the benchmark and the model pair. The shape of the gain carries over: most of the savings come from the large share of easy requests.
[03]
Routing signals, cheapest first
Signal | Example rule | Cost |
|---|---|---|
Endpoint or task type | Tagging and translation always go small | Free |
Request features | Over 2,000 tokens, attachments, code, or more than one question: large | Free |
Business context | Enterprise customer, legal or billing dispute, angry tone: large | Free or cheap |
LLM router | A small model classifies the request with a rubric | One small call |
Learned router | A trained classifier on your logs (RouteLLM-style) | Training once, cheap per call |
Output check (cascade) | Schema fails, missing citation, test fails: escalate | One extra small call when it fails |
Rules handle the obvious cases with no latency. Use a model-based router only for what rules can't decide.
[04]
Worked example: an LLM router with a rubric
You route support questions to a model tier. Reply with JSON.
small: one fact lookup, rewording, classification, short extraction, a question answered by one help article.
large: several steps or conditions, calculations over the customer's data, comparing options, legal or contract
wording, angry or high-value customers, anything where a wrong answer costs money.
If unsure, choose large.
Eight requests, routed by the model at minimal reasoning effort with a JSON schema (tier is an enum of small or large, plus a short reason):
small  How do I reset my password?
small  Translate this reply into Spanish: 'Your refund was issued today.'
large  We have 14 seats on Team and want to move 6 people to Business mid-cycle. What will next month's invoice be?
small  Is the API available in the EU region?
large  Your outage cost us a client. Section 9.2 of our MSA says we get credits. How much are we owed?
small  Tag this ticket: 'CSV export drops the last row'
small  Compare the Business and Enterprise plans for a 40-person team that needs SSO and audit logs.
small  What's your support email?
Seven of eight are right. The plan comparison went to small even though the rubric lists "comparing options" under large. The router's reason:
Simple product plan comparison and requirement mapping: user asks to compare Business vs Enterprise for a 40-person team needing SSO and audit logs (single-step informational task).The router talked itself into "single-step". This is why you test a router on labeled examples before trusting it, and why the clear cases belong in code. A keyword rule such as "compare", "vs" or "difference between" routes large is free, and it can't be argued out of.
[05]
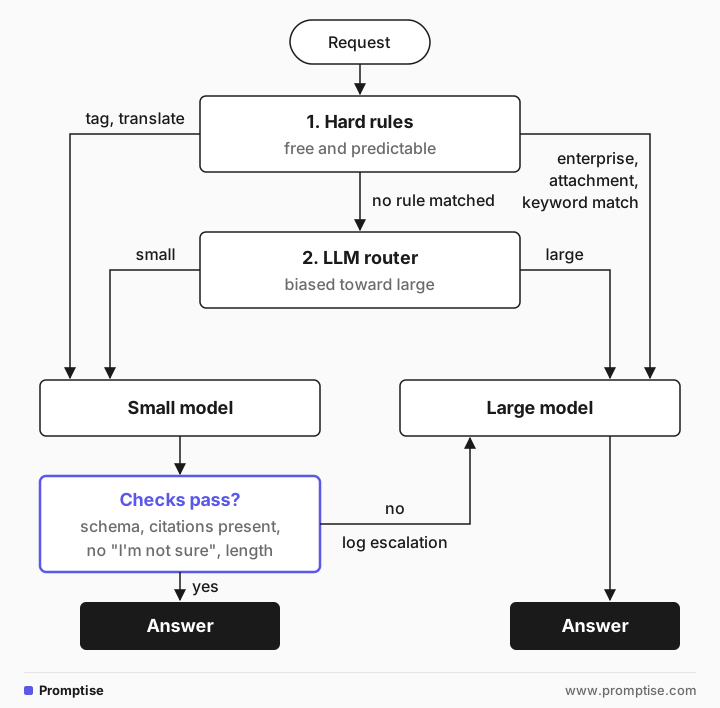
A routing design you can ship
def route(request: Request) -> str:
    # 1. Hard rules: free and predictable
    if request.endpoint in {"tag", "translate"}:
        return "small"
    if request.customer_tier == "enterprise" or request.has_attachment:
        return "large"
    if re.search(r"\b(compare|vs\.?|difference between|contract|refund|invoice)\b", request.text, re.I):
        return "large"
    # 2. LLM router for the rest, biased toward large
    tier = llm_router(request.text)          # returns "small" or "large"
    return tier

def answer(request: Request) -> str:
    tier = route(request)
    if tier == "small":
        draft = small_model(request)
        if passes_checks(draft, request):    # schema, citations present, no "I'm not sure", length
            return draft
        log_escalation(request, draft)       # these are your future router training data
    return large_model(request)
The cascade check after the small model matters more than the router. Good checks are ones code can run: the output validates against a schema, every cited document id exists, required fields are present, the answer doesn't hedge. Checks based only on the small model's self-reported confidence are weaker, because models can be confidently wrong.
Log every routing decision and every escalation. Escalations are labeled examples of "small wasn't enough", which is exactly the data RouteLLM-style routers are trained on.
[06]
Route on reasoning effort, not only model size
With reasoning models, the same model at different reasoning effort is effectively a small and a large tier. Low or minimal effort is faster and uses fewer tokens; high effort thinks longer on hard problems. Routing between effort levels has an advantage over switching models: the prompt, tools and output format stay identical, so there's one less source of differences to test. You can combine both: a small model at low effort, a large model at high effort, and options in between.
[07]
When routing pays off (and when it doesn't)
Route when:
You have high volume and a large share of simple requests.
The price gap between tiers is large.
You can tell easy from hard with cheap signals.
Don't bother when:
Volume is low. Engineering time costs more than the tokens.
Nearly every request is hard, or nearly every request is easy. Pick one tier.
The small model's errors are hard to detect. A cascade without a reliable check just adds latency.
If quality matters more than cost on some paths, keep those on the large model permanently and route only the rest.
[08]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Trusting the router without testing it | It misroutes in ways the rubric seemed to forbid | Label 50 to 100 real requests and measure |
LLM router for cases rules can decide | Slower, costs a call, can argue itself out of the rule | Hard rules first, model for the rest |
Escalating on "confidence: high/low" only | Small models can be confidently wrong | Escalate on checks code can run |
Optimizing average cost only | A few bad answers on high-stakes requests cost more than the savings | Route high-stakes categories to large always |
Different prompts per tier, untested | Tier differences become prompt differences | Same prompt and schema; test both tiers on your eval set |
No logging of decisions | You can't improve the router | Log route, reason, escalations and outcomes |
[09]
Frequently asked questions
What is an LLM router?
A component that decides which model handles each request, based on rules, a classifier or a small model that reads the request. The goal is the lowest cost that still meets your quality bar.
What's the difference between a router and a cascade?
A router chooses a model before answering. A cascade answers with the cheapest model first and escalates to a stronger one if the answer fails a check. Many systems use both: a router for clear cases and a cascade for uncertain ones.
Can a small model route requests?
Yes, and it's common. Give it a short rubric and a structured output with an enum. Test it on labeled examples; small routers misjudge borderline cases, so bias them toward the large tier when unsure.
How do I know if routing hurts quality?
Run your eval set through both tiers and through the router, and compare scores per category. Watch escalation rates and user feedback after launch. If quality drops on a category, route that category to the large model by rule.
Is RouteLLM worth using?
If you have preference data or enough logs of requests with outcomes, a learned router like RouteLLM can beat a hand-written rubric. Start with rules and an LLM router, log decisions, and train one once you have the data.
[10]
Next steps
Choose the models for each tier: best LLM for AI agents.
Track what each tier costs: AI agent cost tracking.
Cap spend per run and per day: AI agent cost control.
Fallback when a provider fails: LLM semantic cache and model fallback.
Measure routing quality: how to evaluate AI agents.
Get reliable router output: structured outputs.