Contents · 16 sections↓
- 01What should be on an LLM security checklist?
- 02How to use this checklist
- 031. Prompts and secrets
- 042. Input and prompt injection
- 053. Retrieval and data access
- 064. Output handling
- 075. Tools and agency
- 086. Models and dependencies
- 097. Abuse, rate limits and cost
- 108. Logging and monitoring
- 119. Testing
- 1210. Incident response and data handling
- 13Sign-off
- 14Common mistakes
- 15Frequently asked questions
- 16Next steps
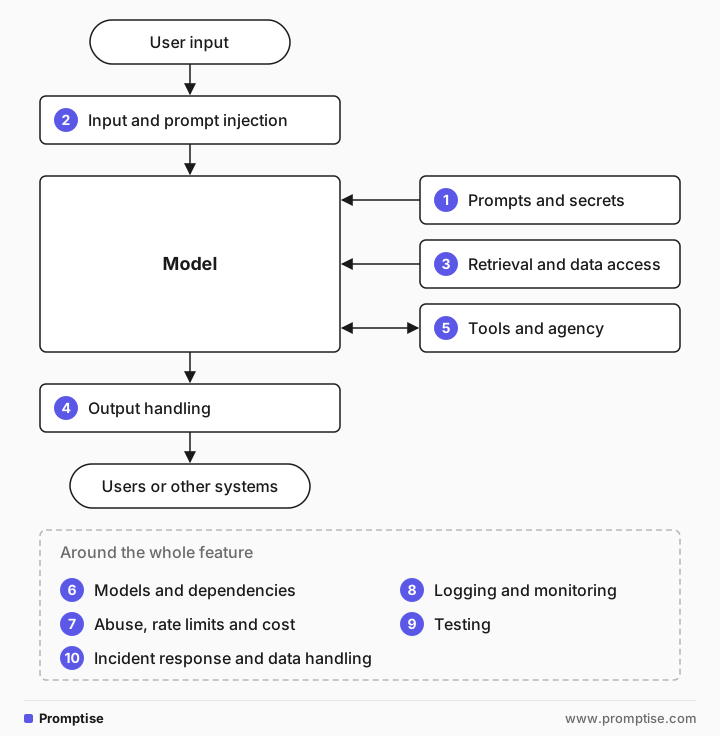
An LLM security checklist is a list of checks a feature must pass before it ships, each with a way to verify it and an owner. This one covers the risks specific to LLM systems: prompt injection, leaked prompts and secrets, unsafe output handling, retrieval and data access, tool permissions, dependencies, abuse and cost, monitoring and incident response. It maps each area to the OWASP Top 10 for LLM applications. It is for engineers and security reviewers signing off an LLM feature or agent.
What should be on an LLM security checklist?
Checks for every place untrusted text enters the model and every place model output is used. That means no secrets in prompts, scanning inputs and retrieved content, filtering retrieval by permission, validating output before it reaches users or other systems, least-privilege tools with approval for irreversible actions, pinned models and dependencies, rate and spend limits, security event logging with alerts, a red-team test set in CI, and an incident runbook. Each check needs a test that proves it passes.
Verify, don't declare. "Prompt injection handled" is not a check. "This probe set runs in CI and no probe leaks the canary" is.
Put the most weight on controls the model can't override: permissions, approval gates, output validation and limits.
Scale with risk. A read-only internal assistant needs a subset. A customer-facing agent that moves money needs all of it.
The checklist doesn't end at launch. Rerun it when the model, prompt, data sources or tools change.
For agent operations (budgets, crash recovery, deployment), use the AI agent production checklist alongside this one.
[02]
How to use this checklist
Copy the checklist into your launch review. For each item, record pass, fail or not applicable with a reason, plus the evidence (a test name, a config file, a dashboard link) and the owner. A failed item on a high-risk feature blocks launch unless someone with authority accepts the risk in writing, with a date to fix it.
Decide the feature's risk level first, because it decides how many items apply:
Risk level | Typical feature | Apply |
|---|---|---|
Low | Internal drafting help; a person reviews every output; no tools | Sections 1, 2, 4, 9 |
Medium | Customer-facing answers, RAG over internal documents, read-only tools | All sections except the approval items in 5 |
High | Agents that act (send, pay, delete, change records), multi-tenant data, decisions about people such as hiring or credit (never by AI alone) | Every item |
The structure follows the OWASP Top 10 for LLM Applications 2025. Sections 8 to 10 add the operational checks that sit outside that list: logging, testing and incident response.
[03]
1. Prompts and secrets
OWASP: LLM07 System Prompt Leakage, LLM02 Sensitive Information Disclosure.
No API keys, passwords, internal URLs or discount codes in any prompt. Verify: grep prompts and templates; run a secret scanner on the prompt repository.
The system prompt is written as if users will read it. Verify: red-team probes that try to extract it; review the extracted text for anything sensitive.
A canary string in the system prompt, checked in every output. Verify: a test that injects the canary into an output and sees the alert fire.
Prompts are versioned and changes are reviewed like code. Verify: prompts live in the repository or a registry with history and review.
Secrets in prompts explains why the system prompt can't keep a secret.
[04]
2. Input and prompt injection
OWASP: LLM01 Prompt Injection.
User input has length limits and is scanned for injection before it reaches the model. Verify: test inputs over the limit and known injection strings are rejected and logged.
Untrusted content (retrieved documents, web pages, emails, tool results) is delimited, labeled with its source and treated as data in the prompt. Verify: prompt assembly code review; a planted-instruction test.
Tool results from untrusted sources are scanned too, not only the user's message. Verify: a test tool returns an injected instruction and the scan catches or flags it.
The scanner fails closed for high-risk features: if a detector can't run, the request is blocked. Verify: disable the detector in a test and confirm the block.
The defenses are explained in Prompt injection 101 and, for agents, AI agent prompt injection defense. If you use Promptise Foundry, one scanner covers input, output and tool results:
from promptise import PromptiseSecurityScanner, InjectionDetector, PIIDetector, CredentialDetector

guardrails = PromptiseSecurityScanner(
    detectors=[InjectionDetector(), PIIDetector(), CredentialDetector()],
    scan_tool_results=True,   # indirect injection arrives in tool results
)                             # fail_open=False is the default
Scanners reduce risk. They don't replace the controls in sections 4 and 5, because no detector catches every injection.
[05]
3. Retrieval and data access
OWASP: LLM08 Vector and Embedding Weaknesses, LLM04 Data and Model Poisoning.
Every indexed source is on an allowlist with an owner and a trust level. Verify: the ingest configuration lists sources; unknown sources are rejected.
Retrieval filters by the user's tenant and permissions in the database query. Verify: a test user asks for another tenant's document and gets nothing.
Secrets and personal data are redacted before indexing. Verify: ingest a test document with a fake key and confirm it is redacted in the index.
Each chunk carries metadata (id, source, trust, tenant, access groups). Verify: inspect stored records.
Retrieved chunk ids are logged per request. Verify: trace one answer back to its chunks.
Details: RAG security and multi-tenant AI agents.
[06]
4. Output handling
OWASP: LLM05 Improper Output Handling.
Output that another system consumes is validated against a schema; decisions use enums, not free text. Verify: malformed outputs are rejected in tests.
Output is never executed or rendered without encoding: no model text into SQL, shell, eval or raw HTML. Verify: code review; tests with output containing <script> and SQL fragments.
Deterministic checks block what must never reach users in this feature (secrets, PII, off-domain links and contacts, prices or codes). Verify: each pattern has a test that blocks.
Generated code runs only in a sandbox with no network and no secrets. Verify: sandbox configuration; a test that tries network access.
See LLM hardening beyond prompting, output verification and code execution sandboxes.
[07]
5. Tools and agency
OWASP: LLM06 Excessive Agency.
The model has only the tools its task needs, and each tool has only the permissions it needs (read-only where possible). Verify: tool list and credential scopes reviewed.
Irreversible or costly actions (send, pay, delete, change access) need approval by a person or a policy the model can't change. Verify: a test call to each such tool waits for approval.
Destinations for outbound data (email recipients, URLs, webhooks) are allowlisted with exact domain matching. Verify: a test send to a lookalike domain is denied.
Tool servers authenticate the agent and enforce authorization themselves. Verify: a call without credentials is rejected at the server.
See human-in-the-loop approval and MCP security best practices.
[08]
6. Models and dependencies
OWASP: LLM03 Supply Chain.
Hosted models are pinned to a dated snapshot, not a moving alias. Verify: configuration shows the snapshot name.
A model or prompt change runs the eval and red-team sets before release. Verify: CI job required on those files.
Python and JavaScript dependencies are locked with hashes and scanned for known vulnerabilities. Verify: lock file in the repository; scanner in CI.
Self-hosted model weights come from a trusted publisher, in a format that doesn't execute code on load, pinned to a revision. Verify: download configuration.
The provider's data retention and training terms are reviewed for the data you send. Verify: a recorded review with the date.
Third-party tool servers are pinned and their tool descriptions reviewed. Verify: version pins and review notes.
More in LLM supply chain security.
[09]
7. Abuse, rate limits and cost
OWASP: LLM10 Unbounded Consumption.
Rate limits per user, per key and per tenant. Verify: a load test hits the limit and gets a clear error.
Input and output token caps per request, and a step limit for agents. Verify: an oversized input is rejected; a looping agent stops.
Spend limits per user and per day with alerts before the limit. Verify: test the alert with a low limit.
Provider API keys are scoped per environment and stored in a secret manager. Verify: no keys in code or images.
See AI agent cost control and per-client rate limiting.
[10]
8. Logging and monitoring
One structured event per model call and tool call with request id, user, tenant, tokens and every guardrail decision. Verify: sample events in the log store.
Prompts and outputs in logs are redacted, access is restricted and retention is set. Verify: log configuration.
Alert rules for probing bursts, canary leaks, blocked outputs after blocked inputs, token spikes and denied tool calls. Verify: each rule fires on a test event.
Alerts go to someone on call, with severity tiers. Verify: a test page reaches a person.
Rules and code: Audit and monitoring for LLM systems.
[11]
9. Testing
A red-team probe set per outcome that must never happen, including indirect injection through documents and tool results. Verify: test files in the repository.
Security probes run in CI on changes to prompts, models, tools and sources, several times each. Verify: required CI job.
Every incident and alert that found a real problem adds a probe. Verify: incident reviews link to the new test.
How to build the set: Red-teaming your own LLM system.
[12]
10. Incident response and data handling
A runbook names the first steps: find the request, decide what got out, contain, fix, add a test. Verify: the runbook exists and on-call has read it.
Kill switches exist and are tested: disable a tool, revoke the agent's credentials, pull a document from the index, switch the feature off. Verify: each one used once in a drill.
You know which personal data reaches prompts, outputs and logs, how long each is kept and where it is stored, and your privacy team has reviewed it. Verify: a recorded review.
Some uses of AI are regulated in some places, so your legal and compliance team has been asked what applies to this feature before launch. Verify: their answer is recorded with a date.
[13]
Sign-off
Section | Owner | Result | Evidence |
|---|---|---|---|
1. Prompts and secrets | Feature engineer | | | |
2. Input and prompt injection | Feature engineer | | | |
3. Retrieval and data access | Data or platform engineer | | | |
4. Output handling | Feature engineer | | | |
5. Tools and agency | Feature engineer and security | | | |
6. Models and dependencies | Platform engineer | | | |
7. Abuse, rate limits and cost | Platform engineer | | | |
8. Logging and monitoring | Platform or SRE | | | |
9. Testing | Feature engineer | | | |
10. Incident response and data handling | Security, legal or privacy | | |
Review the checklist again after launch whenever the model, system prompt, retrieved sources or tools change, and at least every quarter for high-risk features.
[14]
Common mistakes
Mistake | Why it fails | Fix |
|---|---|---|
Checklist items without a test | Everyone marks "done" and nothing is verified | Attach evidence to every item |
Relying on prompt wording for security items | The model can be talked out of it | Prefer permissions, approvals, validation and limits |
One checklist for every feature | Low-risk features drown in work; high-risk ones get a generic pass | Set a risk level first and apply the matching sections |
Signing off once at launch | Model and data changes reopen closed items | Rerun on every change and quarterly |
Treating the checklist as the whole program | It doesn't find new attack types | Combine it with red teaming and monitoring |
[15]
Frequently asked questions
What are the main security risks of LLM applications?
The OWASP Top 10 for LLM Applications 2025 lists prompt injection, sensitive information disclosure, supply chain, data and model poisoning, improper output handling, excessive agency, system prompt leakage, vector and embedding weaknesses, misinformation, and unbounded consumption. Most real incidents combine injection with an output or tool that trusts the model too much.
How do I check if my LLM app is secure before launch?
Set the feature's risk level, go through the applicable sections of this checklist with evidence for each item, run a red-team probe set against the outcomes that must never happen, and confirm that logging and alerts work with test events. Don't launch a high-risk feature with failed items unless the risk is accepted in writing with a fix date.
What is the difference between this checklist and the AI agent production checklist?
This checklist covers LLM security: injection, leakage, output handling, data access, tool permissions, supply chain and abuse. The AI agent production checklist covers running an agent reliably in production, including budgets, crash recovery, observability, evals and deployment. Agents with tools should pass both.
Who should own LLM security sign-off?
The feature team owns most items, because they build the prompts, outputs and tools. Platform or SRE owns limits, logging and dependencies. Security reviews the high-risk items and the overall result, and your legal or privacy team reviews the data-handling items in section 10. Name a person per section.
How often should I review the checklist?
On every change to the model, system prompt, retrieved sources or tools, after every security incident, and on a fixed schedule such as quarterly for high-risk features. Automated tests in CI cover most of the re-checking.
[16]
Next steps
Check agent operations too: AI agent production checklist.
Test the items that matter most: Red-teaming your own LLM system.
Secure retrieval: RAG security.
Build the detection side: Audit and monitoring for LLM systems.
Add guardrails to an agent: AI agent guardrails in Python.
Keep personal data out of prompts and logs: PII detection and redaction for LLM apps.